
Large Language Models (LLMs) are exceptionally good at generating text. We use them to answer questions, write code, reason about problems, and much more. However, not all problems require text generation.
Imagine a customer support system receives the following message:
“I was charged twice for my subscription. I need a refund today.”
The system needs to determine which team should handle the request, how urgent it is, and whether the customer is asking for a refund.
We could prompt an LLM to return a JSON object containing these answers.
llama cli -hf ggml-org/gemma-4-e4b-it-GGUF:Q4_0
> We have the following customer support ticket, "I was charged twice for my subscription. I need a refund today.", which team should handle the request, how urgent it is, and whether the customer is requesting a refund. Give the answers in JSON.
[Start thinking]...[end thinking]```json{  "team_to_handle": "Billing",  "urgency": "High",  "request_refund": true}
But what if the model could directly evaluate the available options and return a probability distribution over them without generating any text?
from transformers import pipeline
decide = pipeline("decision", model="autotrust/GEV-26B-Decide")decision = decide(    {        "state": "I was charged twice for my order and want a refund.",        "questions": {            "department": {                "type": "choice",                "instructions": "Which team should handle this?",                "criteria": {                    "billing": "Payments and refunds",                    "technical": "Bugs and technical issues",                    "sales": "Pricing and subscriptions"                }            },        }    })
# {#   'department': {#       'type': 'choice',#       'choice': 'billing',#       'confidence': 0.9974000453948975,#       'probabilities': {#         'billing': 0.9982666969299316,#         'technical': 0.0010246571619063616,#         'sales': 0.0007087149424478412#       }#     }# }
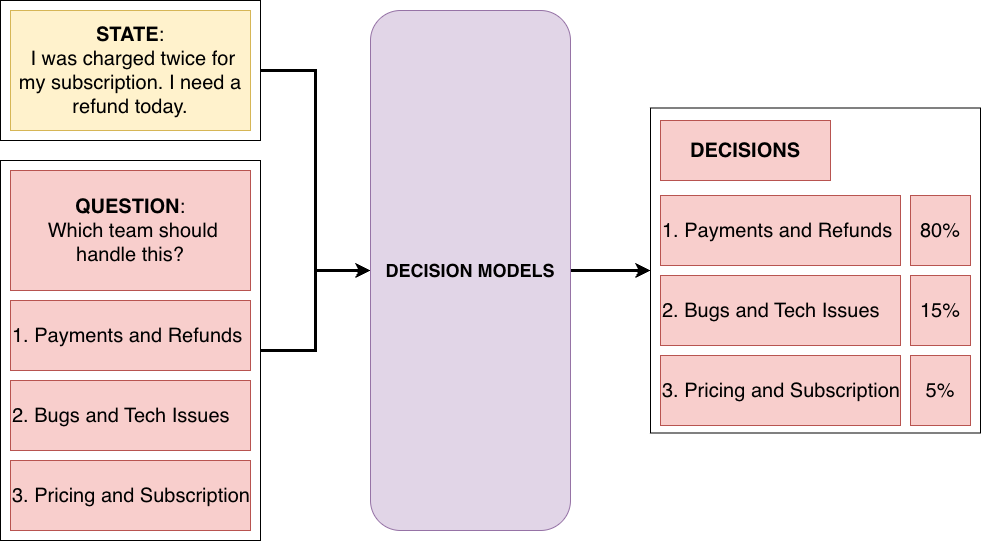
This is the core idea behind decision models.
What Are Decision Models?
A decision model takes some input context (the state), evaluates questions against a predefined set of possible answers (primitives), and returns structured decisions with probabilities. Instead of asking the model to generate an answer token by token, we ask it to assign probabilities to answers that our application already understands.
[ ](https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/blog/de