
Why Do Agents Keep Getting Tripped Up by Their Environment, Even as They Get Stronger?
Make every task the starting point for the next improvement
Your colleague uses an Agent to compile reports, and everything runs smoothly. You use the same model, tools, and workflow, but swap in your own files, and suddenly the Agent keeps re-reading files by trial and error and redoing its work.
The model hasn’t changed, the Harness hasn’t changed. So why does it stop working in a different environment?
A different file location, mixed data formats, or changed template constraints can all make a previously effective method fail. The model provides reasoning ability, and the Harness organizes the execution flow, but the Agent still has to judge: What does this environment look like, and does past experience still apply?
This points to an easily overlooked problem in the continuous self-improvement of Agents: An Agent must learn not only “how to do things” from its tasks, but also determine under which environments that experience remains valid.
In the ongoing optimization process of RSI (Recursive Self-Improvement), an Agent can use task feedback to refine its execution methods and accumulate reusable experience. But if its understanding of the environment isn’t updated in step, experience that once worked can become a new obstacle: the interface conditions have changed, yet it keeps retrying the old call; the data format has changed, yet it keeps applying the old rules.
When a task fails, should you fix the method, or correct the Agent’s understanding of the environment?
A New Problem for Agents, an Old Clue from Cognitive Science
Research in cognitive science on the structure of knowledge offers some insight into how to tell these two kinds of problems apart.
In 1983, cognitive scientist John R. Anderson, in his theoretical work related to ACT-R, systematically discussed two important forms of human knowledge:
- Declarative Knowledge: describes “what the world is like.” For example, a closed container hides the objects inside, and you can only see them after opening it.
- Procedural Knowledge: describes “how to act.” For example, when you need to find multiple objects of the same kind, after finding the first one you should keep checking other possible locations.
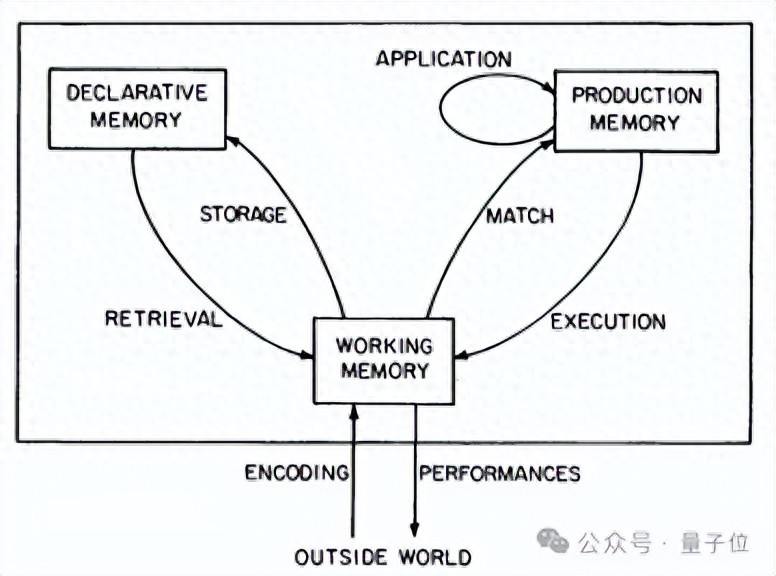
Later, researchers such as Larry Squire confirmed from a neuropsychological perspective that this separation has a biological basis: the two kinds of knowledge are handled by different brain regions, and they differ in learning rate and retrieval mode.
Applying this perspective to Agents, we can see that understanding the environment and mastering how to act are interrelated, yet they require different ways of being verified and updated. Judgments about the environment must be checked against the facts on the ground, while action methods must be tested for effectiveness under the relevant conditions. Conflating the two can lead you to mistake an operation that succeeded by chance for a stable rule, or to keep using a method that has stopped working after the environment changed.
Following this line of thinking, in its continued exploration of RSI, openJiuwen has further proposed TTSE (Two-Track Self-Evolution).
The previously released dual-dimension RSI framework used Harness + Artifacts dual-dimension optimization to let Agents continuously improve their working methods and deliverables based on real task feedback. TTSE goes a step further and focuses on the reliability and reusability of experience itself: it not only lets the Agent accumulate effective execution methods, but also continuously corrects its understanding of the environment, so that experience doesn’t become obsolete when the environment changes.
To this end, TTSE draws on the cognitive-science distinction between declarative and procedural knowledge and divides the experience gained from tasks into two tracks:
- FACT (environment facts): continuously verifies and updates “what this environment is like.”
- TIP (conditional tips): continuously improves “what to do under these conditions.”
The TTSE Two-Track Framework: Building a Feedback-Driven Loop for Self-Evolving Experience
Distinguishing the types of experience is only the first step. How can an Agent keep learning from task feedback and turn effective experience into improvements for the next round of execution?
This is also the core idea of RSI: drive improvement through real task feedback, and keep verifying and optimizing in subsequent execution. TTSE puts this idea into practice at the level of experience management: tasks are executed in batches, so existing experience is continually tested against new evidence. The framework determines which experience is worth keeping and which needs to be revised or retired, then applies the updated experience to the next round of tasks.
The framework consists of four parts: two-track knowledge representation, cold start, online incremental evolution, and final output and evaluation, as shown in the figure below:
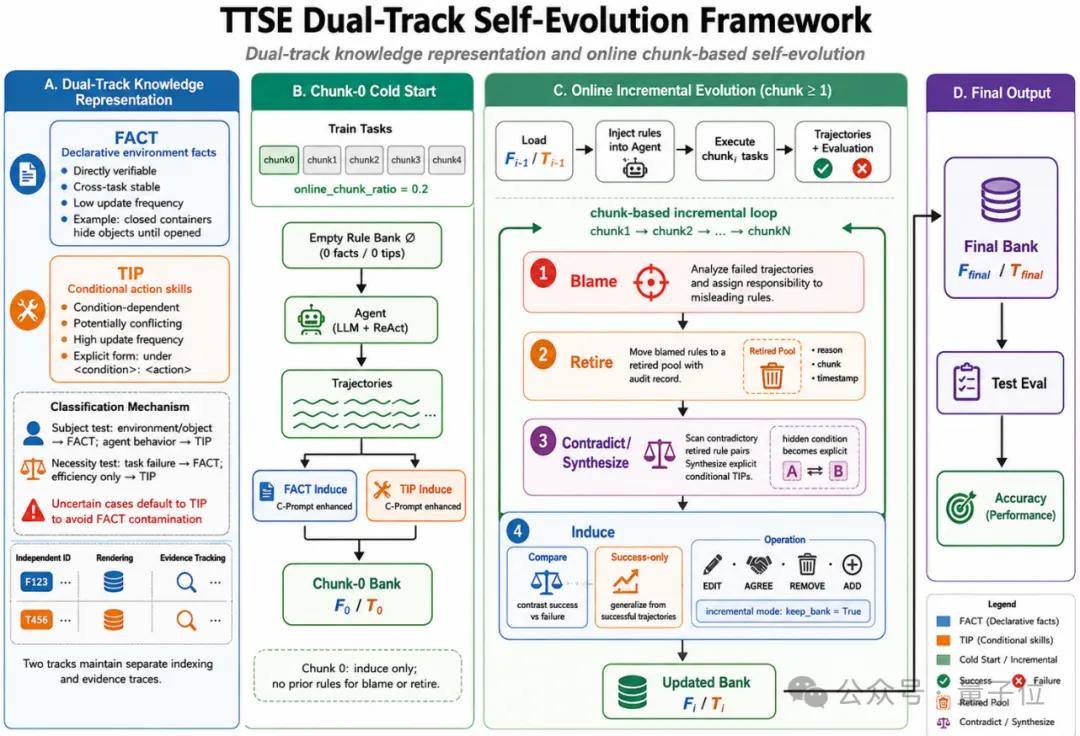
① Two-Track Knowledge Representation: Giving Environment Facts and Execution Methods Their Own Basis
FACT describes the properties and regularities of the environment itself, emphasizing direct verifiability and cross-task stability in applicable scenarios. TIP describes execution methods under specific task conditions, expressed in the form “under what conditions, perform what action.”
The two kinds of knowledge are maintained with separate numbering, presentation, and evidence-tracking mechanisms. This allows each piece of experience to be individually referenced, checked, and updated, and also makes it easier to trace exactly which factual judgment or operational recommendation had an impact when execution goes wrong.
When classifying, the framework judges based on the subject and function of the experience being described. Anything difficult to determine is assigned to TIP by default, which reduces the risk of mistaking insufficiently verified operational experience for an environment fact.
② Cold Start: Inducing Initial Experience from the First Batch of Tasks
TTSE starts from an empty rule base. The Agent executes the first batch of tasks (chunk 0), then induces FACT and TIP separately from the execution trajectories to build the initial two-track experience base.
This stage is primarily inductive. Since no historical rules participate in execution yet, there is no blame assignment or retirement of old rules. Instead, the goal is to establish a first set of experience backed by task evidence for subsequent evolution.
③ Online Incremental Evolution: Testing and Revising Existing Experience on New Tasks
Subsequent tasks proceed in batches. In each round, the Agent loads the FACT and TIP from the previous round, executes the current batch of tasks using that experience, and then, based on execution trajectories and evaluation results, completes four steps in sequence:
- Blame: Analyze failed trajectories and identify rules that may have misled execution, locating the targets for experience revision.
- Retire: Move the blamed rules into a retired pool, keeping records such as the reason, batch, and time so that the adjustment process remains traceable.
- Contradict / Synthesize: Examine contradictions among retired rules, try to identify the applicability conditions implicit in them, and synthesize seemingly conflicting experience into TIPs with clearer conditions.
- Induce: Compare successful and failed trajectories, or extract effective experience from successful ones, and update the two-track experience base through operations such as adding, revising, confirming, and removing.
Blame → Retire → Contradict/Synthesize → Induce runs in a loop across multiple task batches, so that experience is continually tested against new evidence: it both updates the understanding of the environment and adjusts the execution methods under the corresponding conditions.
④ Final Output and Evaluation: Testing the Practical Gains from Experience Evolution
After multiple rounds of incremental evolution, the framework outputs the final FACT and TIP experience bases and evaluates their impact on accuracy or task performance on test tasks.
The core of this mechanism is that environment facts and execution methods are accumulated separately, each remains traceable, and both are tested and corrected through ongoing execution. Each time the Agent completes a batch of tasks, it can turn new interaction evidence into experience usable in the next round, gradually forming a closed loop from environment interaction to knowledge update to improved action.
But one key question remains: is evolving environment facts and action tips separately really more effective than traditional single-track experience management?
From Mechanism to Evidence: Five Benchmarks Validate the Effectiveness of TTSE Two-Track Self-Evolution
The methodology and experimental results of TTSE are presented in the paper A Two-Track Online Self-Evolution Framework for LLM Agents.
To verify whether the two-track experience mechanism is truly effective, the research team evaluated it on five benchmarks: ALFWorld, ScienceWorld, GDPevo, SOPBench, and PinchBench. Each experiment was independently repeated three times to examine the method’s practical gains and runtime stability.
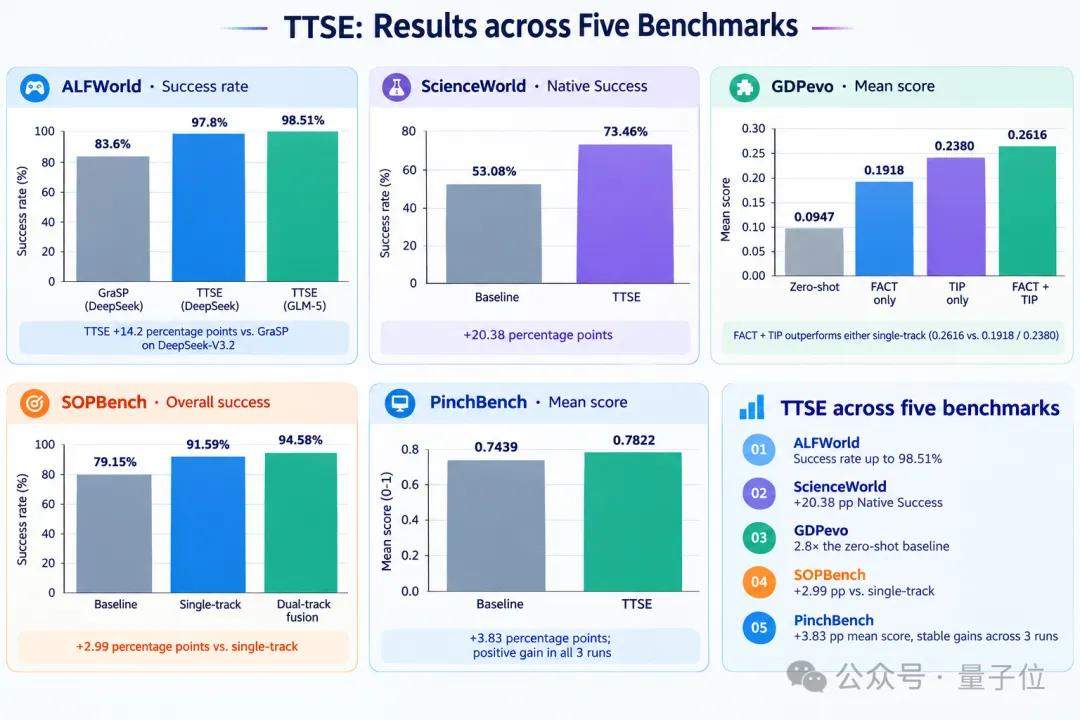
Gains Across Five Benchmarks and Multiple Dimensions
- ALFWorld: success rate up to 98.51%. On GLM-5, TTSE reaches a success rate of 98.51%. On DeepSeek-V3.2, it reaches 97.8%, a 14.2 percentage point improvement over the previous best method GraSP’s 83.6%, while also reducing the number of task execution steps.
- ScienceWorld: significantly improved task performance. MACRO Reward rises from 0.7204 to 0.8534, and Native Success rises from 53.08% to 73.46%, an increase of 20.38 percentage points.
- GDPevo: two tracks outperform one. The full FACT+TIP approach achieves an average score of 0.2616, roughly 2.8 times the zero-shot baseline of 0.0947. Using only TIP or only FACT falls short of the full two-track approach, confirming the value of jointly managing environment facts and action tips.
- SOPBench: further gains when combined with Bayesian skill management. The overall success rate rises from the baseline’s 79.15% to 91.59% with the single-track approach, and the two-track fusion approach reaches 94.58%, another 2.99 percentage points above the single-track approach.
- PinchBench: stable gains on real-world tasks. TTSE was integrated into OpenClaw in a non-invasive manner and run independently three times on 147 real end-to-end tasks. The two-track approach raised the average score from 0.7439 to 0.7822, an increase of 3.83 percentage points. The direction of the gain was consistent across all three runs, and the range across runs also dropped from 3.33 percentage points to 1.61 percentage points.
These results span embodied interaction, scientific reasoning, enterprise operations, industrial processes, and real-world end-to-end tasks, showing that the value of TTSE is not limited to any particular model or single scenario.
Ablation Study: Why Two Tracks Are Necessary
The GDPevo ablation study provides more direct evidence: the full two-track approach outperforms single-track approaches that record only facts or only tips.
The reason is that environmental understanding and action strategy serve different roles. With only FACT, the Agent may know the constraints of the environment but lack suitable ways to act. With only TIP, the Agent may master operational techniques but be unable to accurately identify the conditions under which they hold. Only by combining the two can it answer both “what the environment is like” and “what to do under the current conditions.”
The two-track design is therefore not simply a matter of splitting the experience base into two parts. Instead, it lets different types of knowledge be induced, verified, and reused according to their own semantics and applicability conditions.
From cross-model and cross-task to real-world evaluations, the experimental results not only validate the effectiveness of the TTSE two-track experience mechanism but also demonstrate the potential of RSI at the level of experience learning: an Agent can gradually improve its performance on subsequent tasks, without changing model parameters, by continuously accumulating, verifying, and updating task experience.
This also provides empirical grounding for bringing TTSE from a research framework to real office-agent products.
TTSE Two-Track Self-Evolution Lands in WorkSwarm
TTSE has not only been validated in paper experiments, but has also been officially deployed in openJiuwen’s WorkSwarm, a swarm-based office agent.
Want to try TTSE yourself? Simply install and launch WorkSwarm 0.2.7 or later, turn on the TTSE self-evolution switch in Settings, and you can experience the efficiency gains that come from accumulating and reusing experience.
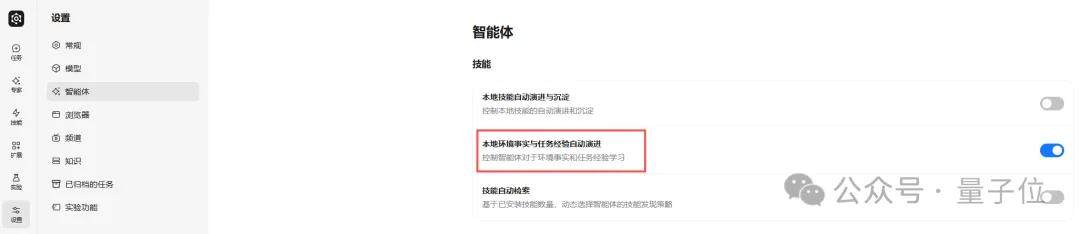
Let’s look at two real office tasks to see how TTSE helps the Agent work faster and more efficiently in practice.
TTSE in Real Office Scenarios: Turning Experience into Efficiency
In everyday office work, Agents are already widely used for tasks such as data cleaning and analysis, document editing and organization, report generation, information extraction, and format conversion. However, when faced with different file structures, data formats, and business requirements, an Agent often has to repeatedly explore the environment, try out tool calls, and work out the execution path anew.
To illustrate TTSE’s real-world effect, the team selected two typical office scenarios, Excel data cleaning and document-and-spreadsheet organization, and compared the Agent’s first run with its performance after experience was injected.
The results show efficiency gains in both scenarios, to varying degrees:
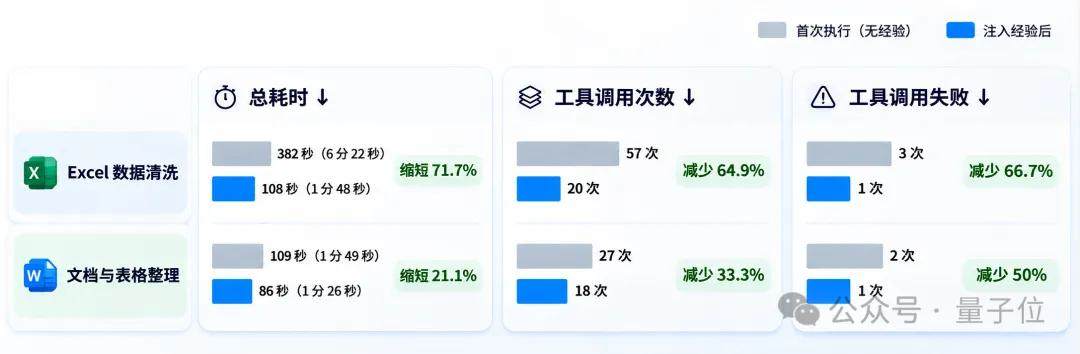
These gains don’t come from any change in model capability. In the comparison tasks shown, the Agent was able to draw on past execution experience to identify environmental constraints faster and choose appropriate ways of handling them.
So what experience did TTSE actually accumulate, and how did it help the Agent reduce trial and error?
Case 1: Excel Data Cleaning — Less Trial and Error in Data Recognition and Processing
The difficulty of this type of task goes beyond cleaning the data. It also involves locating the input file, identifying hidden data-format issues, and determining a deduplication rule that meets business requirements.
On the first run, the Agent had no reusable task experience. It had to explore the input file location, judge the data format, and derive the rule for handling duplicate records on its own. The whole process involved 57 tool calls, 3 of which failed, taking 6 minutes 22 seconds in total.
After the task, TTSE extracted reusable task experience from the real execution trajectory. This experience is no longer just a record of past operations, but a decision basis that can directly influence the next run:
- Quickly locate input materials. When the user doesn’t specify the file location, check workspace/input first and look directly for upstream files, avoiding repeated exploration of irrelevant task directories and saving unnecessary follow-up questions to the user.
- Dig deeper into data problems. For dates, amounts, and text in Excel that look normal, use openpyxl directly to inspect the raw stored values, identifying hidden issues such as text-formatted dates, currency symbols, and trailing spaces, and reducing omissions caused by improper reading methods.
- Reuse a verified deduplication rule. Group by business fields, keep the record with the earliest date, and log the number of deleted records, so the deduplication criteria no longer need to be derived from scratch, cutting down on repeated judgment and trial and error.
When a similar task was run again, this experience directly informed tool selection and processing decisions. Tool calls dropped to 20, failed calls dropped to 1, and total time was reduced to 1 minute 48 seconds.
Case 2: Document and Spreadsheet Organization — Less File Exploration and Format Trial and Error
Unlike Excel data cleaning, the main difficulties in this type of task are unknown file locations, unclear CSV encodings and delimiters, and complex Word template structures. On the first run, the Agent had to explore files step by step, identify formats, and determine a suitable way to handle the template.
In the document and spreadsheet organization task, the Agent’s first run took 1 minute 49 seconds, with 27 tool calls and 2 failed tool calls. After the task was completed, TTSE accumulated a set of environment facts and operational tips from the real execution trajectory.
On the second run, the Agent no longer had to explore the file directory from scratch or probe how to read the CSV, nor did it have to wait until after the document was generated to discover template replacement problems. It could directly reuse verified environmental experience and choose more suitable tools and processing paths up front.
The second run took 1 minute 26 seconds, with tool calls down to 18 and failures down to 1. Overall time dropped by about 21.1%, tool calls fell by 33.3%, and failed calls fell by 50%.
Rather than simply remembering which operations were performed in the past, TTSE goes a step further, letting the Agent accumulate both an understanding of the environment and execution methods that work under specific conditions.
Going from accumulated experience to improved capability depends on reusing it correctly.
The two office cases demonstrate the value of TTSE in practical tasks: the Agent doesn’t have to explore from scratch every time, but can turn experience verified as effective in past tasks into a reference for later execution.
This is exactly the kind of continuous improvement RSI aims to achieve: every task execution produces not only deliverables, but also an opportunity to accumulate useful experience for the next one. Through its two-track FACT and TIP mechanism, TTSE makes this accumulation of experience more verifiable, updatable, and reusable.
But do these gains exist only in specific tasks, or can they be seen across a broader range of office tasks?
TTSE Delivers Comprehensive Gains on an Office Benchmark
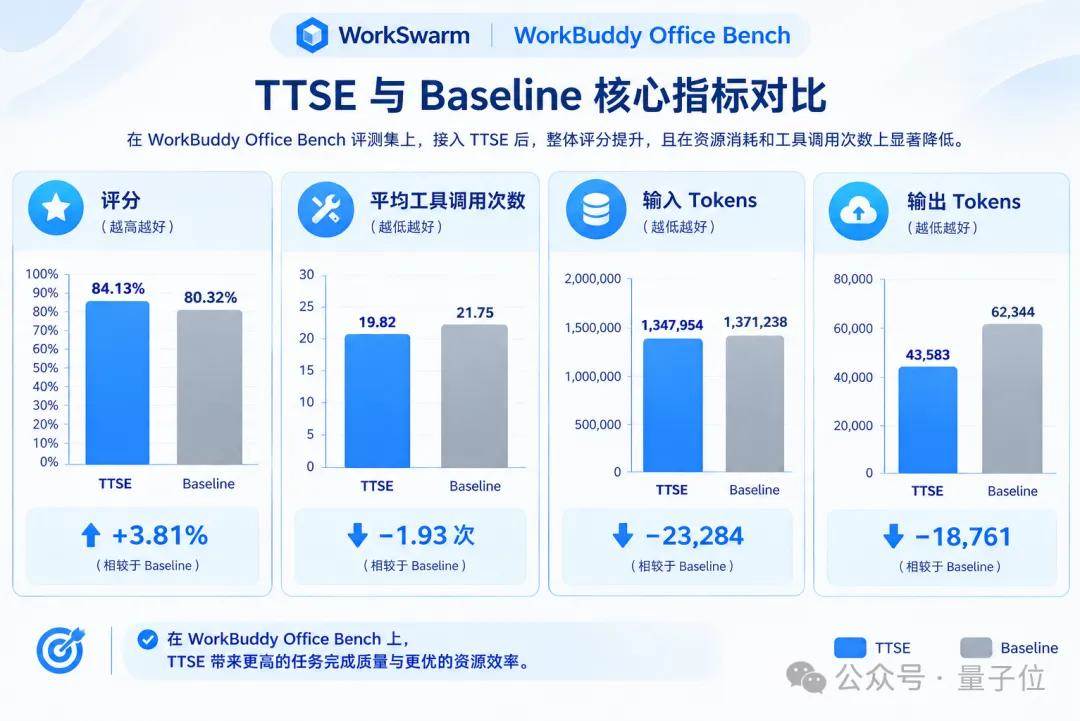
To further evaluate TTSE’s performance in comprehensive office scenarios, the team tested TTSE-enabled WorkSwarm on WorkBuddy Office Bench, an open-source industry leaderboard.
TTSE not only improved task performance but also effectively reduced token consumption and tool-call overhead. The evaluation results show that, compared with the native baseline, task performance improved by 3.81%, input token consumption dropped by 1.70%, output token consumption dropped by 30.09%, and the average number of tool calls fell by 2.
Final Thoughts
We are at a turning point where Agents are moving from “one-off tools” to “continuously evolving partners.”
The core value of RSI is not just letting Agents complete more tasks, but enabling them to gain feedback from every real execution, accumulate experience, and turn that experience into the capacity for continuous improvement.
From the dual-dimension optimization of Harness and Artifacts to TTSE’s two-track evolution of environment facts and execution tips, openJiuwen is exploring different paths toward agents that continuously improve themselves: optimizing working methods and deliverables while also constantly correcting their understanding of the environment and accumulating reliable experience.
TTSE provides a verifiable, traceable mechanism for self-evolving experience, so that an Agent learns not only “how to do things” but also understands “under what environment doing it this way is effective,” and keeps refining itself through each task execution.
Experience shouldn’t be fleeting. Teaching an Agent not just “how to do things” but, more importantly, “what the world is like” is the first lesson on its path to long-term autonomy.
Academic paper: TTSE: A Two-Track Online Self-Evolution Framework for LLM Agents
Full paper: https://arxiv.org/pdf/2609.24289