
All rise! A year and a half later, NVIDIA’s next-generation robot foundation model has finally arrived!
Just now, at this year’s CoRL conference in Austin, NVIDIA GEAR co-leads Yuke Zhu and Jim Fan unveiled their next-generation World Action Model—
GR00T 2.
In the 90-second official demo, GR00T 2 can use scissors to cut tags, install graphics cards, strike matches, slice bananas to make breakfast, wipe up spilled coffee, bus tables, and sell popcorn.
Watching it in action, it is practically an all-rounder. From fine-grained bimanual manipulation to whole-body locomotion, the model’s task scope covers nearly every dimension of robotic capability.
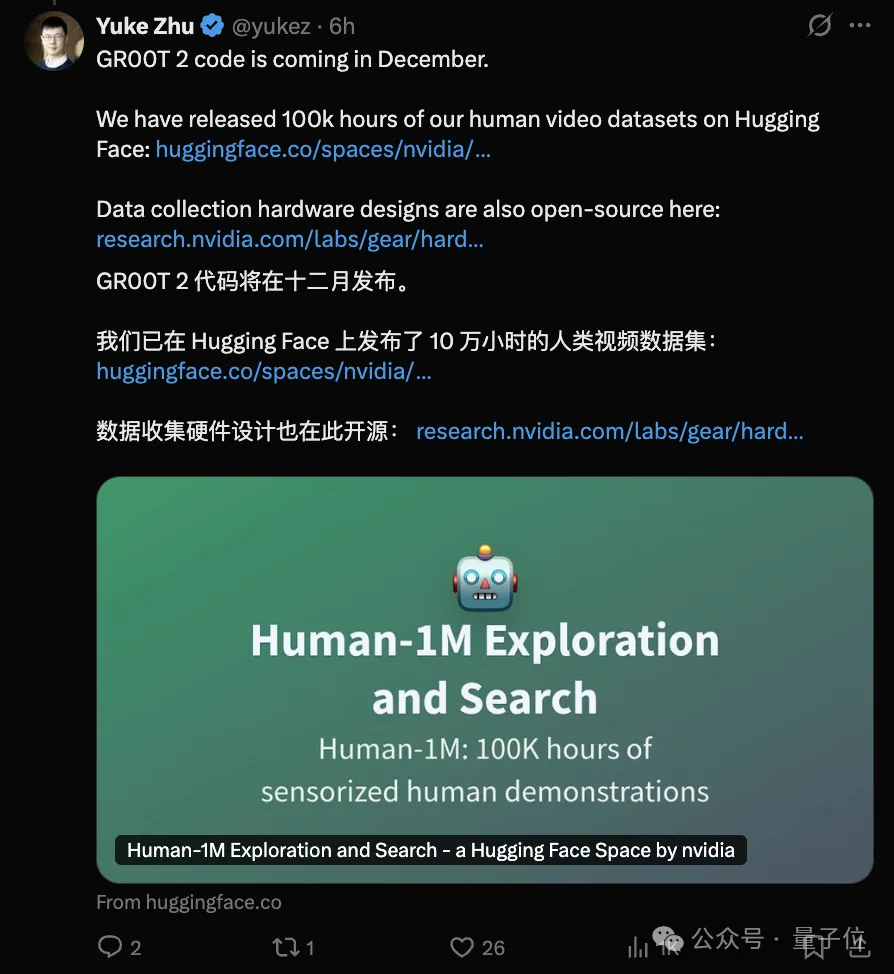
Furthermore, according to Yuke Zhu, the models, datasets, simulation environments, and data collection hardware for GR00T 2 will be progressively open-sourced.
Currently, 100,000 hours of human data have already been released in the first batch.
Is it too much to ask everyone to give a massive shout-out to NVIDIA for this?
GR00T 2: Scaling Generalization, Dexterity, and Adaptability in Robot Foundation Models
As a World Action Model, GR00T 2 can simultaneously predict future visual frames and robot actions. During training, it jointly learns “how the world will change” and “how the robot should act.”
During the keynote, Jim Fan positioned it as a System 1 (fast-thinking) physical skill model that reacts quickly, runs locally, and is both easy to teach via demonstrations and easy to guide using reasoning models.
Looking inside GR00T 2, this comes down to what Yuke Zhu referred to on X (formerly Twitter) as X-Adapt (cross-embodiment adaptation).
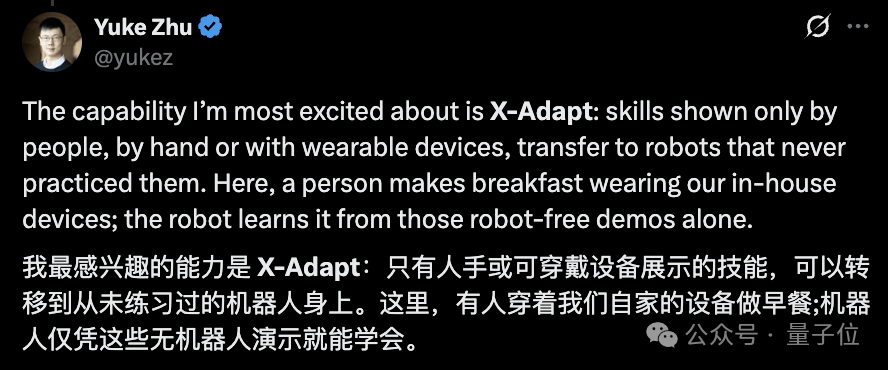
Simply put, teaching a robot a new task in the past typically required collecting a fresh batch of robot demonstration data tailored to its specific physical morphology and control scheme.
X-Adapt attempts to break through this limitation: skills demonstrated by humans or handheld devices can be directly transferred to robots that have never practiced the task.
Specifically, NVIDIA demonstrated three pathways:
1. Transferring from human demonstrations to robots.
Researchers wore motion-capture equipment to demonstrate how to place and wet filter paper. Subsequently, Dexter—a dual five-fingered dexterous hand setup—was able to complete the exact same task.
Throughout the entire process, no robot teleoperation demonstrations were collected for this specific task. Relying solely on human demonstrations, Dexter achieved a 65% success rate across 20 trials.
2. Transferring from handheld grippers to robotic arms.
Researchers used handheld UMI grippers to demonstrate how to assemble a toy dump truck. Once the model learned the skill, it transferred it to YAM robotic arms.
Even though the UMI and YAM grippers have different morphologies, YAM was still able to complete the assembly task end-to-end—taking up to four minutes—with a 60% success rate.
This same transfer pathway was also applied to tasks such as conveyor belt sorting and tossing, as well as control panel disassembly.
3. Transferring from wearable exoskeletons to dexterous robotic hands.
Researchers wore DexUMI hand exoskeletons to demonstrate making banana yogurt and scooping cereal.
After fine-tuning the model with this data, the robot was able to take over and complete the breakfast task—again, without requiring any additional robot teleoperation demonstrations for the task.
In summary, all three pathways point to the same paradigm shift: the same skill no longer needs to be re-demonstrated on every single type of robot.
Of course, cross-embodiment transfer doesn’t mean robot data is completely unnecessary.
In the human motion-capture and UMI pathways, the target robot still provides task-agnostic data so the model can familiarize itself with the robot’s physical structure, kinematics, and control space; meanwhile, demonstrations for new tasks can come from human operations, which are much easier to collect.
This aligns with the core focus emphasized in the GR00T 2 technical report: scaling generalization, dexterity, and adaptability in robot foundation models.
Beyond skill transfer, GR00T 2 also demonstrated the ability to boost execution precision using just a handful of robot demonstrations.
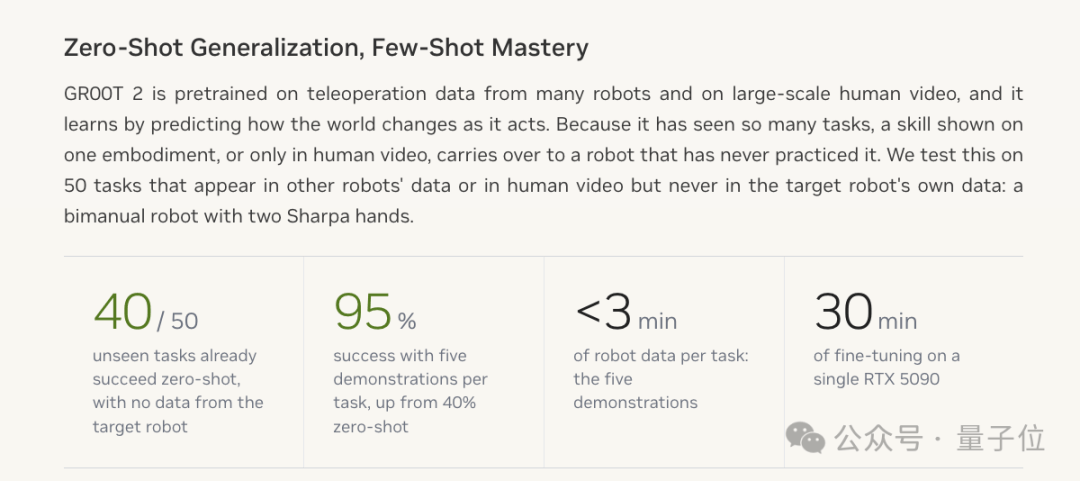
In another set of Dexter-50 evaluations, the model achieved a zero-shot average success rate of 40%; with just one demonstration per task, the success rate jumped to 71%; with five demonstrations, it reached 95%.
More importantly, those five demonstrations took less than three minutes in total. Following that, it only takes about 30 minutes of LoRA fine-tuning on a single RTX 5090 to produce a model adapted to the corresponding task.
In terms of practical deployment, NVIDIA is also keeping pace with industry trends by opening up the WAM API.
Through the API, reasoning models can handle task decomposition and monitor execution progress, while delegating specific physical skills to GR00T 2 for execution.
In other words, GR00T 2 can not only execute skills on its own, but also serve as a physical execution module called upon by higher-level agents.
Which begs the question: NVIDIA, how are you this good?
How Do 400,000 Hours of Human Video Turn into Robotic Dexterity?
Let’s break it down step by step. Behind X-Adapt lies a massive data pyramid. The pre-training of GR00T 2 blends three categories of data:
- 402,730 hours of egocentric human video;
- 10,184 hours of handheld UMI demonstrations covering 2,897 tasks;
- 23,500 hours of robot teleoperation data.
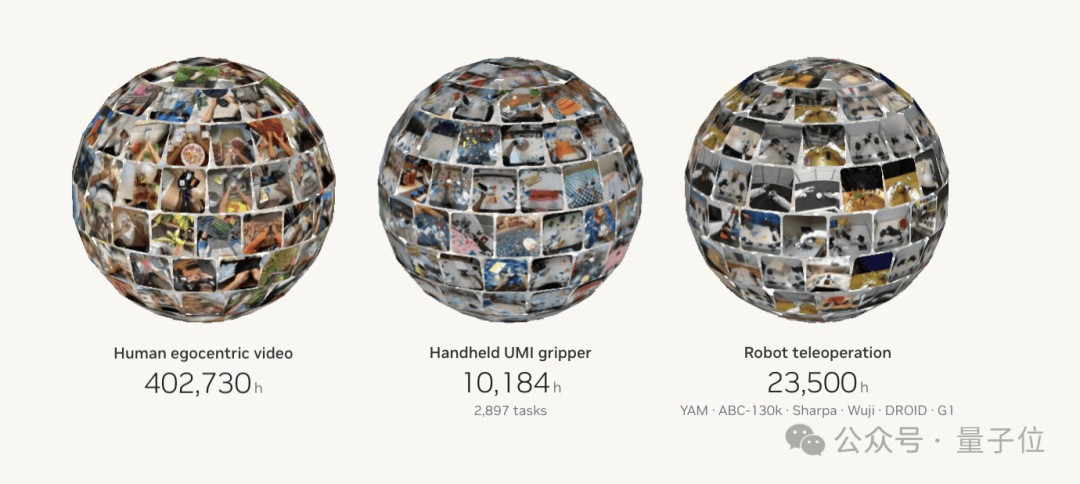
It is easy to see that the scale of human video dwarfs the other two categories. This means that a robot’s learning material is no longer confined to action trajectories collected via manual teleoperation, expanding instead to encompass vast amounts of real-world human activity:
How humans pick up tools, move objects, complete assemblies, and how the surrounding scene changes following an action.
UMI and wearable devices supplement this with more direct manipulation trajectories, while robot teleoperation data helps the model learn the kinematics and control schemes corresponding to different physical embodiments.
To verify whether human videos can genuinely help robots get work done, the team conducted a dedicated scaling experiment.
They trained models using datasets containing 0%, 1%, 10%, and 100% of the human videos, and then evaluated them across 72 Dexter tasks.
The results showed that as the volume of human video data increased, the average task progress on physical robots rose from 50% to 70%.
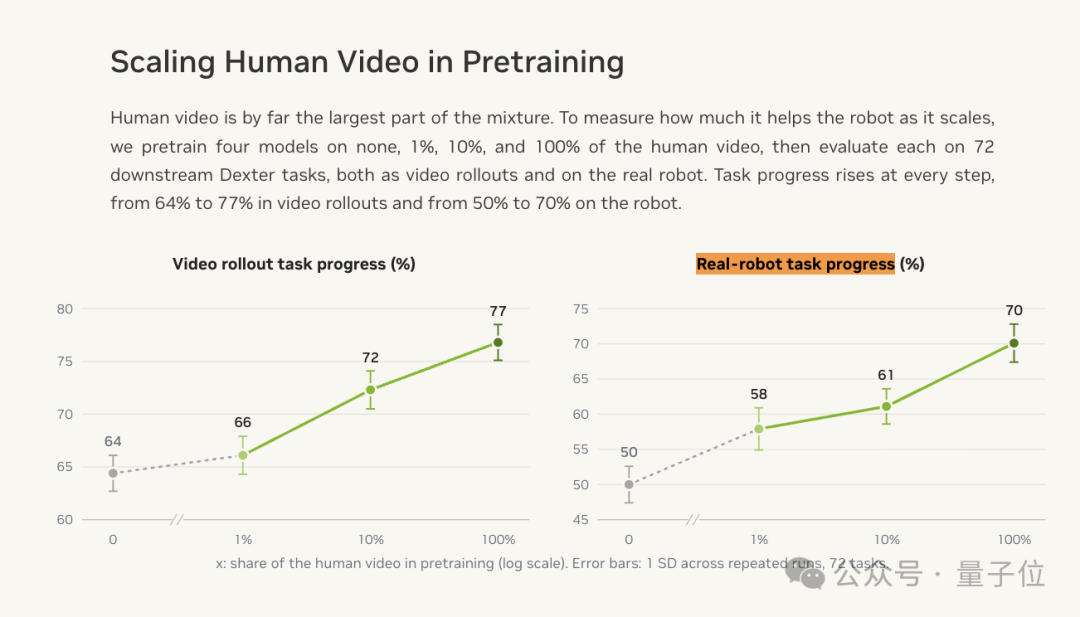
This set of experiments provides a pretty straightforward answer: large-scale human experience doesn’t just enrich a model’s visual knowledge—it also translates into tangible execution progress on real-world robotic tasks.
To digest all this data on the modeling side, GR00T 2 takes in language instructions, multi-view camera feeds, and robot states, using a unified Diffusion Transformer to jointly predict future video frames and action sequences.
Finally, centered around GR00T 2, NVIDIA is connecting data collection, processing, training, simulation verification, and real-world deployment into a complete end-to-end toolchain.
On the collection side, there are devices like UMI and DexUMI. They allow researchers to directly record human manipulations, especially dexterous movements that are difficult to perform naturally via traditional teleoperation.
On the data side, there are Human-1M and Flora. The former provides egocentric human videos, with the first subset of 100,000 hours already made public; the latter supports data curation, descriptive annotation, and automated evaluation.
On the simulation side, there is SimFoundry. It can reconstruct task environments from real-world scenes for policy testing, data generation, and skill development.
On the execution side, workloads are divided among different models and components.
ASPIRE orchestrates robot models and code skills to support task execution and error recovery. Tailored for humanoid robots, Turbo uses a lighter network and more compact video representations to reduce prediction overhead.
On the G1’s onboard Jetson Thor, a single prediction with Turbo takes 124 milliseconds; meanwhile, SONIC runs on a separate Jetson Orin, handling whole-body control at 50Hz.
The former generates motion plans, while the latter translates those plans into continuous physical actions, allowing the robot to maintain coordination while reaching, bending, and carrying objects.
As a result, once developers get their hands on GR00T 2, they can not only call the model itself, but also use the accompanying toolchain to collect their own data, adapt to their own tasks, verify skills in simulation, and ultimately deploy them onto physical robots.
This is the most noteworthy aspect of NVIDIA’s release: what it is opening up is no longer just a single robot model, but an entire development ecosystem spanning data collection, model training, skill invocation, and physical execution.
One more thing
During his live keynote at CoRL, Jim Fan remarked:
“Astra didn’t shatter our dreams; what it shattered were our walls.”
“This is not a winter; this is the summer of robotics.”
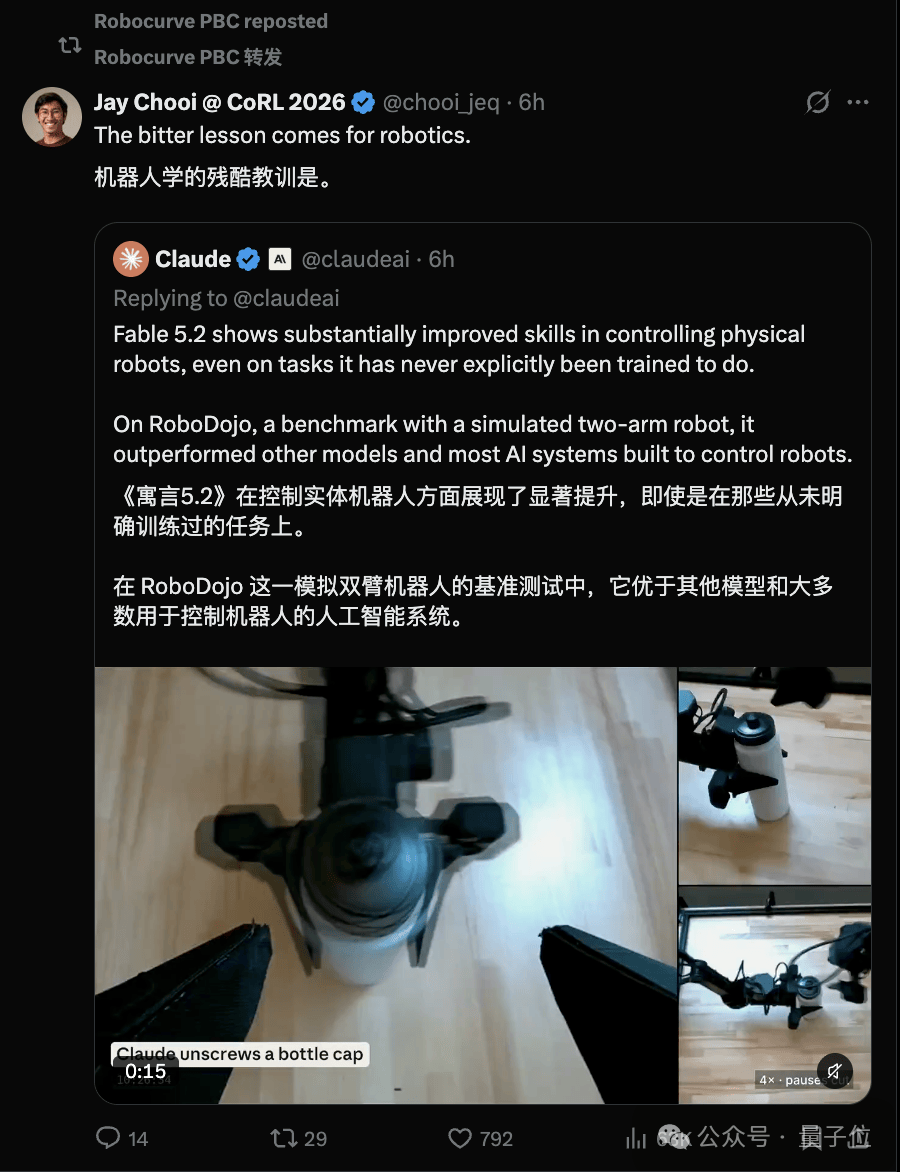
While that certainly sounds inspiring, Claude Fable 5.2, which was released today, put on a performance on RoboDojo that honestly feels like it’s schooling the robotics field.
In the RoboDojo Sim bimanual benchmark released by Anthropic—using the exact same runtime framework and the highest available reasoning effort for each model—Fable 5.2 scored 64.9%, while GPT-6 Astra scored 29.8%.
Say, for the next meetup, how about Team LLM and Team Embodied AI sign up for a head-to-head showdown?
References
[1]https://research.nvidia.com/labs/gear/gr00t-2/
[2]https://research.nvidia.com/labs/gear/gr00t-2/assets/gr00t2_whitepaper.pdf