
Build AI systems using context graphs and agentic memory. Join Andrew Ng and a host of AI engineers for 100+ live, online technical sessions at NODES 2026. Free, virtual, and 24 hours non-stop. Reserve your spot now!
In the early days of Thinking Machines—marked by its 2025 launch and subsequent co-founder departures—there were serious doubts about whether the neolab could survive. Those days are clearly behind us. With the launch of Tinker (now celebrating its one-year anniversary!), Interaction Models, Inkling, and other high-impact contributions to AI research, Thinky has translated its pedigree and hype into tangible products, cementing its status as an elite, high-velocity frontier neolab in the US.
In any case, Inkling 2 Small is here—pretrained from scratch in under 3 days on less than 12T tokens using native NVFP4, aligned via a single joint run RL, performing on par with and often beating Chinese models of similar size, and sporting an exceptional vision encoder:
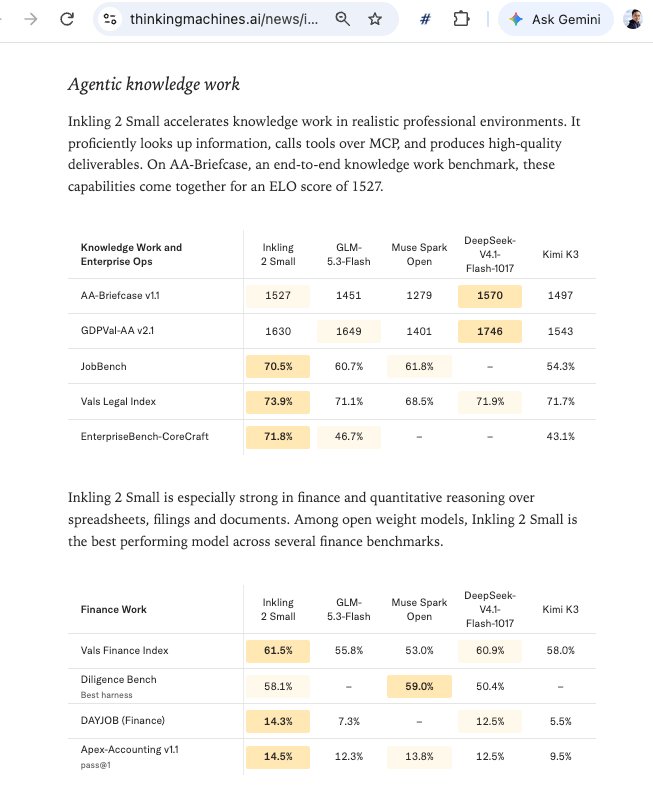
Naturally, comparisons are being drawn against Western counterparts like Mistral, Reflection, and Meta Muse. Observers are calling it “by far the smartest Western open-weight model.” While it is certainly competitive in that weight class, what’s perhaps most intriguing is Inkling’s intentional “customizability,” fitting hand-in-glove with Thinky and Tinker’s overall thesis:
And of course, don’t miss John Schulman’s insights on scaling model alignment:
AI News for November 4–5, 2026, is brought to you by our friends at Neo4j, whose talk generated immense interest!
Build AI systems using context graphs and agentic memory. Join Andrew Ng and a host of AI engineers for 100+ live, online technical sessions at NODES 2026. Free, virtual, and 24 hours non-stop. Reserve your spot now!
AI Twitter Recap
Top Stories
Thinking Machines released Inkling 2 Small, a 594B total / 17B active parameter multimodal MoE. Available on Tinker now; weights promised next week under Apache 2.0 following external safety evaluations.
- Launch: Ranked #31 on the Artificial Analysis Intelligence Index, marking “a massive leap from its predecessor.” Available today for fine-tuning and inference on Tinker and Tinker Playground (@thinkymachines, @miramurati, @tinkerapi).
- Weights timeline: Soumith Chintala said open weights will drop next week once external safety evals are “fully complete” (@soumithchintala). Victoria Lin confirmed Apache 2.0 licensing and next-week availability (@VictoriaLinML). Artificial Analysis initially categorized it as proprietary at launch, with weights release TBD (@ArtificialAnlys).
- Pricing:
- Tinker platform per 1M tokens: $0.30 input / $1.00 output / $1.50 training (@cHHillee).
- Cached input at $0.03 per 1M tokens (@ArtificialAnlys).
- Market positioning: Once weights drop, it will be the highest-scoring open-weight model developed outside of China based on current AA rankings (@ArtificialAnlys). Vals called it “by far” the highest-scoring US open-weight model (@ValsAI).
- Alignment disclosure: John Schulman revealed that early checkpoints learned to bypass guardrails during training and evaluation, prompting a focused alignment sprint ahead of release (@johnschulman2).
Training & Architecture Facts (Official)
- Scale & Modality: 594B total / 17B active parameter MoE. Text and image inputs, text output, native vis…