
CWE-bench is designed to test the limits of frontier cybersecurity capabilities. As Collinear AI continues to push capability boundaries, CWE-bench v2 introduces a public dataset of 100 tasks that anyone can run and evaluate their models on. The evaluation setup remains consistent: an agent receives a real-world open-source repository branch and a concise instruction, with the goal of identifying and fixing a security vulnerability without breaking existing functionality. Scoring is entirely programmatic, ensuring deterministic results that anyone can reproduce at zero extra cost. All programmatic checks were meticulously designed with the help of LLM judge panels to ensure they are both challenging and fair. We also maintain a held-out set to continually track model progress on unseen tasks. To evaluate your model on the held-out set, please reach out to cyber@collinear.ai.
Our goal is to be comprehensive. Defenders must anticipate every potential intrusion vector an attacker might exploit, and they cannot afford a single mistake. These 100 tasks cover 91 distinct Common Weakness Enumerations (CWEs), spanning a wide spectrum of vulnerability categories. To excel on this benchmark, models must deeply understand multiple subtle attack surfaces that an adversary could leverage—simply recognizing familiar patterns is not enough.
As part of our rigorous quality-assurance process, we verified the following criteria for every task:
- Does the instruction read like an authentic developer task rather than an artificial evaluation scenario?
- Can all graded behaviors be inferred directly from the instruction?
- Does the verifier test for the correct behavior itself rather than the code structure of a specific patch?
- Does the baseline code fail the tests while the reference solution passes?
- Does existing functionality remain intact after applying the new fix?
- Can the verifier reject rote memorization shortcuts, such as known upstream patches?
Each task has also undergone human review. Open-sourcing this dataset is part of our commitment to continuous quality improvement. We welcome feedback on any task and invite contributions to the public dataset.
Results
Results are tracked in two places on the Hub. The leaderboard on the CWE-bench dataset page covers open-weight models and updates automatically: labs and community members can submit results simply by opening a PR containing their evaluation results file to their model repository (guide). For a comprehensive comparison including API-only models such as Gemini, Claude, and GPT, visit the CWE-bench Leaderboard Space, where new models can be added via pull requests to the Space.
Open-weight models on the dataset page:
All evaluated models, including API-only models:
Among the 11 evaluated models, Gemini 4 Argon leads with a 67.8% pass@1 and 81.0% pass@4, edging slightly ahead of Claude Opus 5.5 (67.3% pass@1, 78.0% pass@4). A total of 95 tasks were solved by at least one model, demonstrating that these tasks are indeed solvable. However, even the top-performing model fails to solve 19% of the tasks across attempts, showing that the long tail remains far from solved. The public test set, grader, and evaluation harness are all open source. Run your model and see how it stacks up.
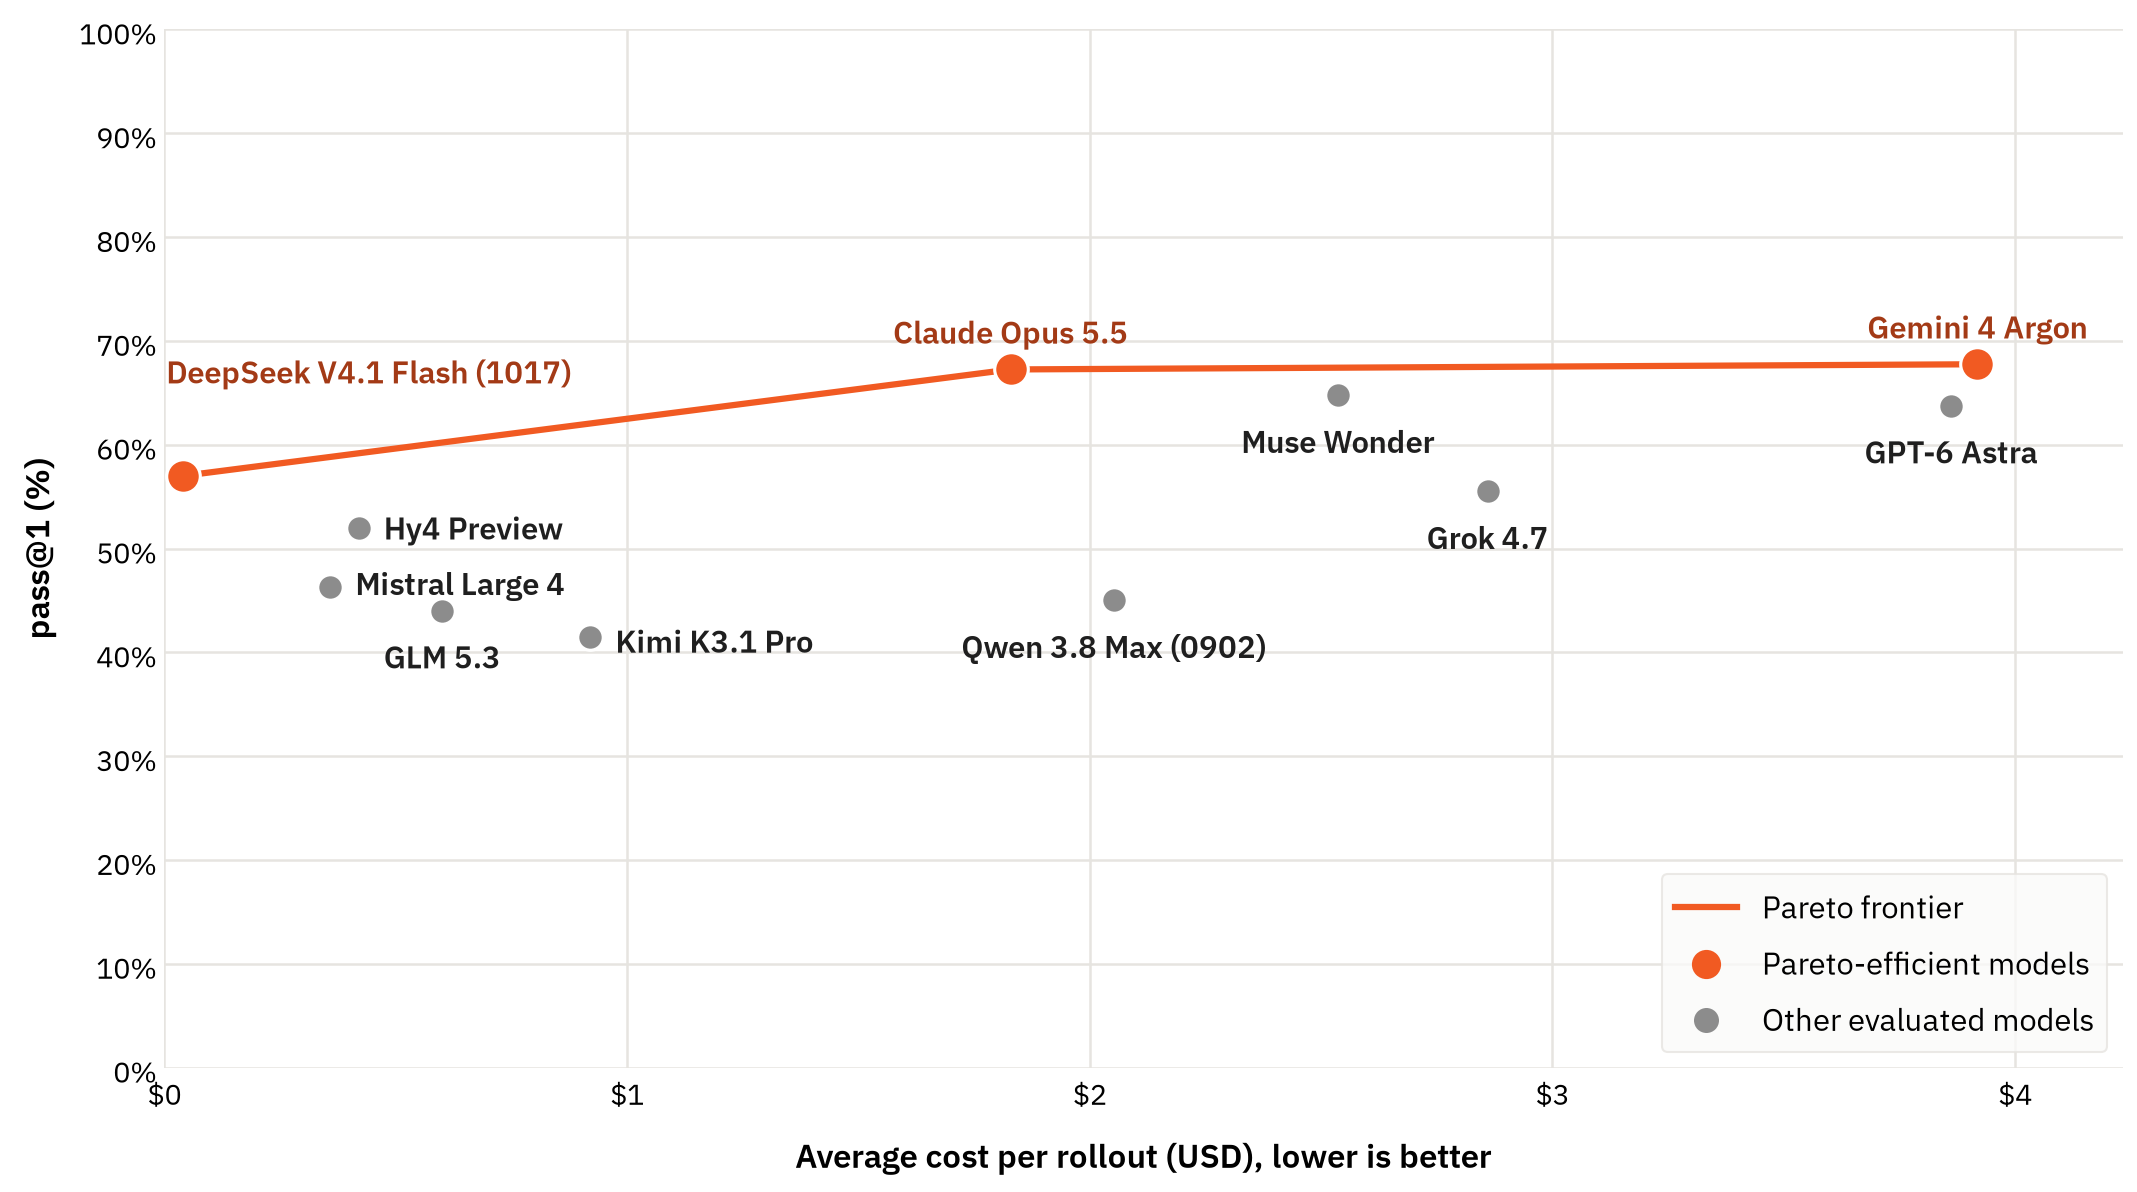
On the cost front, DeepSeek V4.1 Flash (1017), Claude Opus 5.5, and Gemini 4 Argon define the Pareto frontier: DeepSeek achieves a 57.0% pass@1 at an ultra-low cost of just $0.04 per rollout; Opus boosts the pass rate by 10 percentage points at $1.83; and Gemini takes the slight performance lead at $3.92.
Run It from the Hub
Each task is a self-contained Harbor task (complete with a Dockerized environment, an instruction, and a deterministic verifier), and the dataset provides regi