
NVIDIA and MIT Team Release Model Weights for Open-H3-Regenerate-2K Video Enhancement Project on Hugging Face
Recently, the Efficient-Large-Model team, comprising researchers from NVIDIA and MIT, released the model weights for the video enhancement project Open-H3-Regenerate-2K on Hugging Face, with inference code open-sourced in the NVlabs/Sana repository. Based on MiniMax H3, this solution regenerates low-resolution draft videos into high-resolution videos, supporting 2K output at 2560×1440 and native 4K reconstruction up to 3840×2160.
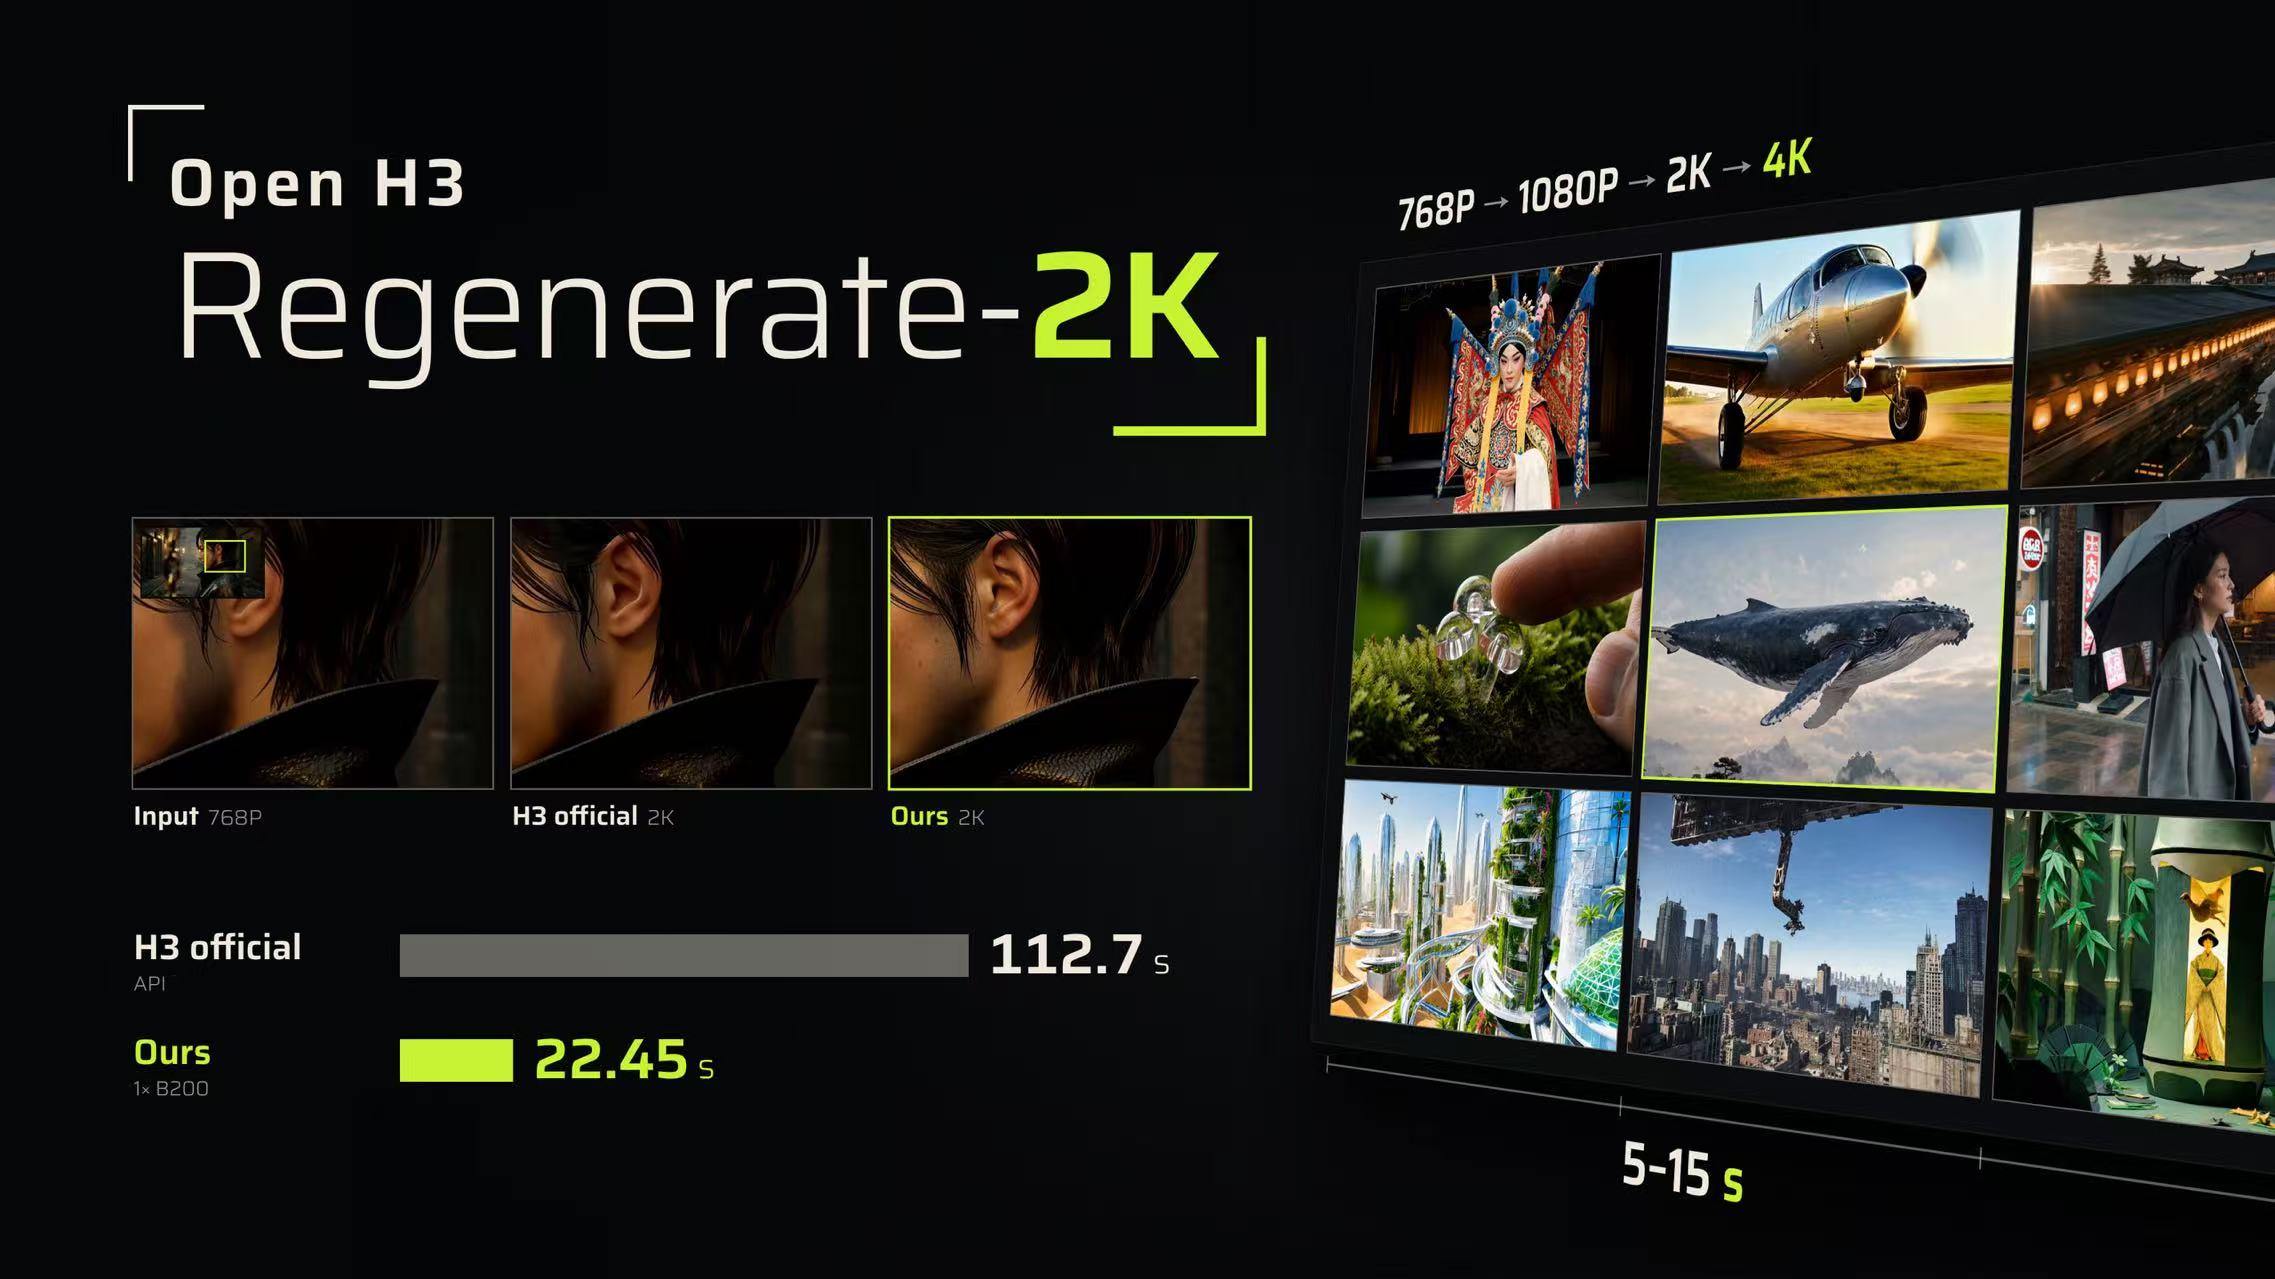
The complete MiniMax H3 system encompasses multimodal context processing, foundational audio-video generation, and high-resolution regeneration. Among these components, the open-weight H3-Base handles 768P audio-video generation, while the official H3-Regenerate-2K module is served via API. This newly released project leverages the generative capabilities of the H3 base model to offer an open, locally deployable implementation for high-resolution regeneration.
During the training phase of the refiner model, the research team froze the original parameters of the H3 Transformer backbone and the video VAE, training only the newly added refiner LoRA. During inference, this refiner LoRA is merged with community adapters such as LightX2V FL2VA Turbo and LMS Sharp to regenerate visual details at the target resolution via 3-step denoising. Scene, layout, and motion cues from the draft video serve as priors guiding the process.
To enhance inference efficiency, the project employs a community-developed latent upscaler to upscale the video’s latent representations directly, avoiding the overhead of repetitive encoding and decoding at high resolutions. Additionally, it integrates SoL-Engine’s sparse attention mechanism, low-precision computation, and a fast VAE decoder, delivering end-to-end acceleration across both refinement and decoding stages.
Benchmarks published by the team demonstrate that under warm-up conditions on a single NVIDIA B200 GPU, the total processing time for a ~5-second video—covering latent upscaling, 3-step refinement, and 2K decoding—dropped from 87.26 seconds in the unoptimized version to 22.45 seconds, representing an approximately 3.9× speedup. Notably, the fast decoder compressed the video decoding time from around 15 seconds down to roughly 1.6 seconds.
In terms of visual quality, the team conducted comparative evaluations on the RefinerBench-150 benchmark. Given identical inputs and 2K outputs, Open-H3-Regenerate-2K scored an average of 60.0 on the UniPercept perceptual quality evaluation, surpassing the official H3-Regenerate-2K API’s score of 53.4. On VBench, this solution demonstrated superior scores in aesthetic quality, imaging quality, and subject consistency, while the official API retained a slight edge in motion smoothness and dynamic degree.
Since MiniMax H3 went open-weight in August this year, fine-tuning, distillation, and tooling integrations around it have expanded rapidly, attracting numerous research teams and community developers worldwide. Surpassing 24 million downloads in its first month and spawning over 300 public derivative models, it has become one of the most downloaded models globally in 2026.
Among these efforts, the joint NVIDIA and MIT research around H3 spans multiple application domains. Beyond this video enhancement solution, the team previously released StreamRender-H3, a streaming video rendering model built on H3 Ref2VA, and Sol-H3-VAE, a fast decoder distilled from the H3 video VAE, providing dedicated support for interactive video rendering and decoding efficiency optimization, respectively.
Previously, LightX2V introduced MiniMax-H3 Turbo offering 4-step and 8-step distilled variants, while the community fine-tuned model Singularity focused on optimizing motion performance, facial details, and visual styling. Teams abroad such as FastVideo and Pika have also released the FastH3 4-step preview and the 6-step sampling Pika H3 Flex, respectively. Meanwhile, ComfyUI and Unsloth have provided weight adaptations and quantized models, deeply integrating H3 into local creative workflows.