
FLUX.3 Image Klein by Black Forest Labs is out now, featuring day-one support in Diffusers. A single model supports both text-to-image and multi-reference image-to-image generation, introducing a brand-new capability: layout control. You can write bounding boxes directly into your prompts to specify where different parts of the image should be placed, or indicate which elements from reference images should move. Both open-weight checkpoints are available in the FLUX.3 Image Klein Collection:
| Checkpoint | Description | Default Parameters |
|---|---|---|
black-forest-labs/flux-3-image-klein | Time step distilled for fast inference | 16 steps, no CFG |
black-forest-labs/flux-3-image-klein-base | Base model | 50 steps, with CFG |
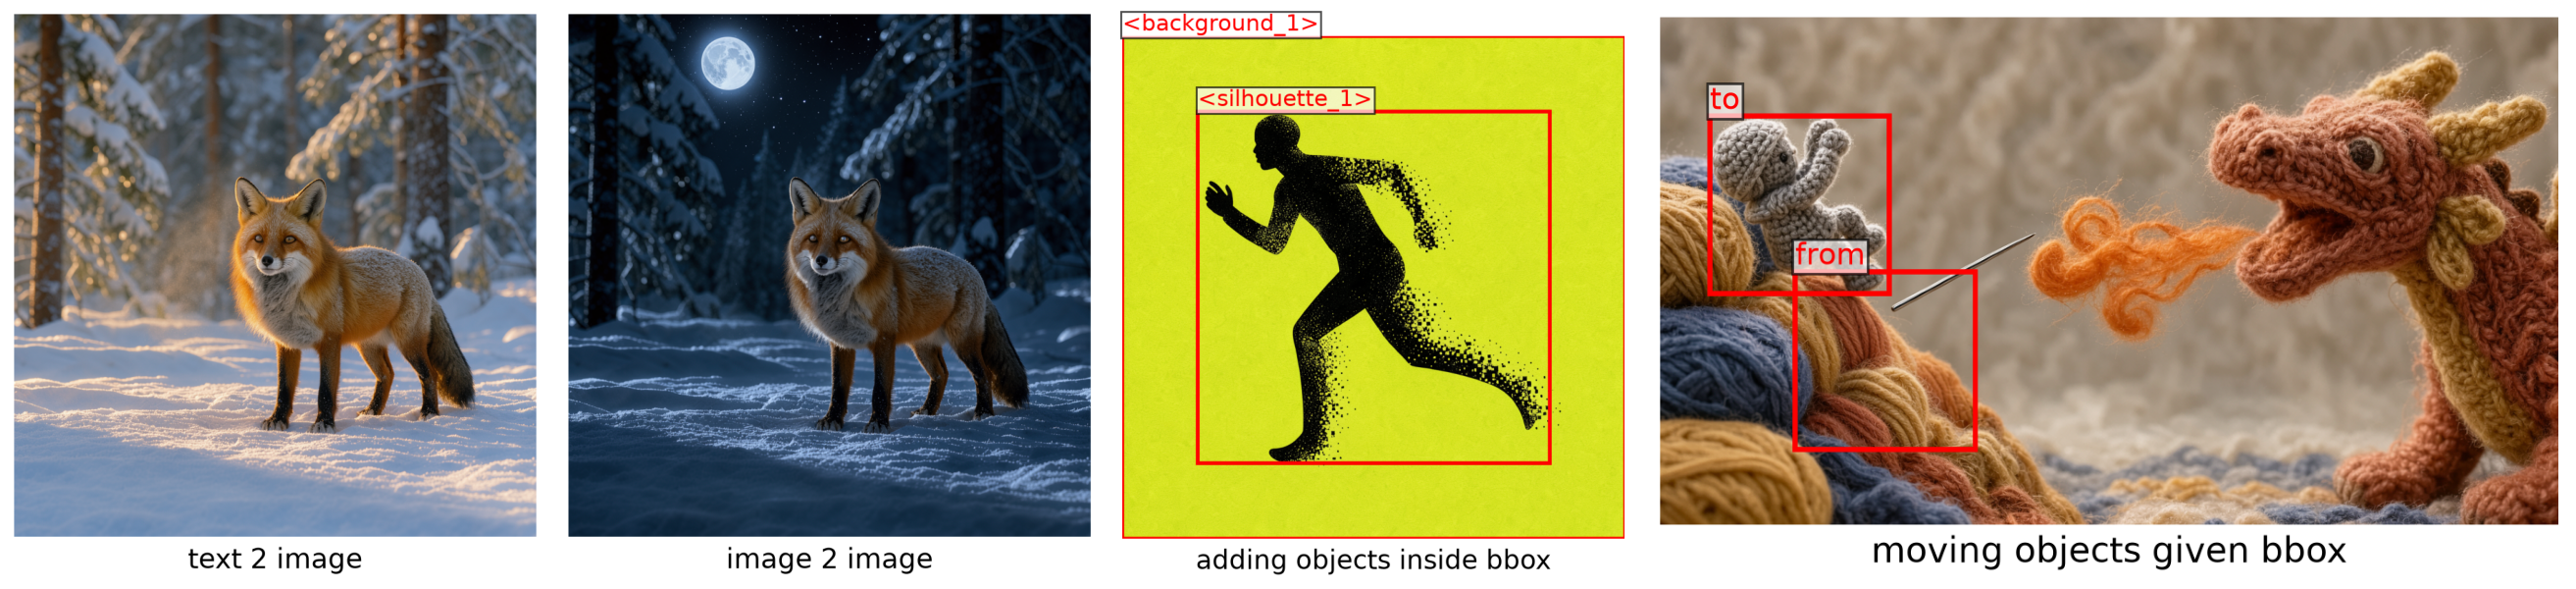
You can try generating images yourself right now on the Hugging Face Space!
TL;DR
- A single model for text-to-image, multi-reference image-to-image, and bounding box-based layout control.
- The distilled checkpoint generates a 1024 × 1024 image in ~2 seconds on a single H100 GPU.
- Supports NVFP4 and FP8 weights via
from_single_filefor GPUs with lower VRAM. - Provides LoRA training scripts for both text-to-image and image editing.
- Released as a Modular Diffusers pipeline, making it easy to swap in or add custom modules.