
We’ve been tracking MSL’s 14-month journey into a frontier lab, and today, the other shoe finally dropped: Meta launched Muse Wonder, completing the lineup alongside Spark and Glimmer, much like OpenAI has Sol/Terra/Luna and Anthropic has Opus/Sonnet/Haiku. Interestingly, while Muse hasn’t disclosed parameter counts, Muse Wonder Full actually beats Fable and Astra on certain benchmarks; however, given the varying degrees of post-training, it remains unclear whether Wonder truly belongs to the Fable/Astra class of models.
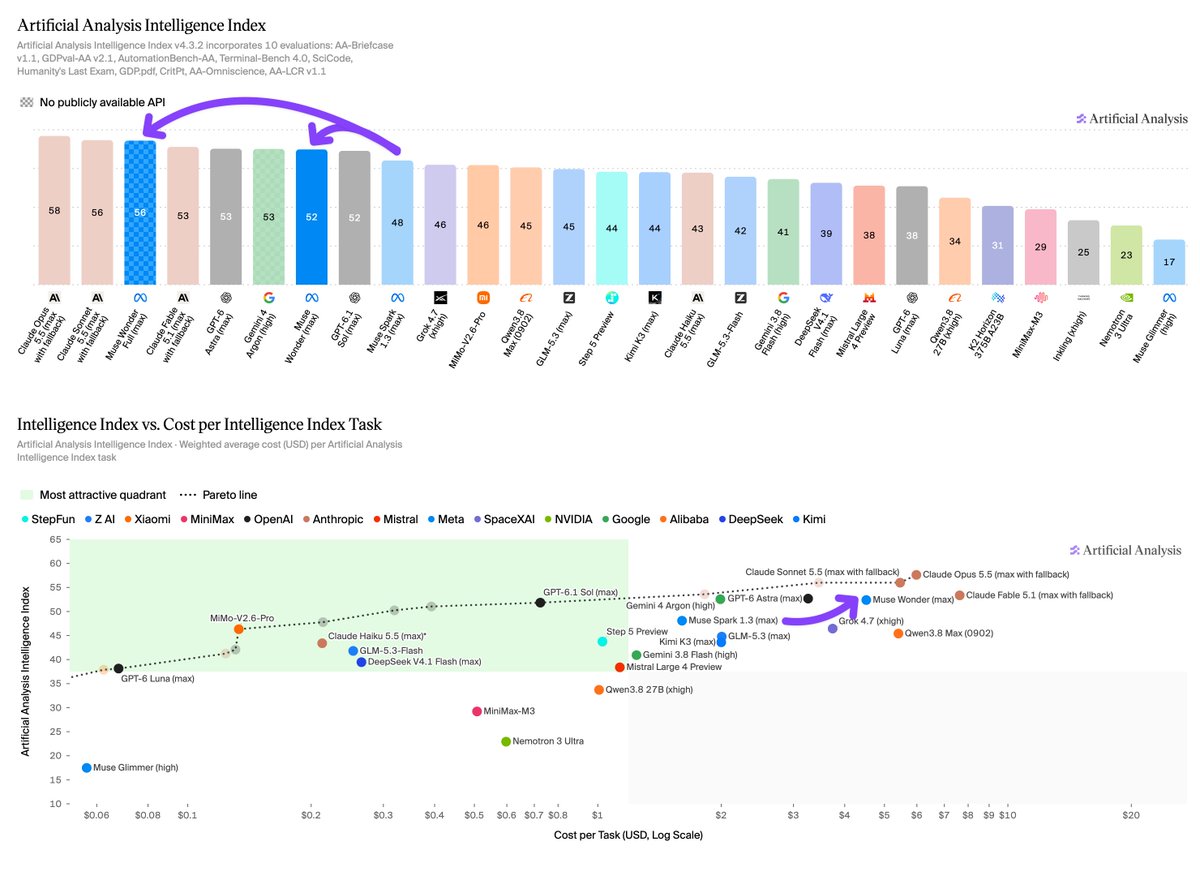
Meta has released Muse Wonder and Muse Wonder Full, scoring 52 and 56 respectively on the Artificial Analysis Intelligence Index v4.3 at maximum reasoning settings—both marking substantial improvements over Muse Spark 1.3 (max 48), released just 6 weeks ago.
Muse Wonder is now rolling out to users…
 —
Below is our full, detailed breakdown of the release.
AI Twitter Recap
Top Story: Meta Releases Muse Wonder and Muse Wonder Full
At a Glance
Meta Superintelligence Labs (MSL) has officially launched Muse Wonder (codenamed “Watermelon” 🍉), its second-generation model family. Third-party benchmarks show performance nearing frontier levels—just ~14 months after the lab’s inception.
-
The Tease: Hours before the official release, several insiders began teasing the announcement with watermelon emojis: @rpnickson (“this is a big watermelon…”), @alexandr_wang, @finkd (“muse told me to post 🍉”), and @EdwardSun0909. @kimmonismus retweeted leaked pricing from @synthwavedd: $4/M input tokens, $20/M output tokens, a 1M context window, with the top-tier reasoning “Wonder Full” tier restricted to MuseCode Power/Maximum Usage subscription plans.
-
Two Models: @finkd announced the model family. He explained that while Muse Spark was MSL’s initial product line, Wonder is “a much larger, more advanced model class pushing us into frontier territory.” The two released tiers are Muse Wonder (a fast frontier model) and Muse Wonder Full (the full flagship model).
-
Tiered Availability (@AIatMeta, Newsroom):
- Wonder is accessible via the Meta Model API and Muse Code.
- Full is exclusive to Muse Code subscribers.
- Wonder will power Muse’s personal agent products, with priority given to subscribers (@finkd).
- Muse Code can be installed via
curl dev.meta.ai/install.sh | bash(@alexandr_wang).
-
Product Positioning: Meta pitches these models as state-of-the-art (SOTA) for “personal and professional agentic work.” @alexandr_wang highlighted three core capabilities:
- Active Memory: Persistent memory spanning days, weeks, and months.
- Active Focus: Powering through bottlenecks to drive tasks to completion.
- Domain Expertise: SOTA in finance and legal, with “strong performance in healthcare.”
-
Training Journey: Wang noted that Meta has been aggressively scaling up pre-training and reinforcement learning (RL) since Muse Spark launched in April (post; research blog). @AIatMeta described it as “going from rebuilding the foundation to pushing the frontier in 14 months.”
-
Safety Claims: @AIatMeta stated that the models were trained for enhanced robustness against adversarial instructions and careful handling of private data. No dedicated system card was referenced.
-
Day-One Rate Limit Bug: Wonder and Wonder Full were burning through Muse Code rate limits at an unexpectedly rapid pace (@alexandr_wang, follow-up). The issue was resolved later that day, with quotas reset for all users (fix announcement; @mjdouglas). Wang noted, “there are definitely still some rough edges we’re working through” (post).
-
Media Appearance: Zuckerberg and Wang appeared on Stripe’s podcast Cheeky Pint (@collision). Topics included the “$100B bet,” agentic commerce, OpenRouter, “why AI won’t be winner-take-all,” and the organizational structure of MSL.
Independent Evaluations (Hard Data)
Artificial Analysis (@ArtificialAnlys) provided the most thorough third-party analysis:
-
Intelligence Index v4.3: Wonder Full (max reasoning) scored 56, and Wonder (max reasoning) scored 52—both improvements over Muse Spark 1.3 (max 48). Spark 1.3 and Wonder launched just 6 weeks apart. Opus 5.5 currently leads the board at 58 (@TheRundownAI).
-
Wonder Full showed gains across all 10 index benchmarks. The most dramatic leaps came in agentic tasks:
- Terminal-Bench 4.0: 33% → 57%
- GDPval-AA v2