
LFM2.5-24B-A2B is a 24-billion (24B) parameter reasoning model with only 2 billion (2B) active parameters, purpose-built for fast, private on-device agents. It thinks before answering, supports tool calling, and executes multi-step tasks across leading agent harnesses. Because it activates just 2B parameters per token, the computational cost per reasoning token is exceptionally low, allowing users to run persistent agents on their own hardware.
- Best-in-class agent: Rivals Qwen3.6-35B-A3B—which has ~50% more total and active parameters—on agentic and tool-calling tasks, leading 48.09 to 38.19 on the LiveClaw benchmark.
- MoE-level reasoning speed: Consistently thinks before answering. With only 2B active parameters per token, every reasoning token is remarkably cheap.
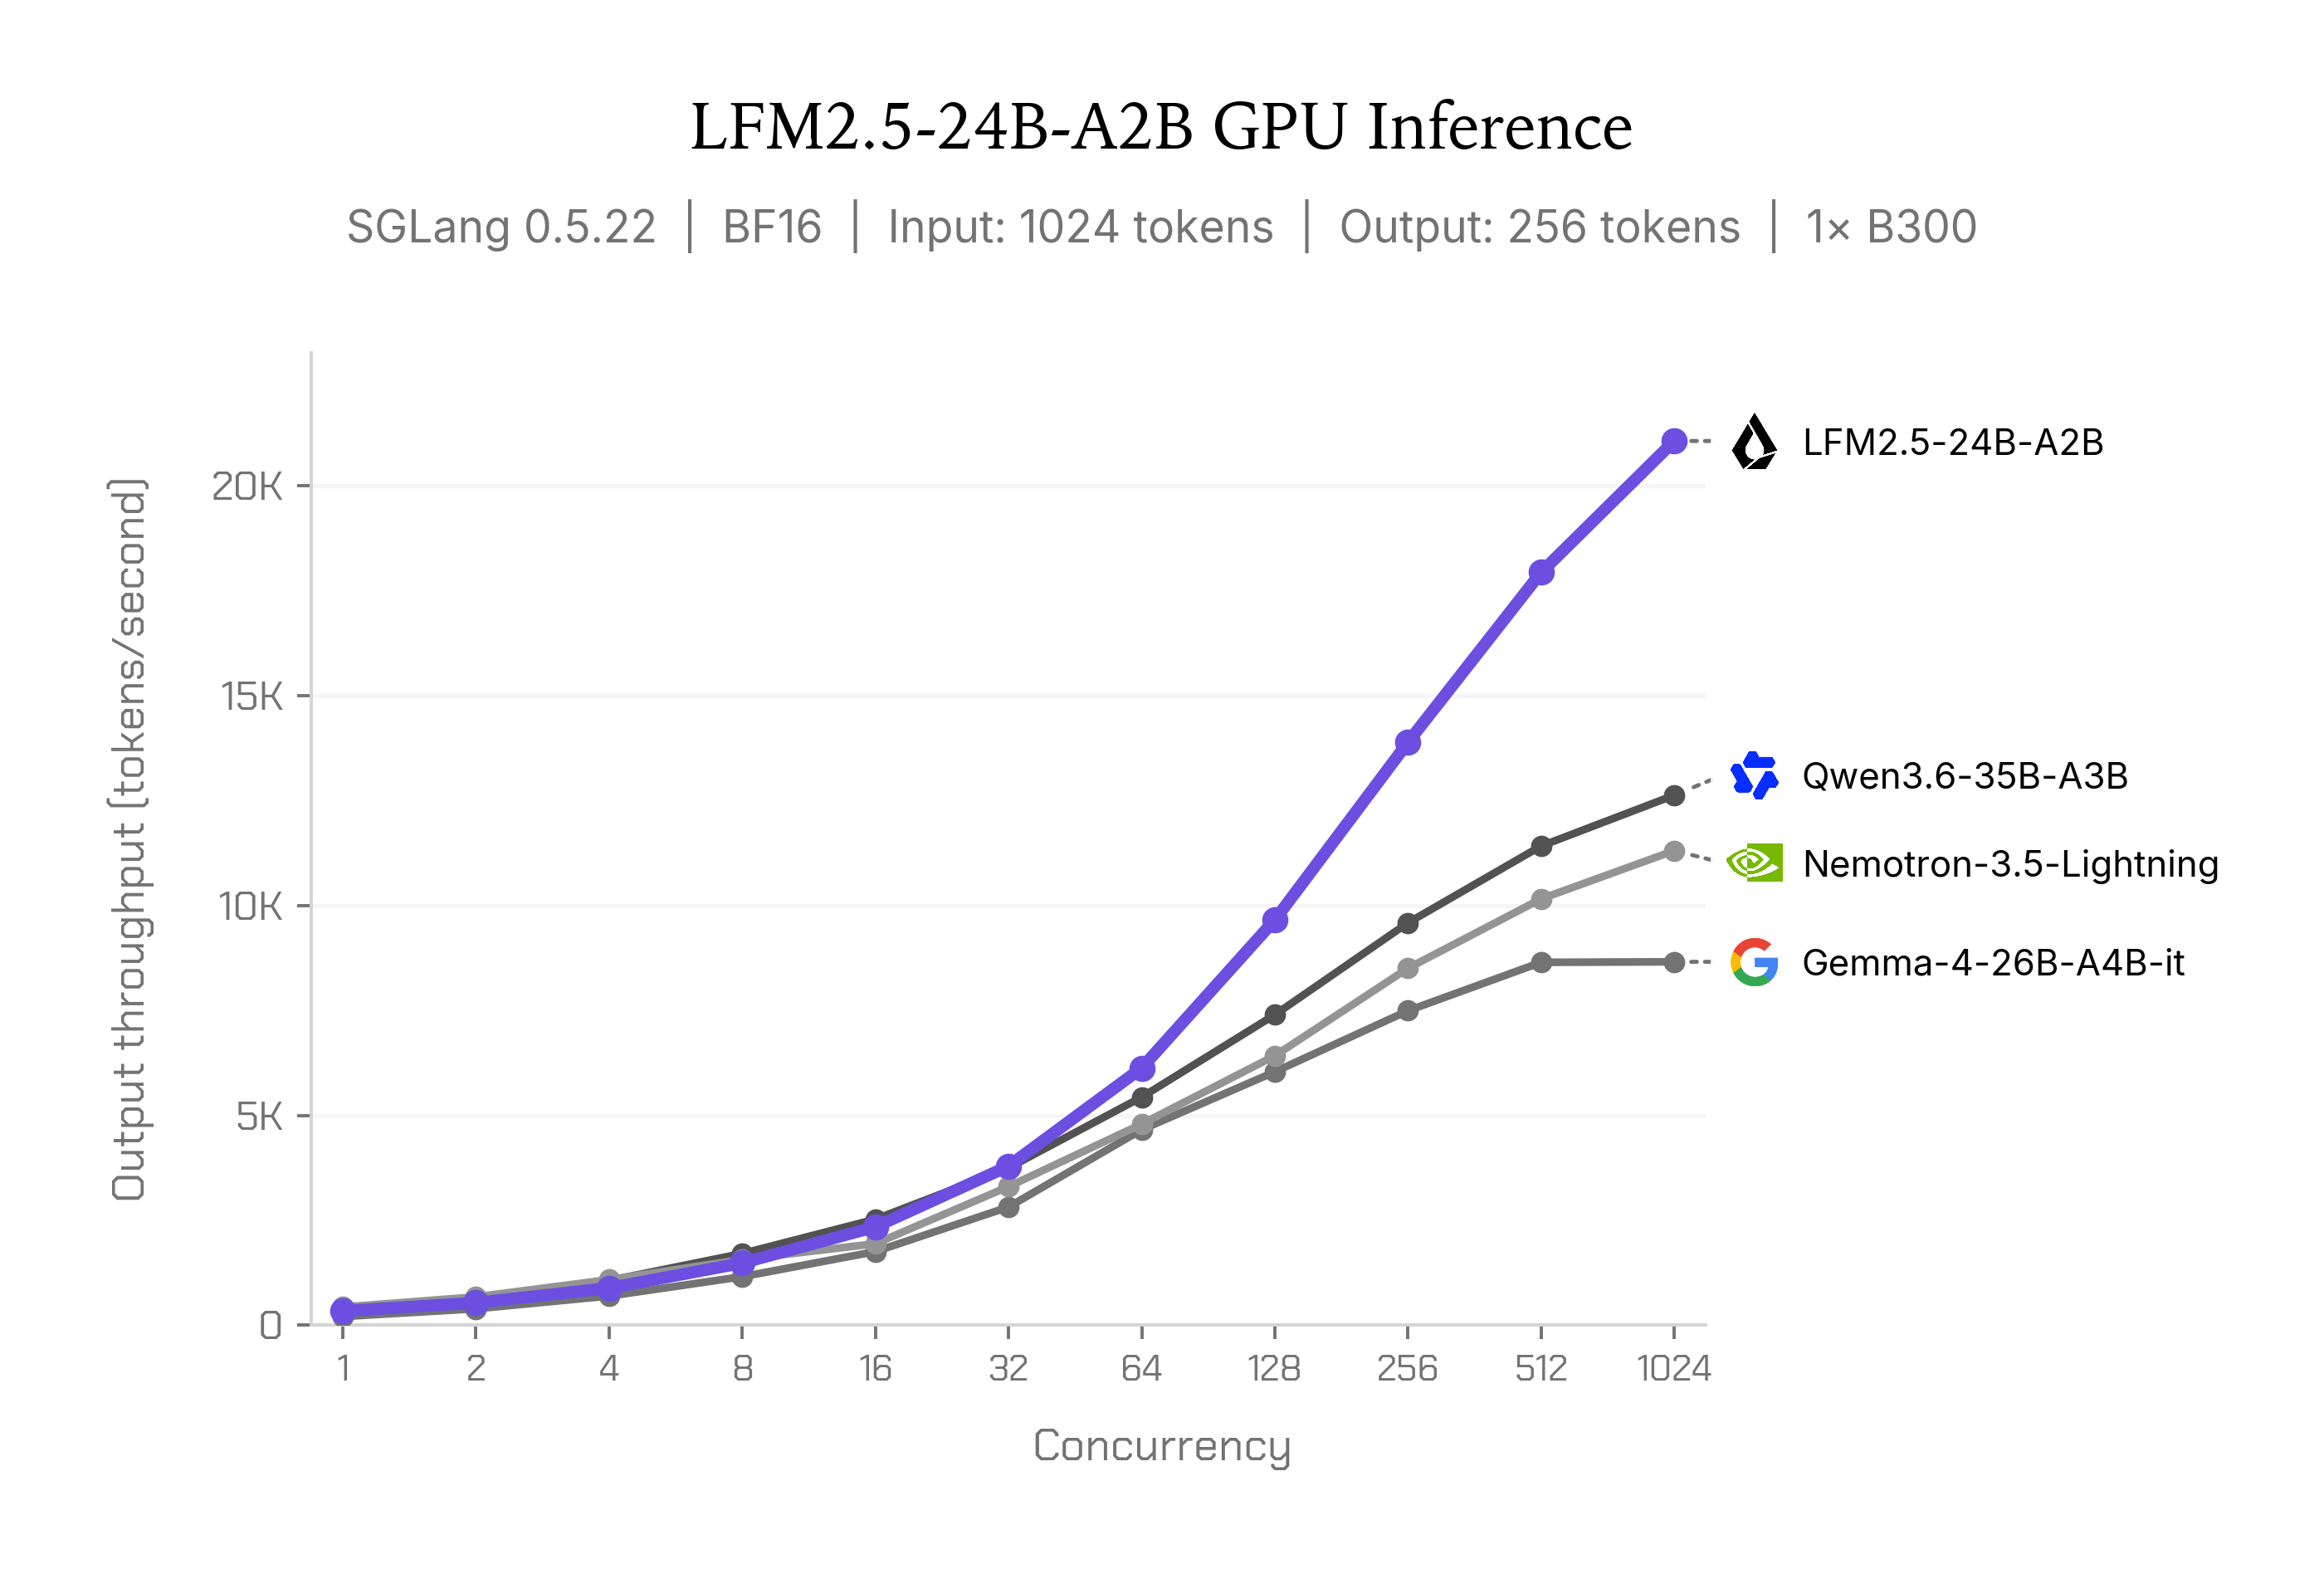
- High-throughput inference: Achieves up to 184 tok/s on an Apple M5 Max, and up to 21K output tok/s on a single NVIDIA B300 GPU.
How We Built a Reasoning Agent with Just 2B Active Parameters
LFM2.5-24B-A2B is built on LFM2-24B-A2B and inherits its model architecture: 40 layers, 64 experts per MoE block with Top-4 routing, and a hybrid design combining gated short convolutions with Grouped-Query Attention (GQA). The context window has been extended from 32K to 131K tokens, and the vocabulary size was doubled from 65K to 128K tokens via in-place tokenizer expansion to enhance tokenization efficiency for non-Latin scripts. Unlike its predecessor, it is a reasoning-only model that produces an explicit Chain of Thought before generating the final response.
Pre-training data was expanded from ~17T to ~33T tokens. Next, mid-training injected 2T tokens at a 32K context window—emphasizing reasoning, mathematics, code, instruction following, and multilingual text—along with 300B tokens at a 131K context window, weighted toward long-context data. Tool calling and multi-turn trajectories were integrated throughout both phases. Post-training then molded the base model into an agent across five stages:
- Supervised Fine-Tuning (SFT)
- Teacher specialization
- Non-agentic Multi-Objective On-Policy Distillation (MOPD, non-agentic): Distilling specialized teacher models on non-agentic tasks.
- Agentic MOPD (MOPD, agentic): A second distillation stage focused on agentic tasks.
- Agentic Reinforcement Learning (Agentic RL): Training the model inside agent harnesses like OpenClaw, Hermes Agent, Pi, and OpenCode.
Benchmark Results
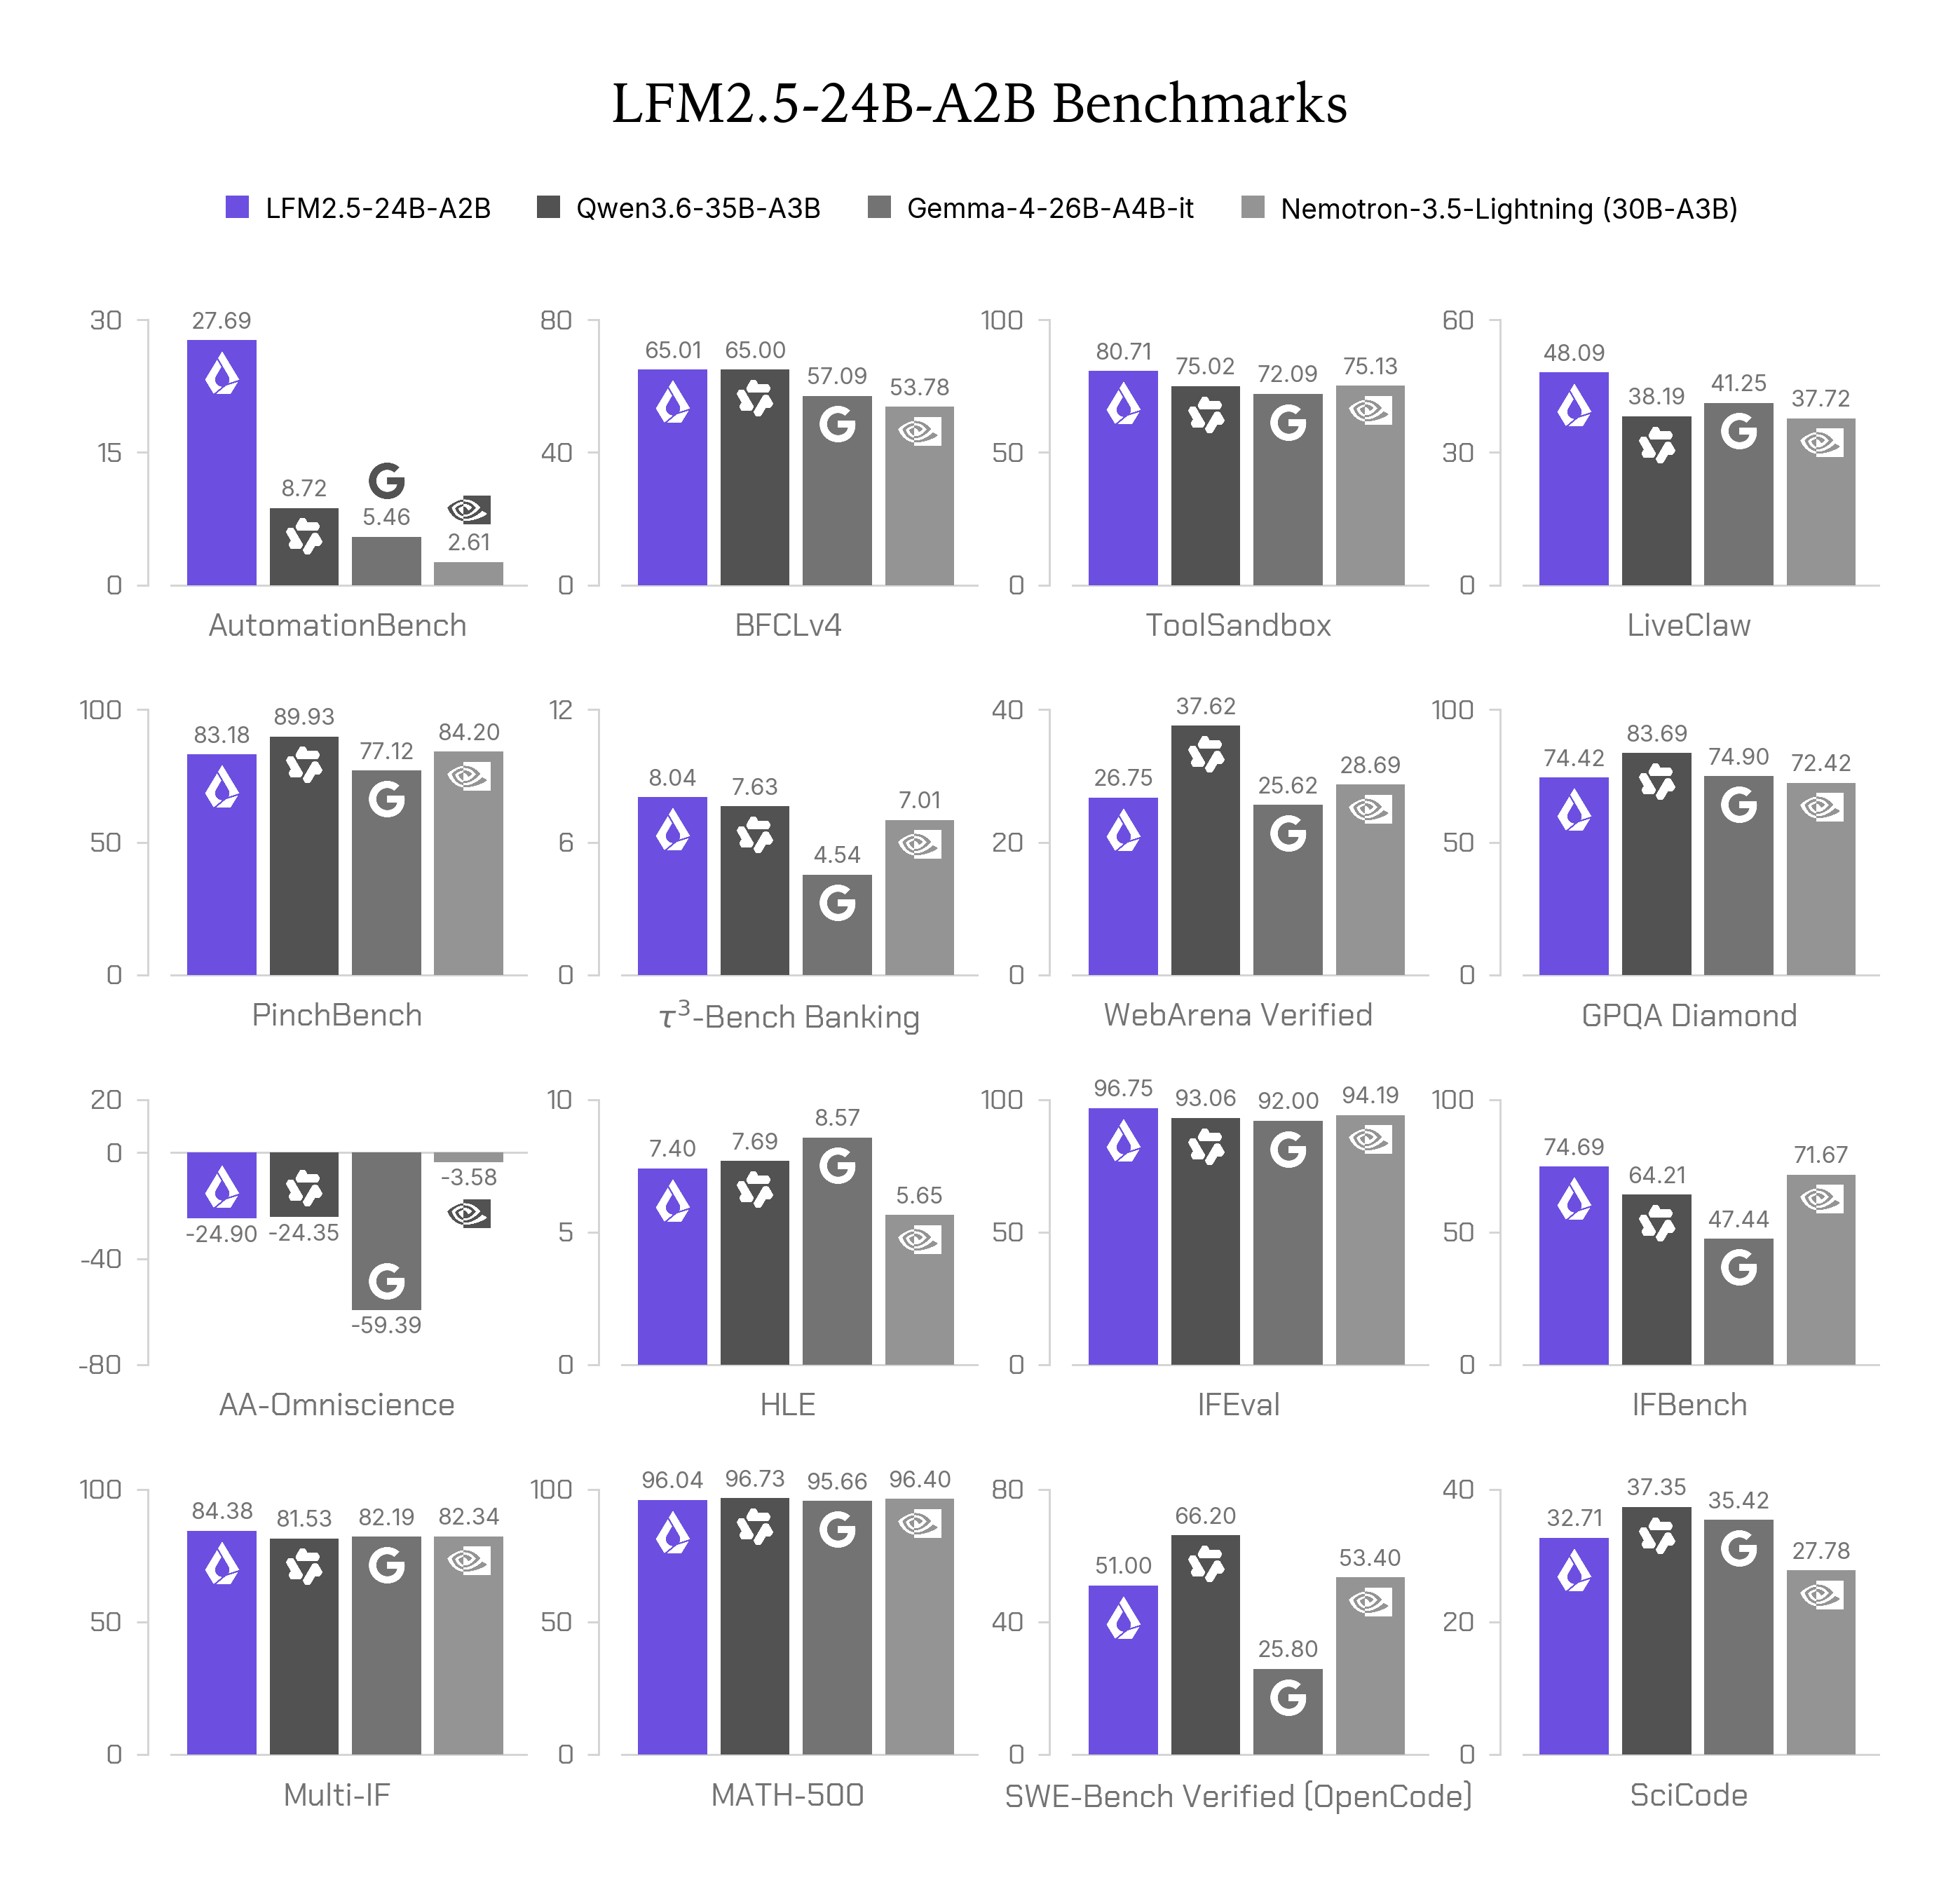
We evaluated LFM2.5-24B-A2B against Qwen3.6-35B-A3B, Gemma-4-26B-A4B-it, and Nemotron-3.5-Lightning across 16 benchmarks covering tool calling, agent workflows, general knowledge, instruction following, math, and coding. Even though it is the smallest model in this group, it goes toe-to-toe with MoE models featuring ~50% more total and active parameters.
| Benchmark | LFM2.5-24B-A2B | Qwen3.6-35B-A3B | Gemma-4-26B-A4B-it | Nemotron-3.5-Lightning (30B-A3B) |
|---|---|---|---|---|
| AutomationBench | 27.69 | 8.72 | 5.46 | 2.61 |
| BFCLv4 | 65.01 | 65.00 | 57.09 | 53.78 |
| ToolSandbox | 80.71 | 75.02 | 72.09 | 75.13 |
| LiveClaw | 48.09 | 38.19 | 41.25 | 37.72 |
| PinchBench | 83.18 | 89.93 | 77.12 | 84.20 |
| τ³-Bench Banking | 8.04 | 7.63 | 4.54 | 7.01 |
| WebArena Verified | 26.75 | 37.62 | 25.62 | 28.69 |
| GPQA Diamond | 74.42 | 83.69 | 74.90 | 72.42 |
| AA-Omniscience | -24.90 | -24.35 | -59.39 | -3.58 |
| HLE | 7.40 | 7.69 | 8.57 | 5.65 |
| IFEval | 96.75 | 93.06 | 92.00 | 94.19 |
| IFBench | 74.69 | 64.21 | 47.44 | 71.67 |
| Multi-IF | 84.38 | 81.53 | 82.19 | 82.34 |
| MATH-500 | 96.04 | 96.73 | 95.66 | 96.40 |
| SWE-Bench Verified (OpenCode) | 51.00 | 66.20 | 25.80 | 53.40 |
| SciCode | 32.71 | 37.35 | 35.42 | 27.78 |
*All models were evaluated using vLLM with the recommended generation parameters for each benchmark.
For real-world applications, its core strengths lie in tool use and instruction following. Across 8 tool-calling and agent benchmarks, LFM2.5-24B-A2B leads or matches competitors on 5 (AutomationBench, BFCLv4, ToolSandbox, LiveClaw, and τ³-Bench Banking); on AutomationBench, its score is more than triple that of the runner-up. Furthermore, it takes first place on all 3 instruction-following evaluations. Larger models still retain a modest edge on knowledge-intensive benchmarks (such as GPQA Diamond, HLE, and AA-Omniscience) as well as coding evaluations (such as SWE-Bench Verified (OpenCode) and SciCode). Therefore, for heavily knowledge-dependent tasks, we recommend pairing LFM2.5-24B-A2B with retrieval-augmented generation (RAG) or web search.
These benchmark results make LFM2.5-24B-A2B a compelling foundation for building agents that run reliably on local devices while delivering both reasoning and tool-calling capabilities.
Inference Speed on CPU and GPU
LFM2.5-24B-A2B launches with comprehensive inference ecosystem support from day one, including llama.cpp, MLX, vLLM, SGLang, and ONNX.
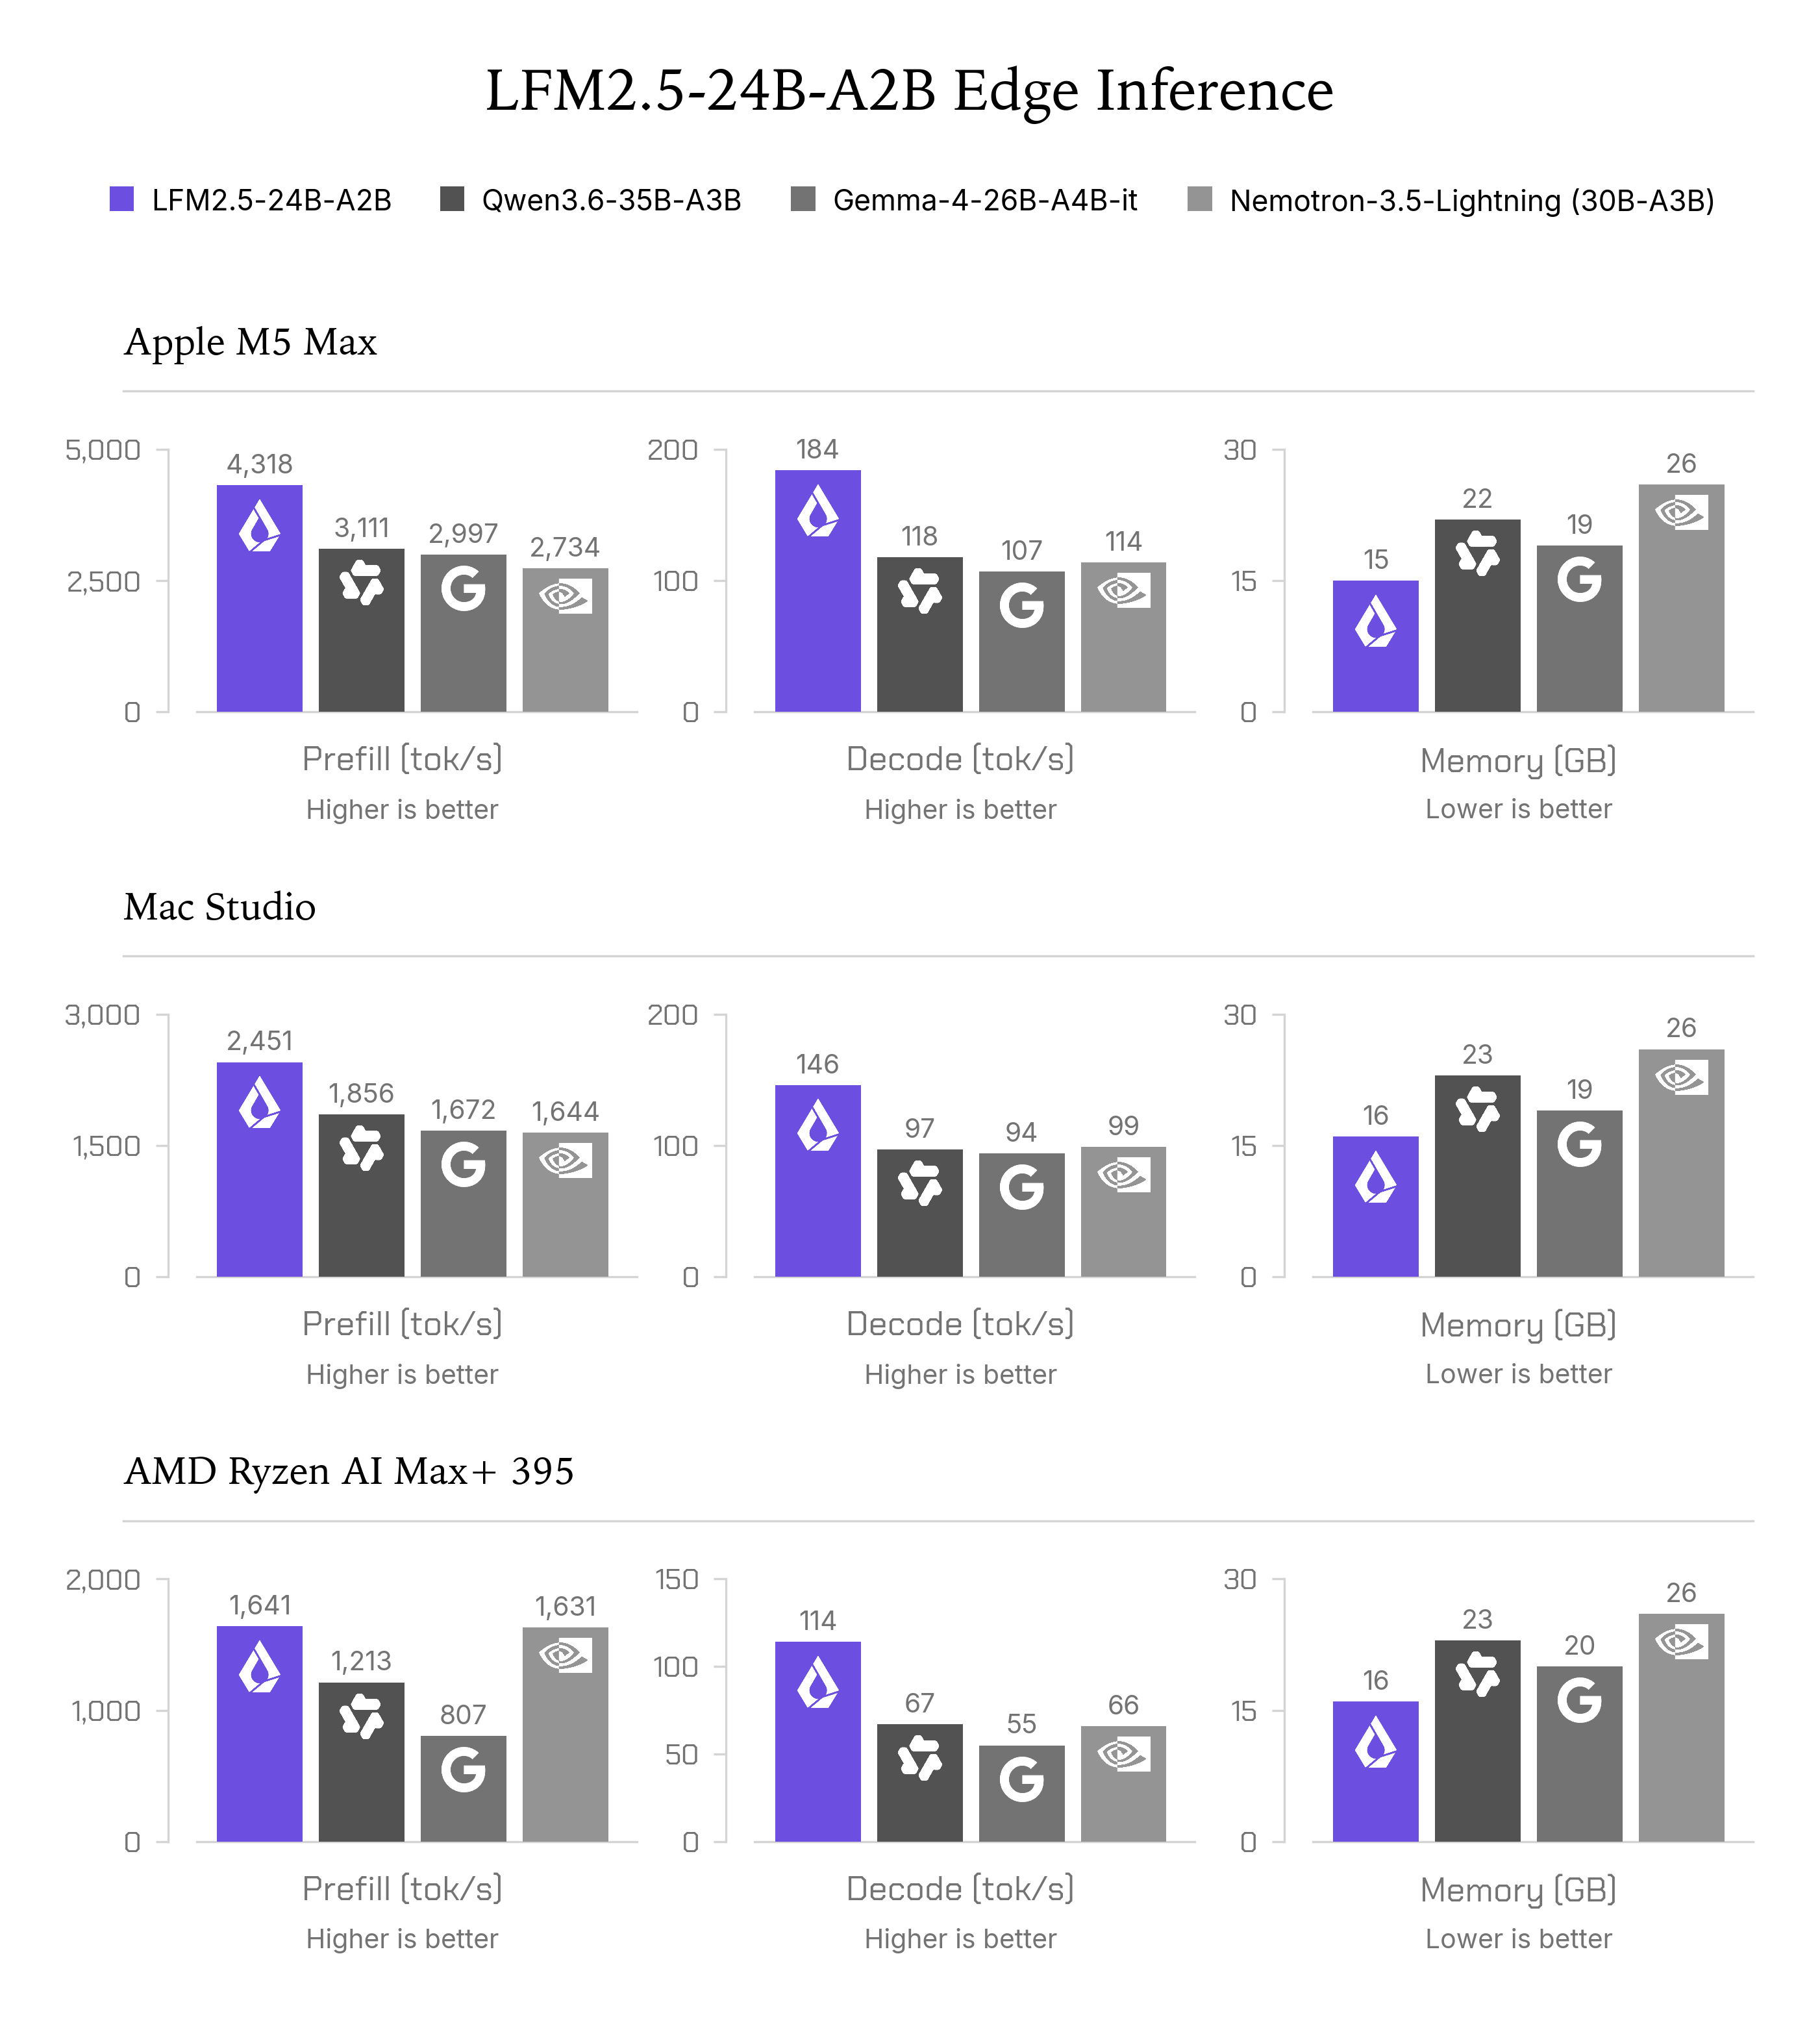
On-device / Edge inference. LFM2.5-24B-A2B is the fastest among the evaluated MoE models, reaching a decoding speed of 184 tokens/s on M5 Max and 114 tokens/s on Ryzen AI Max+ 395—up to 1.7× faster than the runner-up while maintaining the lowest memory footprint.
GPU inference. LFM2.5-24B-A2B is the fastest model in its weight class, exceeding 21K tokens/s on a single B300 under high-concurrency workloads.
Getting Started with LFM2.5-24B-A2B
If you are looking to build reasoning- and tool-use-enabled agents that run reliably on local hardware, LFM2.5-24B-A2B is an ideal choice.
Install the latest version of transformers (compatible with transformers>=5.0.0):
pip install -U transformersThen load and run the model:
from transformers import AutoModelForCausalLM, AutoTokenizer, TextStreamer
model_id = "LiquidAI/LFM2.5-24B-A2B"model = AutoModelForCausalLM.from_pretrained(    model_id,    device_map="auto",    dtype="bfloat16",)tokenizer = AutoTokenizer.from_pretrained(model_id)streamer = TextStreamer(tokenizer, skip_prompt=True, skip_special_tokens=True)
prompt = "What is C. elegans?"
input_ids = tokenizer.apply_chat_template(    [{"role": "user", "content": prompt}],    add_generation_prompt=True,    return_tensors="pt",    tokenize=True,)["input_ids"].to(model.device)
output = model.generate(    input_ids,    do_sample=True,    temperature=0.1,    top_k=50,    repetition_penalty=1.05,    max_new_tokens=512,    streamer=streamer,)
Using in Your Agent Harness
Deploy and run LFM2.5-24B-A2B on any OpenAI-compatible local backend, then point your agent harness to that endpoint. For example, with Hermes Agent:
hermes config set model.provider customhermes config set model.base_url http://localhost:8080/v1hermes config set model.default LFM2.5-24B-A2Bhermes config set model.context_length 131072hermes config set model.api_mode chat_completionshermes config set agent.tool_use_enforcement trueThe exact port depends on your chosen inference backend: 8080 for llama.cpp and MLX, 8000 for vLLM, 30000 for SGLang, and 1234 for LM Studio. For OpenClaw and Pi setups, check out the model card, and consult the official guide for complete configuration steps. Check out our [release blog](https: