Has GLM’s “Speed Demon” Arrived?
Zhipu AI has quietly rolled out a new model named GLM-5.3-Highspeed, which is now integrated into Zcode.
According to a leak shared by @leo114119, the model is currently accessible in Zcode 3.15.1 and is being randomly rolled out via a staged canary release to subscribed users.
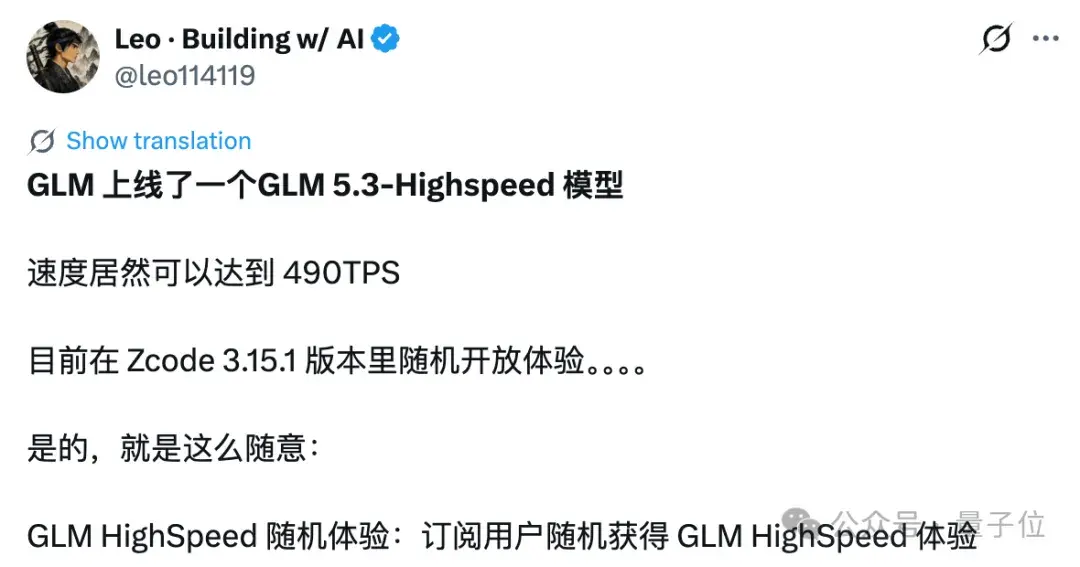
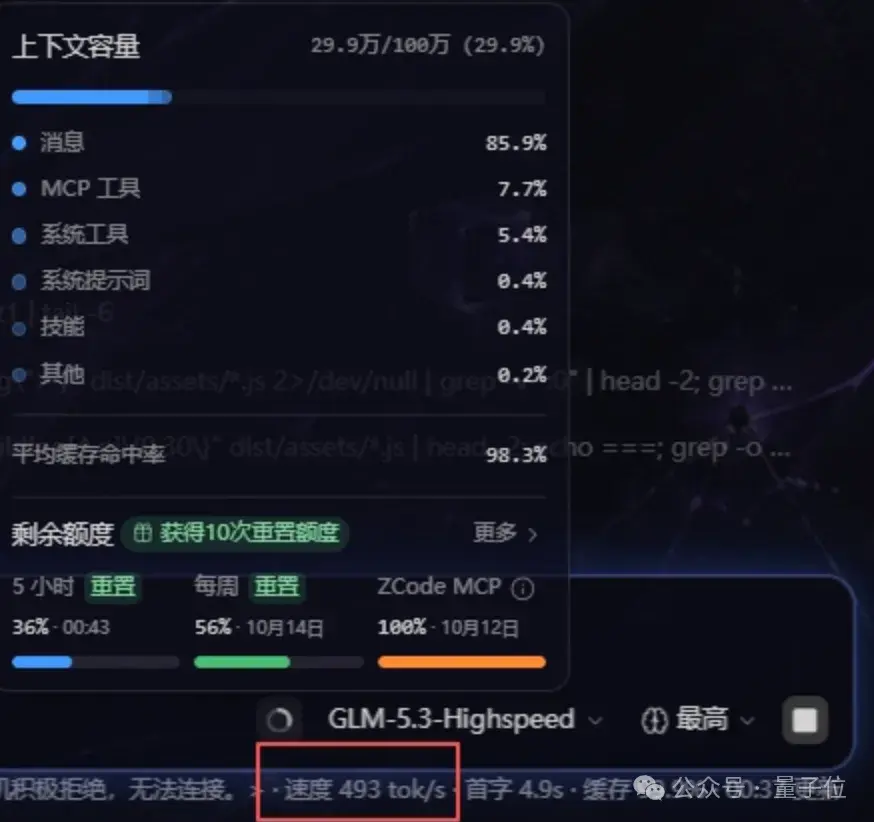
Based on the shared benchmark tests, its generation speed hits an astonishing 490 tokens/s.
We immediately headed over to Zcode to try manually adding and switching to this model.
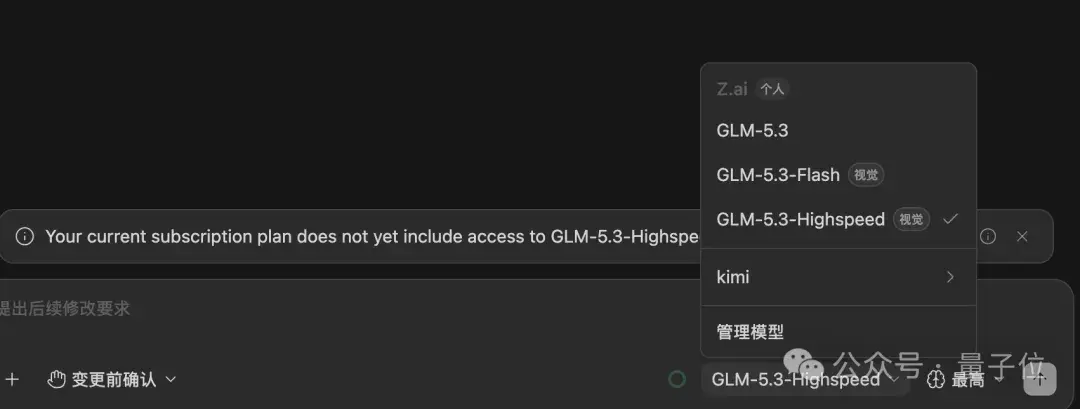
However, likely because the Lite tier hasn’t been granted access yet or our account wasn’t included in the canary rollout, we were unable to invoke it for now.
How Does GLM-5.3 Highspeed Perform?
With speed as its headline feature, all eyes are naturally on its generation performance.
The shared benchmark of 490 TPS is remarkably fast, closing in on the 500 TPS threshold (TPS represents Tokens Per Second). At that sustained rate, outputting 10,000 tokens takes only about 20 seconds.
For comparison, GLM-5.3-FlashX, released by Zhipu just last month, tops out at around 200 tokens/s; meanwhile, speed tests from Artificial Analysis show GLM-5.3-Flash outputting at roughly 60 tokens/s on the Z.ai API.
Such a leap in throughput makes it a true next-generation “speed demon.”
In fact, clues pointing to GLM-5.3-Highspeed surfaced earlier—the model had already been cataloged in Pi’s model directory.
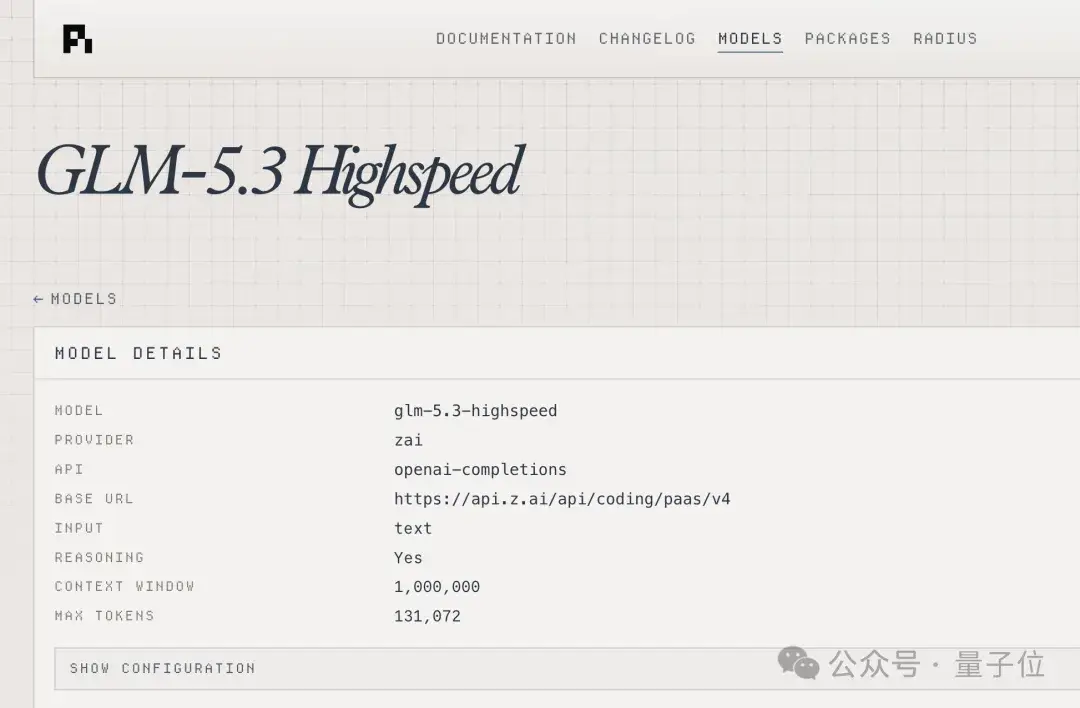
Directory details indicate that GLM-5.3-Highspeed features a 1-million-token context window, a maximum output limit of 131,072 tokens (~128k), and three reasoning intensity tiers: low, high, and max. These specifications match those of the standard GLM-5.3.
Additionally, discussions have emerged across Reddit, with several users speculating that it might be connected to Omen Alpha, the anonymous model spotted on OpenCode.
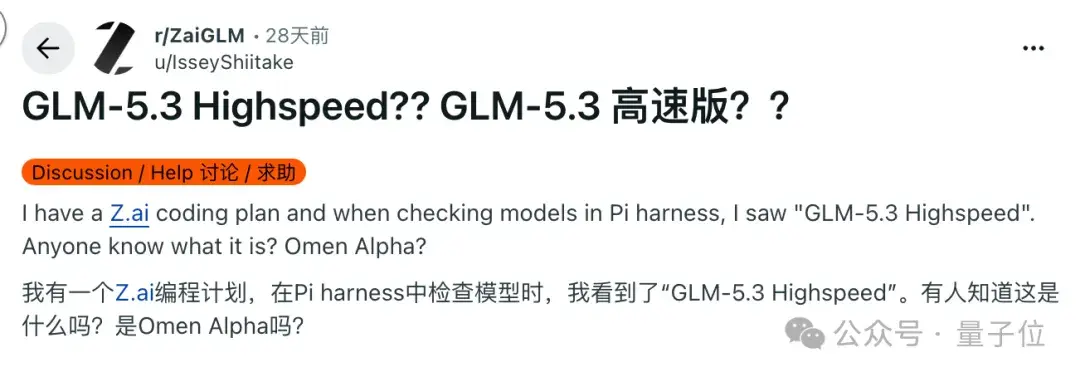
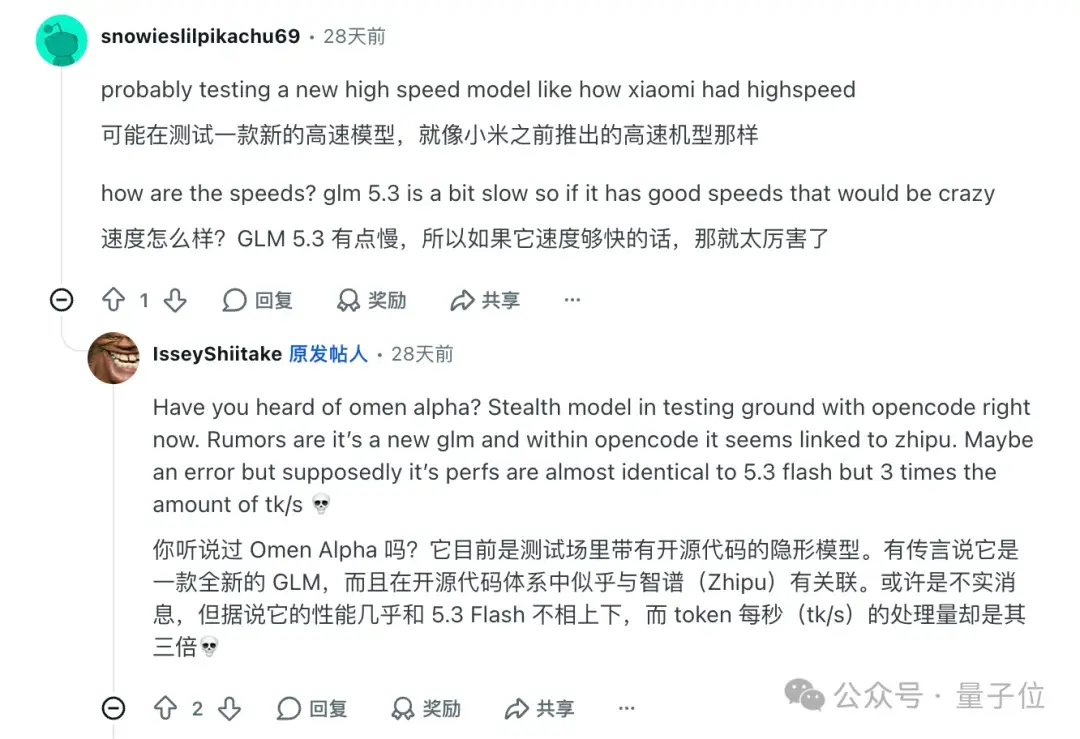
Omen Alpha appeared on OpenCode back in September, and numerous characteristics have led the community to trace its origins back to the GLM lineup.
One user even tested it with the classic “pelican riding a bicycle” benchmark prompt:
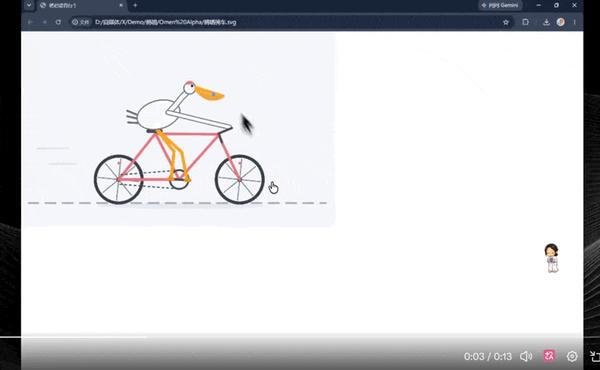
The consensus from real-world feedback: blazing-fast inference, deep reasoning, and consistently stable output quality.
The true identity of Omen Alpha remains a subject of debate—some speculate it is GLM-5.3-Highspeed, while others guess it could be GLM-5.3-Omni or GLM-5.4-Flash.
Prior to this, Zhipu had already made moves in the high-speed model space. The GLM-5.1-highspeed released in May clocked in at 400 tokens/s, setting a new benchmark across global LLM API providers at the time.
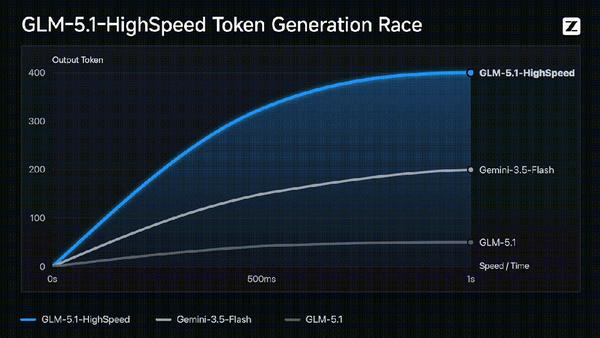
If GLM-5.3-Highspeed can reliably maintain 490 TPS, it will bring substantial productivity gains to high-throughput, long-context workloads.
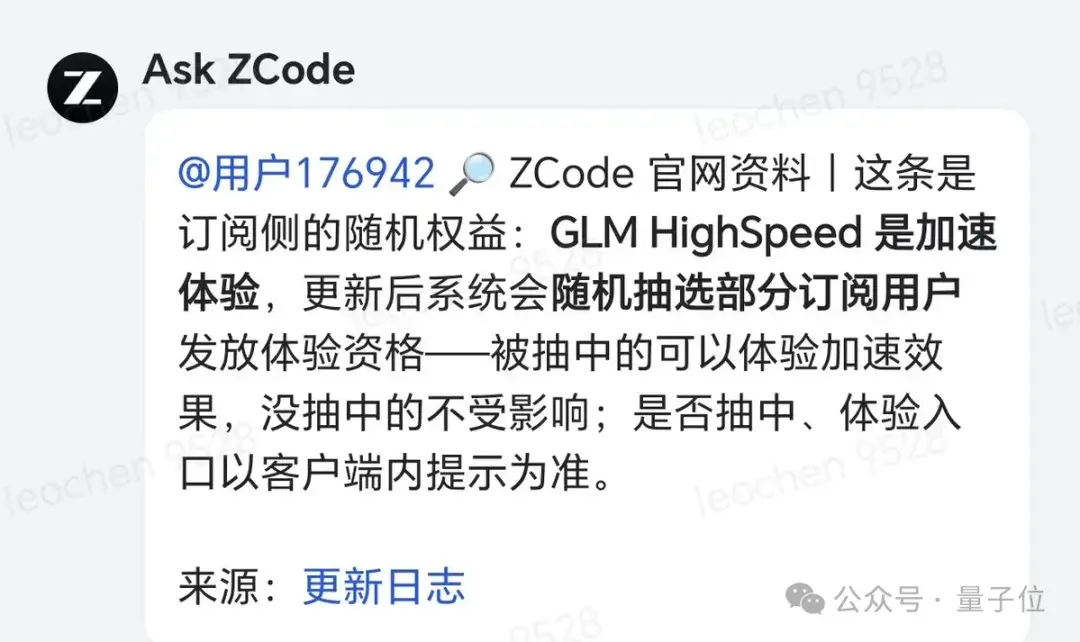
The model is currently undergoing canary testing in Zcode. If you have been granted access, it is well worth putting it through its paces.