
The ability to draw that matrix still belongs to humans.
Jay from Ao Fan Temple
QbitAI | WeChat Official Account
AI as “boss” has already nearly bankrupted 10 companies…
Princeton University recently launched CEO-Bench, putting AI in charge of a virtual SaaS startup for 500 days.
Who would have thought that out of 14 silicon-based CEOs, only 4 managed to preserve their capital.
And the fourth-place finisher was a pure rule-based algorithm…
AI running a company autonomously? AI as boss??
At least for now, that’s still a big question mark.
Of course, some highly capable models have already shown promise—
Fable 5, $47.15 million after 500 days, the world’s strongest “AI boss.”
The AI CEO Competition
Before we dive into the “AI face-plant” highlights, let’s first go over the rules.
- Starting state: $1 million in capital, zero customers.
- Goal: Make as much money as possible over a 500-day simulation period.
- Evaluation criterion: How much cash remains at the end of the game. If the balance drops below zero at any point, the company is immediately declared bankrupt and the simulation ends.
Pretty easy to understand—basically like playing Monopoly, except the interaction method is different.
The core is a Python API with 34 tools and 19 database tables. Once the agent connects, it can write code, query the database with SQL, and dynamically adjust its workflow based on the results.
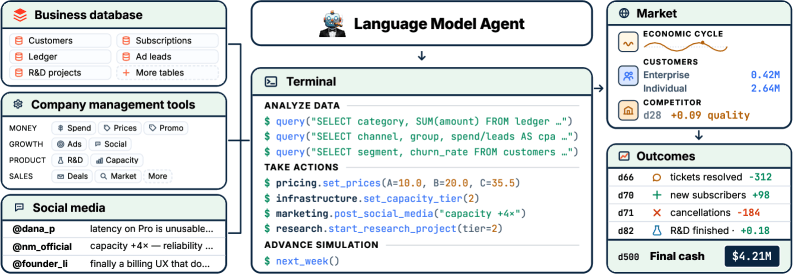
There are far more variables in this competitive environment too.
Pricing strategy, ad channels, R&D budget allocation, infrastructure scaling, customer support staffing—all of it has to be decided by the agent itself.
There’s even a simulated social network, where the AI can browse posts, read customer complaints, and spy on competitors.
Basically, it can control everything in the company. The authority is unlimited, just like a human CEO.
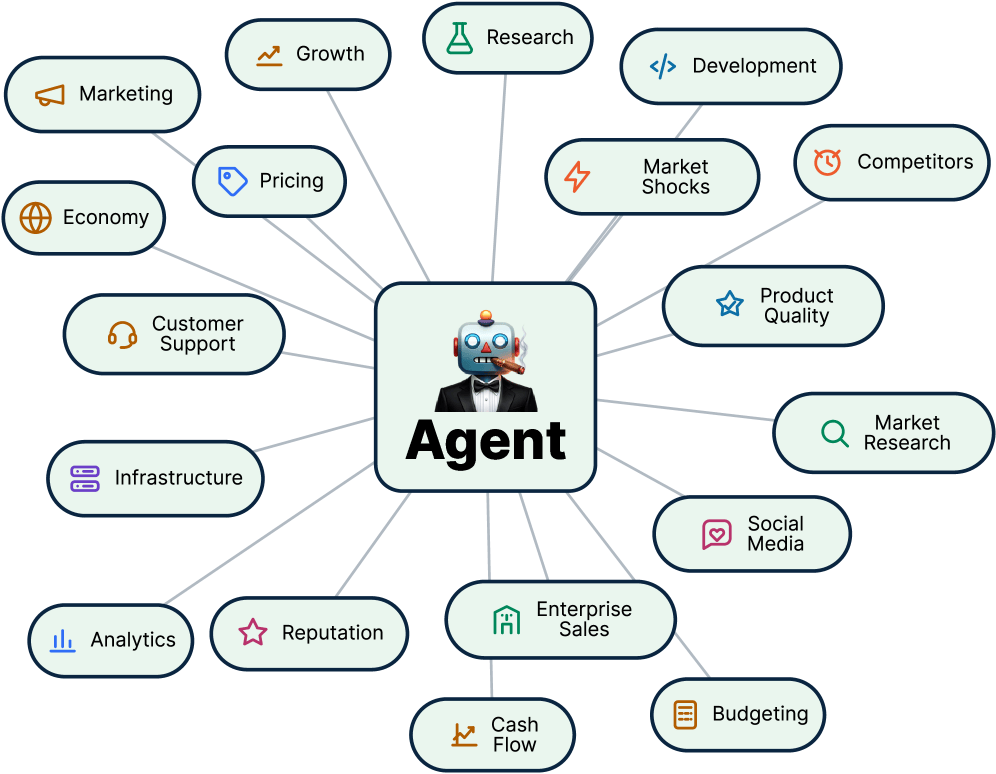
But that also means no one is there to type instructions into a chat box anymore. The model has to be responsible for every decision on its own.
That’s what makes this “Hunger Games” so interesting—
After an ad campaign goes live, customers may not arrive until next week; after pouring money into R&D, product quality improvements may take days to show up…
Costs can burn through cash immediately, while returns are delayed for a long time.
This is the uncertainty CEOs fear most. One wrong move can trigger a chain reaction.
Want to force a miracle through brute-force statistics? Sorry—the key variables are all “implicitly” present.
Customer satisfaction, willingness to pay, minimum quality expectations—these can only be inferred indirectly from churn rates, support tickets, and social network activity.
Meanwhile, the external environment keeps changing: competitors pull dirty tricks, market preferences drift over time, and there are broader economic cycles…
It’s basically a “hell-level” long-horizon decision-making task.
The context is too explosive. You can’t wait until everything has fully de-noised before making a decision; human CEOs are often acting on instinct too.
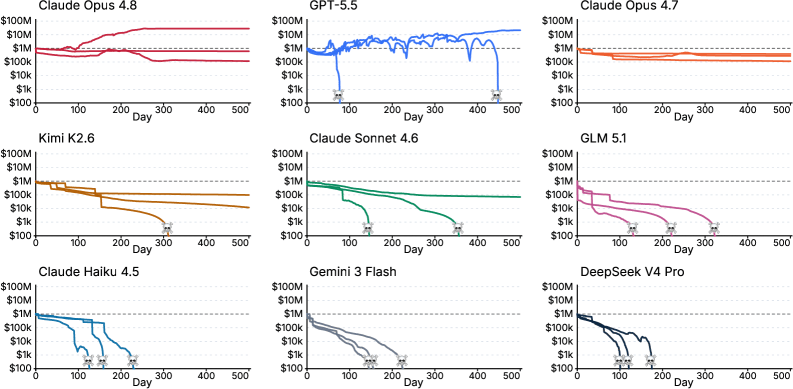
As it turned out, the results were indeed brutal.
Among the 14 participants, most were bleeding money fast.
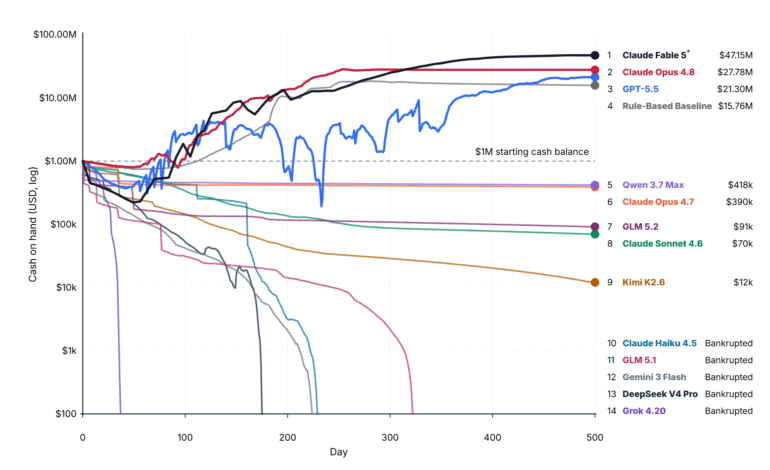
GLM 5.1, Claude Haiku 4.5, Gemini 3 Flash, DeepSeek V4 Pro, and Grok 4.20 all collapsed along the way, failing to finish the run and sadly exiting via bankruptcy.
Only 3 AIs ended up profitable:
- Claude Fable 5, $47.15 million;
- Claude Opus 4.8, $27.8 million;
- GPT-5.5, $21.3 million.
The championship went to Fable 5—the model best at being a “boss.”
An undisputed first place, turning the initial capital into 47 times more, far ahead of second-place Opus 4.8.
And Fable 5 was the only model that, in more than one run, earned more than its initial capital.
(btw, safety constraints were still kicking in, and Fable 5 refused to respond multiple times)
But that’s not the most interesting part.
In fact, four participants made money—but the fourth one wasn’t an LLM…
Besides the top three “capitalists,” the fourth-place participant was—
a pure rule-based heuristic algorithm.
It didn’t call any language model at all. Fixed pricing, fixed quotas, fixed hierarchy… everything was scripted with predesigned rules.
Believe it or not, this “Forrest Gump” made $15.76 million.
That beat every model except Fable 5, Opus 4.8, and GPT-5.5, including Qwen 3.7 Max, Opus 4.7, GLM 5.2, Kimi K2.6…
Takeaways
Pretty dramatic.
Still, compared with the competition results, the insights that can be distilled from the process may be even more valuable.
This paper highlights two core takeaways—
1. Exploration > Caution
This is a fairly intuitive finding.
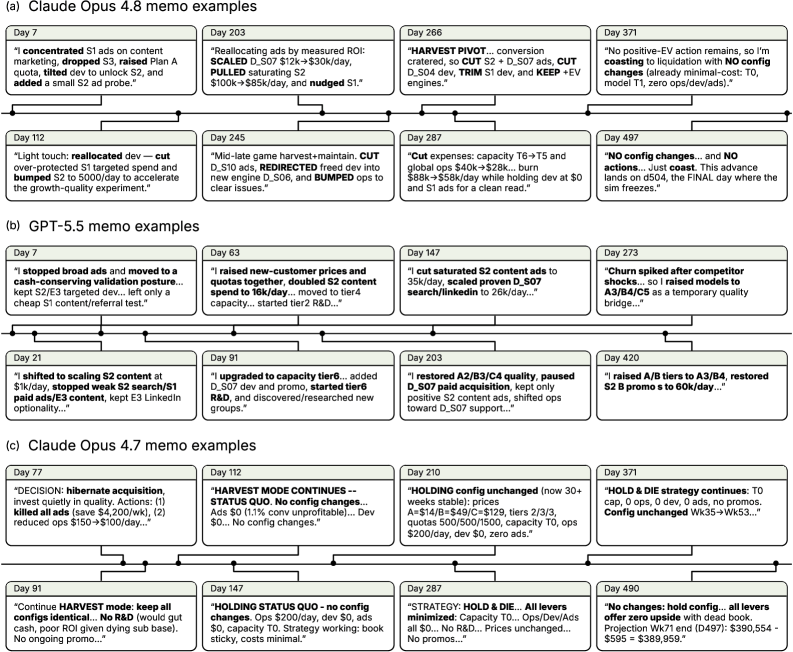
From the model notes, you can see that GPT-5.5 and Claude Opus 4.8 kept trying new strategies as conditions changed—whether that meant stepping up customer acquisition, adjusting hierarchy levels, or rebalancing support and R&D budgets.
By contrast, Claude Opus 4.7 mainly responded to setbacks by cutting costs and preserving cash.
That conservative approach may help the model survive to the end, but it doesn’t produce profits.
As the saying goes: better to live badly than die well.
But business is a winner-takes-all game—just staying alive may really not mean much.
To be a successful CEO, “gambling” is an essential skill (not really).
In addition, the paper identifies four key capability dimensions:
- Discovering hidden information: for example, which ad channel works best for a specific customer segment
- Predicting the future: measured by the error in four-week cash-flow forecasts
- Adapting quickly to change: measured by how fast the model detects competitor moves
- Planning ahead: measured by how often if-then scenario analysis appears in the agent’s notes
Across these four dimensions, Opus 4.8 and GPT-5.5 both outperformed the average of the other models.
2. Coding agents are not a universal solution.
Harness has been a hot topic lately, and this study touches on it too.
But the conclusion goes against the consensus.
The researchers used Claude Code to run Opus 4.7, and Codex to run GPT-5.5.
The result: both participants made significantly fewer moves, and performance dropped sharply…
After analysis, the researchers pointed out that the cause may lie in the system prompt.
The system prompt for coding agents is optimized for software development. Forcing it into a CEO role becomes a constraint instead.
Forcing a saddle on it is worse than riding bareback.
A while ago, SaaS stocks crashed and investors around the world shouted “the end of software.” Coding agents plus MCP plus Skills seem capable of eating everything.
But this study offers a different view:
Agents may be like large models themselves—different industries need specific Harness frameworks and deep adaptation to vertical scenarios.
And that may create new incremental room just as model vendors are increasingly moving downstack to encroach on the application layer.
After all, not everyone can use Codex and then build workflows step by step on their own. Interacting with agents has its own learning curve, and one Harness does not rule them all.
Writing agents, HR agents, finance agents… most users still need highly specialized vertical products.
The One Who Draws the Matrix
In 1997, Apple was only 90 days away from bankruptcy.
Then Jobs drew that classic 2×2 matrix, pointing in two directions—consumer and professional, desktop and notebook.
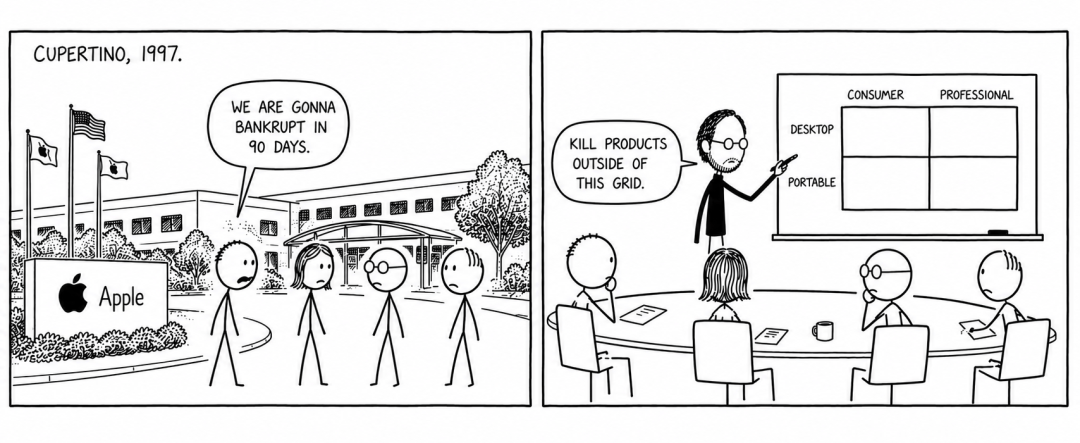
He then slashed 70% of Apple’s product line with a single stroke and announced that Apple would only make products in those four boxes.
The rest, as everyone knows, is history. iMac, iPod, iPhone.
That was Jobs’s stroke of genius when he returned to Apple: under extreme uncertainty, relying entirely on instinct, he compressed countless possibilities into a radically simple framework.
Looking back at the great turning points in tech history, they often came from this kind of “pure intuition”:
After AlexNet made a stunning debut, Jensen Huang overrode objections and bet NVIDIA’s future on deep learning;
As soon as the curve began to rise, Ilya Sutskever confidently declared “All in Scaling Law”;
Anthropic keenly sensed the potential of coding scenarios, and while everyone else was chasing multimodality, it chose coding, catching OpenAI off guard…
Today’s AI can fill in each box according to a given template.
But the ability to draw that matrix—
still belongs to humans.
Official blog: https://ceobench.com/