
A New Benchmark Specifically for Evaluating Embodied Spatial Intelligence
Tingyu, from Aofei Temple
QbitAI | Official Account: QbitAI
After ImageNet, Fei-Fei Li Strikes Again!
Fei-Fei Li’s team has just released ESI-Bench — a new benchmark specifically designed to evaluate embodied spatial intelligence.
Traditional spatial intelligence benchmarks give models the best possible observations by default, but ESI-Bench is the first to turn the observer into an actor, closing the perception-action loop.
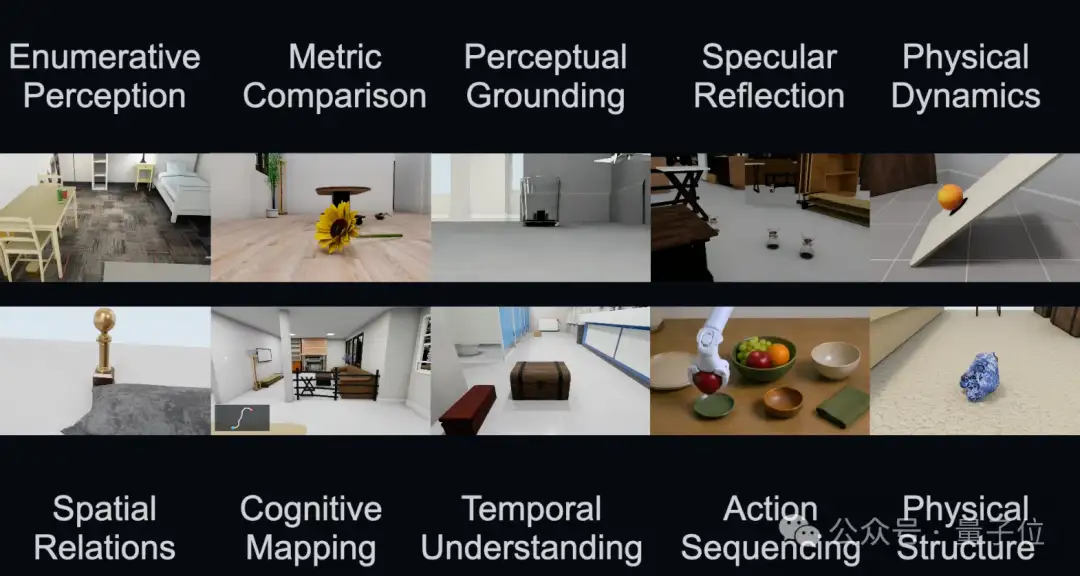
It provides a systematic evaluation framework for embodied spatial intelligence, covering four dimensions of core human spatial cognition.
The paper’s central conclusion is: today’s AI is excellent at looking at images, but it is still far from spatial intelligence that can “move, touch, and actively seek answers.”
What is ESI-Bench
ESI-Bench was created because current spatial intelligence benchmarks mostly test “passive perception.”
You feed the model one or a few images and ask questions like “Is object A to the left or right of object B?”, “How much water can this cup hold?”, or “Is there anything in the drawer?” These tasks measure a model’s eyesight, not its spatial reasoning ability.
Humans, by contrast, would stand up and walk around to look behind an object, pull open the drawer, or pour out the water to measure it.
That is the core position of ESI-Bench: turn the observer into an actor.
In the real world, an agent must act like a human: proactively decide what to do, gather evidence, and then make the next judgment based on new observations. The team calls this the Perception-Action Loop.
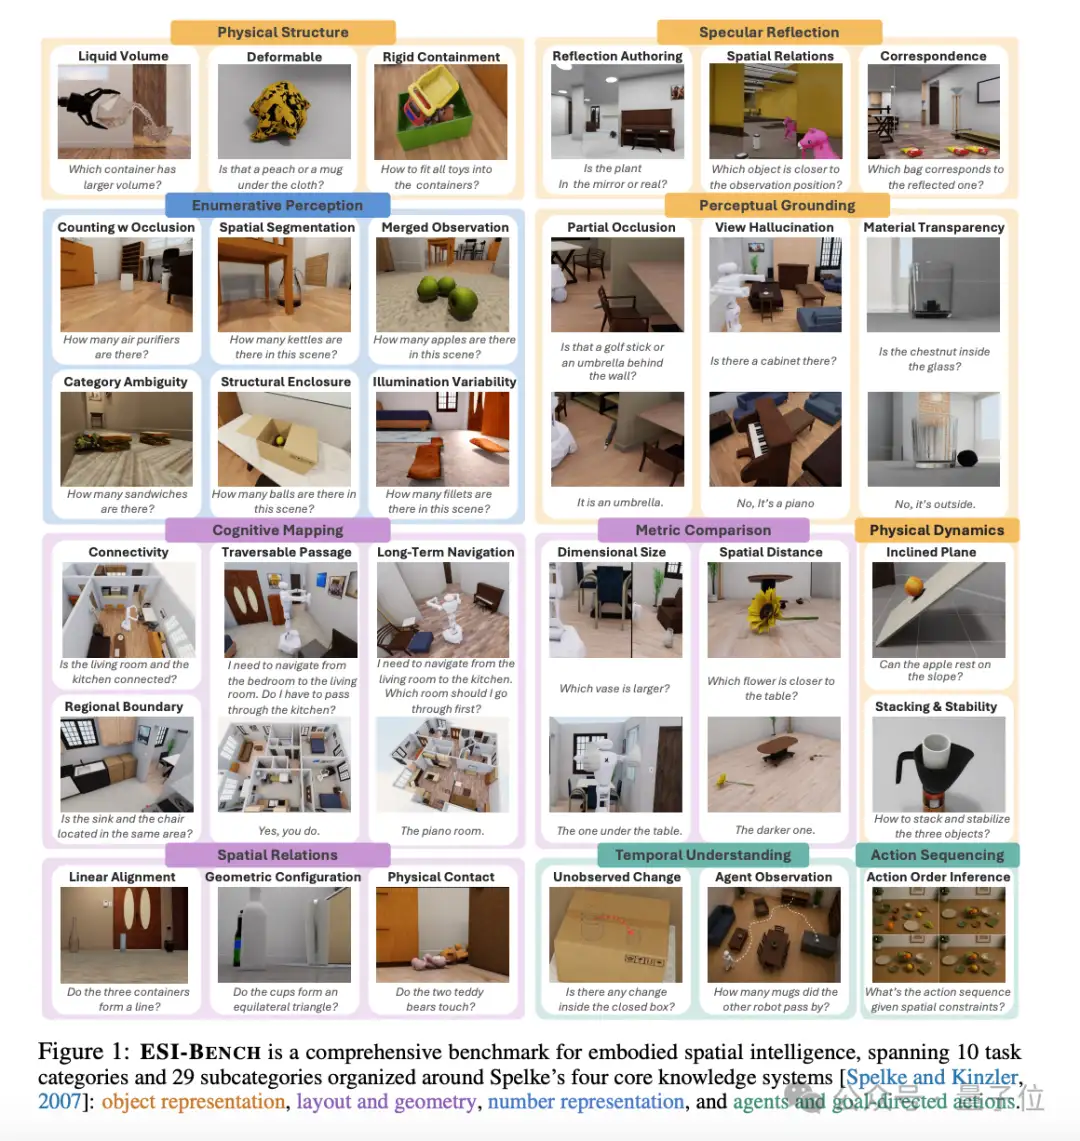
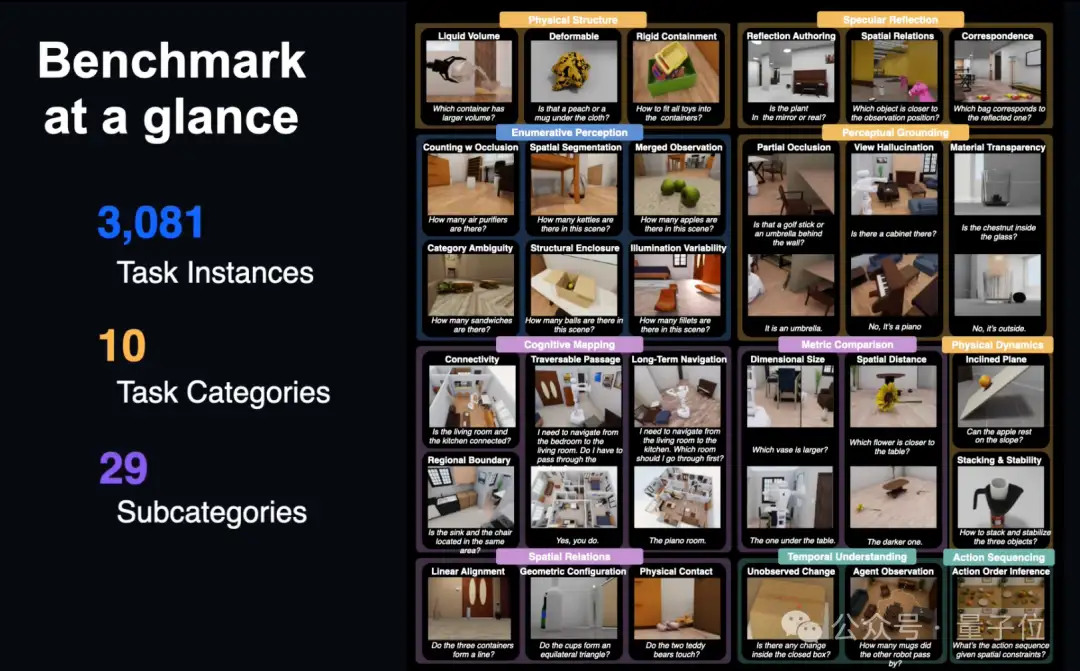
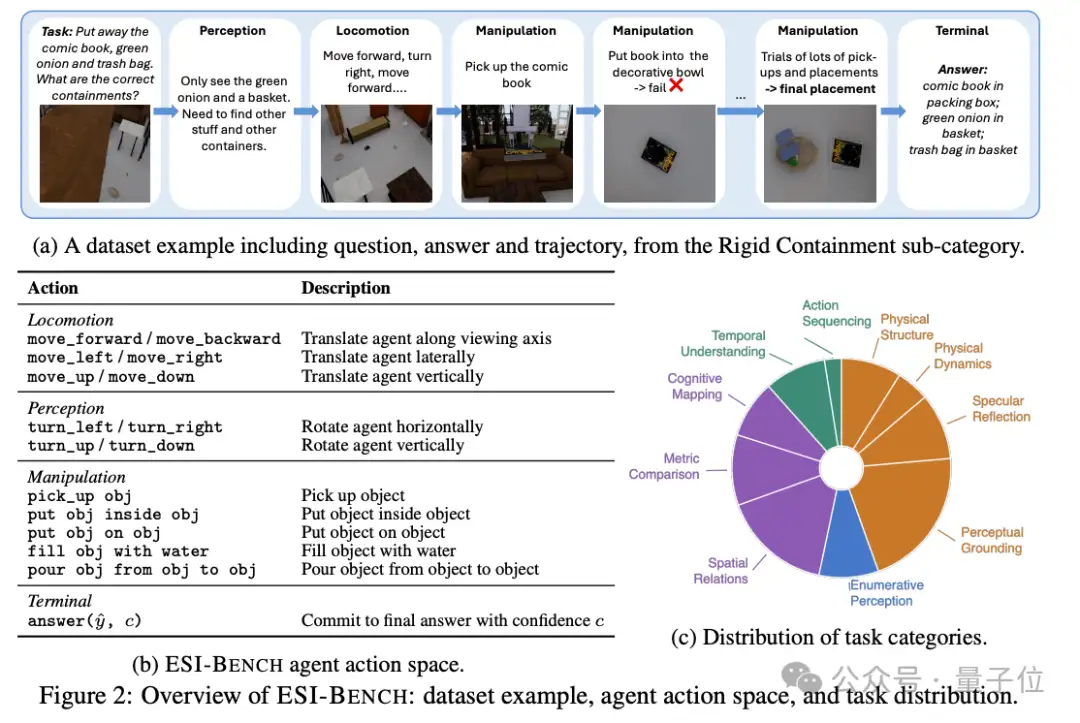
ESI-Bench is a new spatial intelligence evaluation benchmark that goes beyond existing ones. It contains 10 task categories, 29 subcategories, and 3,081 task instances, all built on the OmniGibson simulation platform, with scene assets drawn from the BEHAVIOR-1K scene library.
All tasks are designed around Spelke’s four core knowledge systems — the spatial intuitions that human infants are born with: object representation, layout and geometry, quantity representation, and goal-directed action.
Its key design choice is action enforcement. For every question, the AI agent must take action on its own to obtain enough information before answering. The model cannot sit still and wait for images; it has to decide where to go, what to look at, what to pick up, and how to interact.
Here are a few concrete examples:
For example, one evaluation task is rigid containment: given several containers and several objects, the agent must fit all the objects inside. Some containers have narrow openings, some have internal dividers, and some require the lid to be lifted to reveal their true capacity.
The model has to move closer, lean in, or even pick up the container and inspect it from the bottom to determine whether the objects will fit.
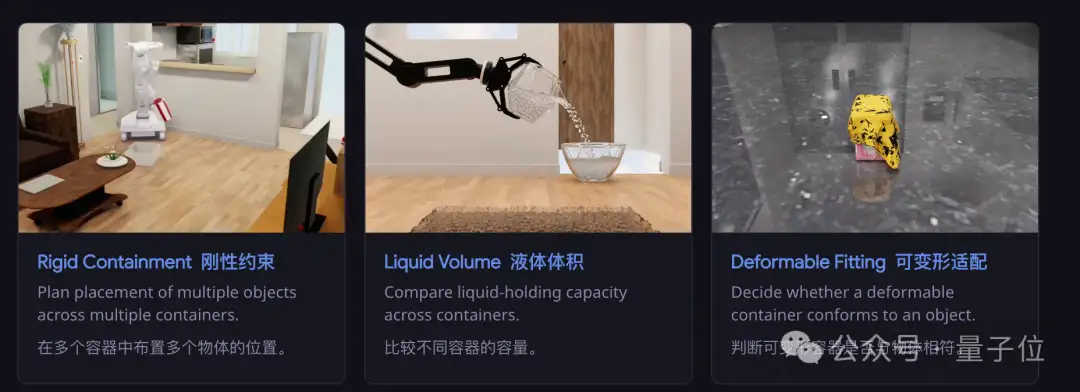
There is also a liquid volume task: two cups may look identical from the outside, but their capacities differ. The model needs to pour water in to test them, or simply lift them to feel the weight.
From this, the benchmark’s design philosophy should be easy to grasp:
The correct answer is not in any single image; the agent must act proactively and reason out the right result.
The team specifically points out that ESI-Bench advances over prior work in three ways:
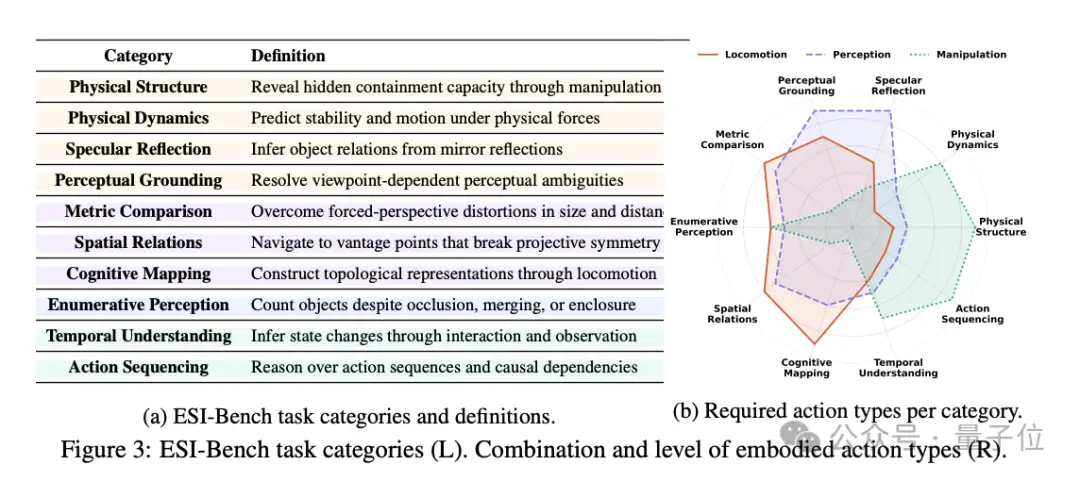
From spatial perception to spatial capability: here, agents are evaluated not only by what they can perceive, but also by whether they know which specific capabilities to deploy to solve spatial tasks;
Selective perception: agents must determine which observations are worth obtaining, prioritizing task-relevant information over redundant or uninformative input;
Resolving perceptual ambiguity: agents must reason through misleading observations to infer hidden spatial structures and latent physical constraints that go beyond direct observation.
What did the evaluation reveal? Three key conclusions
The team conducted comprehensive tests on today’s strongest multimodal models, including GPT-5 and the Gemini family.
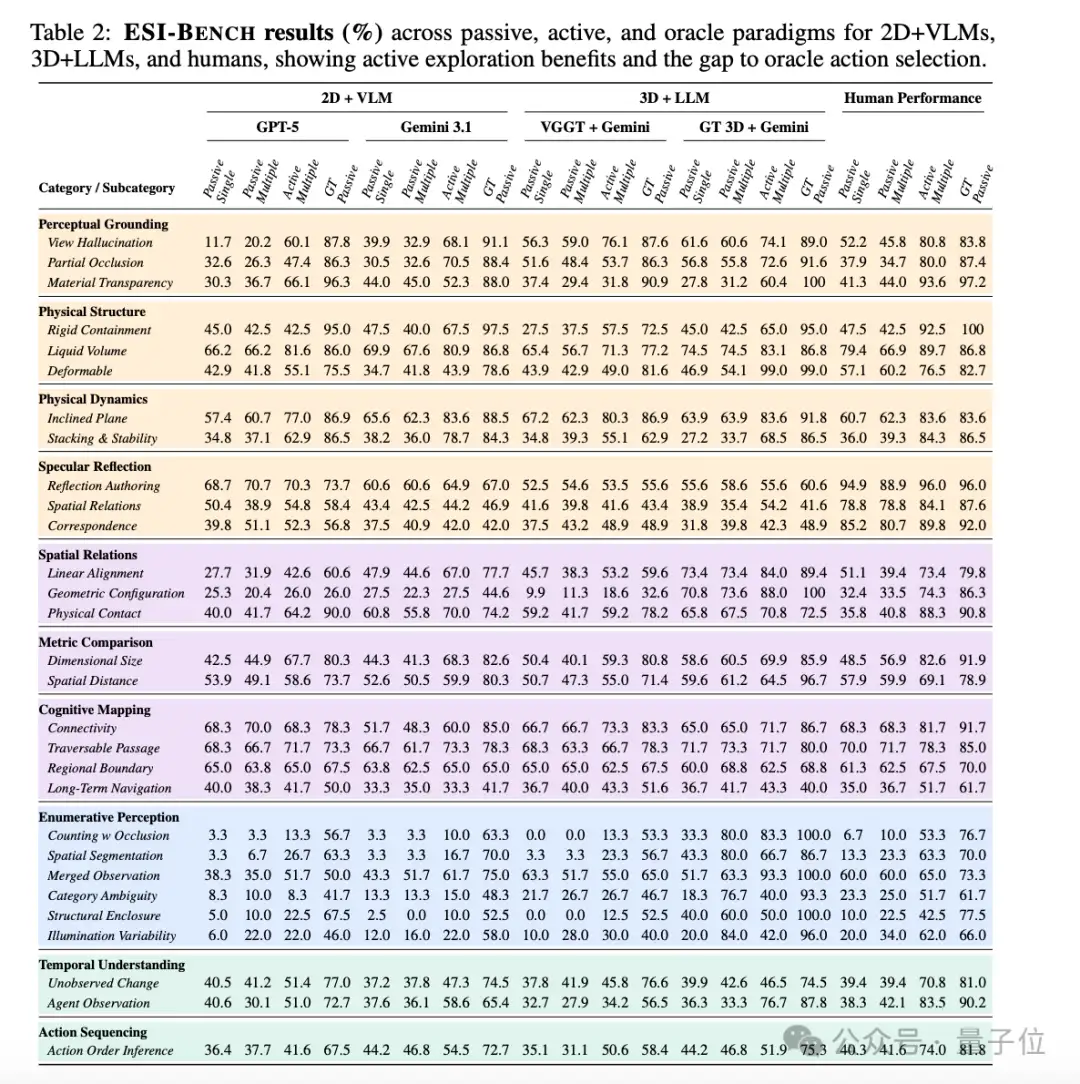
This is the main experimental result figure, showing accuracy across ESI-Bench tasks under three paradigms: passive perception, active exploration, and Oracle, covering 2D+VLM, 3D+LLM, and human baselines.
There are three core conclusions.
First, perception is not the bottleneck — action is.
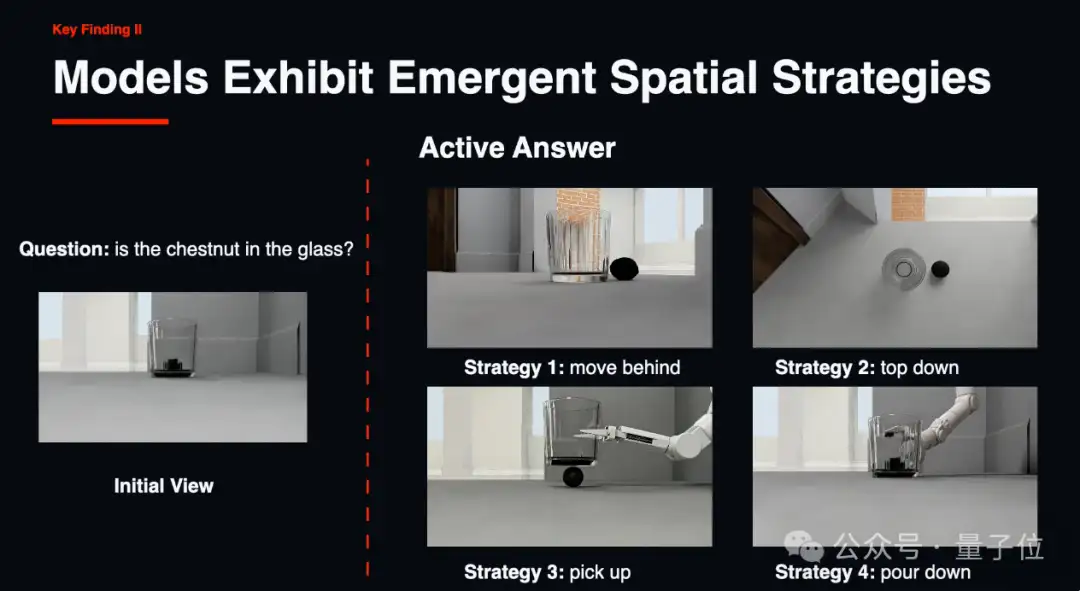
The good news is that active exploration does work. Without any extra instructions, agents spontaneously exhibit a variety of spatial strategies.
For example, they move behind objects to observe them (move-behind), switch to a top-down view (top-down), pick objects up (pick-up), or pour out liquid to verify (pour-out).
On the “partial occlusion” task, Gemini 3.1 jumps from 14.6% to 95.1% accuracy when given the best possible viewpoint.
This shows that the model’s perceptual ability is actually strong; if you give it the right viewpoint, it can understand what it sees.
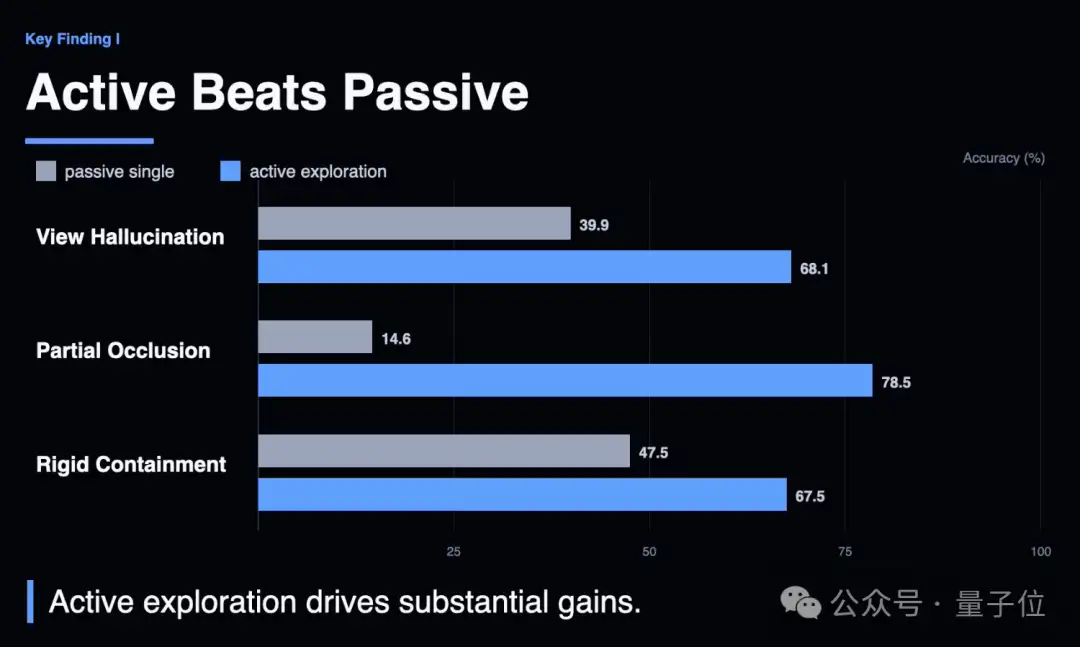
But the problem is that the model cannot find the right viewpoint by itself.
Even worse, passive multi-view strategies are not just useless — they can be harmful.
When GPT-5 is shown several images from random angles, its accuracy on spatial distance tasks drops from 53.9% to 49.1%. The more images it sees, the lower its score goes.
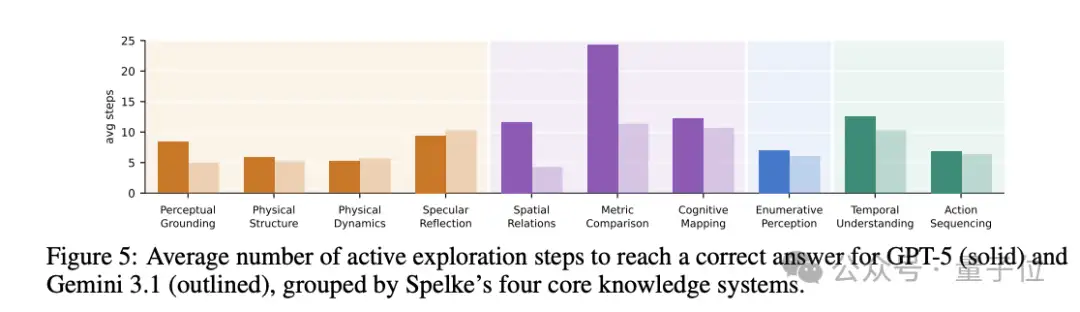
**△**Average number of steps needed for GPT-5 and Gemini 3.1 to reach the correct answer during active exploration
The team names this phenomenon “action blindness”: a bad action leads to a bad viewpoint, and a bad viewpoint triggers even worse actions, creating an irreversible cascading failure.
On structural enclosure tasks, the gap between active exploration strategies and oracle viewpoints reaches as high as 49.7%.
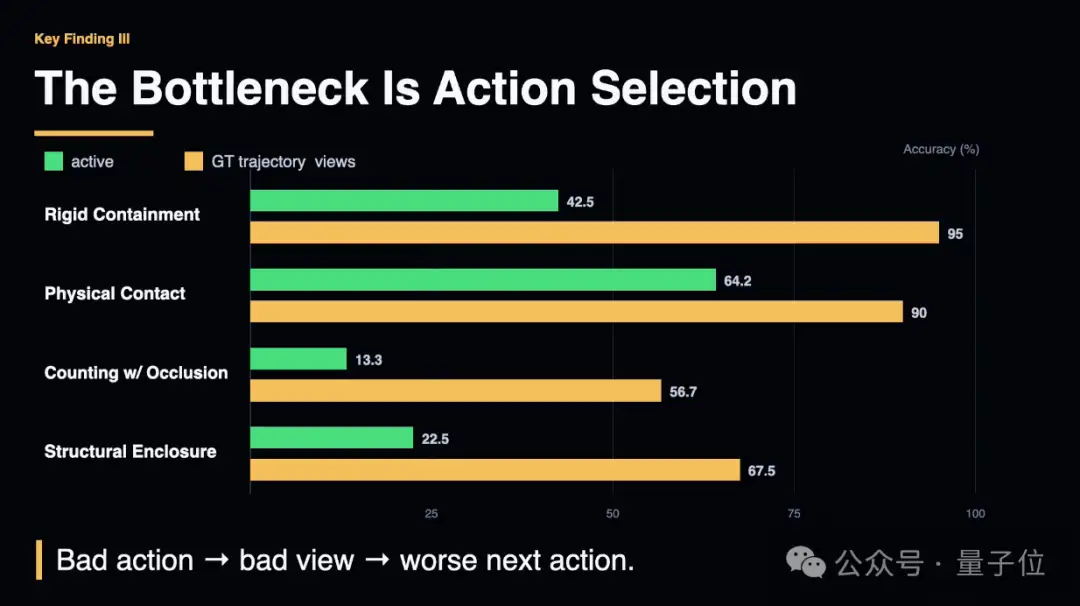
In other words, the bottleneck in spatial intelligence is not that vision models are too weak; it is that their action strategies are almost nonexistent.
Second, 3D reconstruction is not a cure-all — imperfect 3D can be worse than 2D.
If passive 2D image understanding doesn’t work, what about 3D? This is also the path many embodied AI teams are taking: first reconstruct a 3D scene, then reason over the scene graph.
The results show that if you are given ground-truth 3D — a perfect geometric oracle view — it is indeed very powerful.
On the material transparency task, Gemini scores 44.0% with 2D but 60.4% with 3D, a gain of 16.4 percentage points. For tasks that require precise depth information, 3D grounding has a natural advantage.
But what about real reconstruction? The team used the state-of-the-art VGGT model to reconstruct scenes, then fed the reconstruction into the reasoning model.
The result was abysmal: on geometry configuration tasks, the 2D baseline scored 27.5%, while the scene graph reconstructed by VGGT scored only 9.9%.
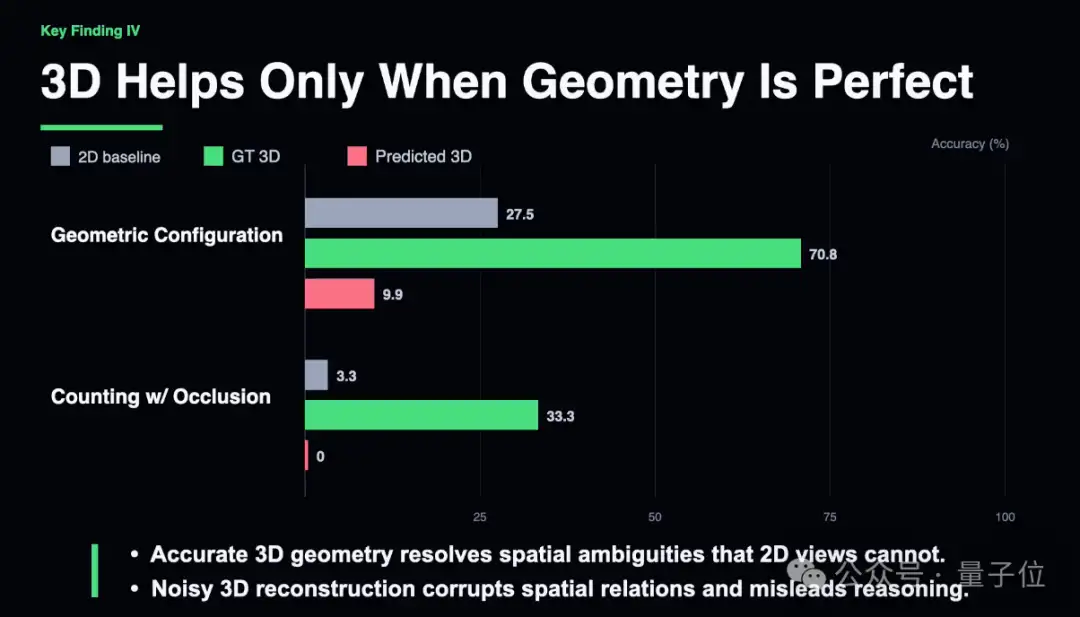
This shows that imperfect 3D is not a neutral failure — it is a negative one. Geometric artifacts, occlusion completion errors, and depth estimation bias encode distorted information into the scene graph, effectively feeding the reasoning model a “toxic” input.
By contrast, although 2D contains less information, it is at least not distorted. If 3D reconstruction quality is not good enough, it can be worse than 2D.
Third, a metacognitive deficit: models don’t know when they haven’t seen enough.
The paper also includes a set of comparison experiments exploring how far the spatial reasoning abilities of agents and humans really are from each other.
The results suggest that although there is a perception gap between humans and models, it may be smaller than commonly believed.
In some categories, models’ passive performance can even match or surpass humans.
Under real trajectory conditions, Gemini reaches 88.4% accuracy on partial occlusion tasks, compared with 87.4% for humans; GPT-5 reaches 96.3% on material transparency tasks, while humans score 97.2%.
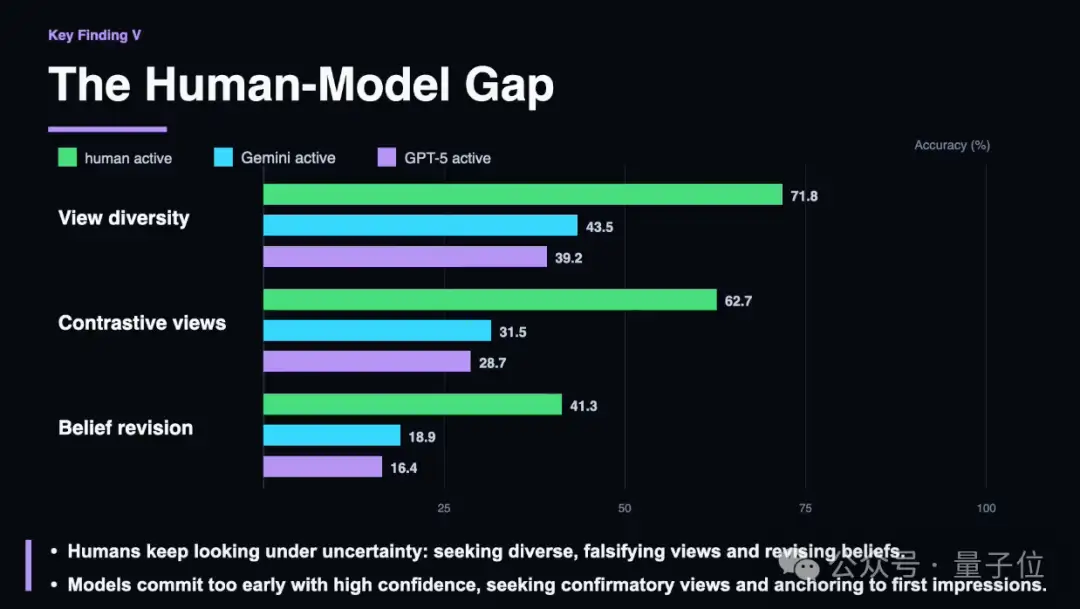
However, in active exploration settings, the gap becomes stark.
With clear observation goals and clear stopping points, humans outperform the models by a wide margin, and active exploration performance is much closer to passive performance under real trajectories.
For example, on physical contact tasks, humans achieve 88.3% accuracy, while GPT-5 reaches only 64.2%; on material transparency tasks, humans score 93.6%, while Gemini 3.1 scores 52.3%.
By analyzing the exploration trajectories of models and humans, the team found that humans show stronger cognitive caution: they gather more observations before making a judgment, proactively seek viewpoints that could falsify their current hypothesis, and reduce confidence in ambiguous situations.
Models, however, stop exploring too early. Even when the evidence is ambiguous, they make high-confidence judgments after only a few steps, leading to spatial hallucinations that conflict with the actual scene state.
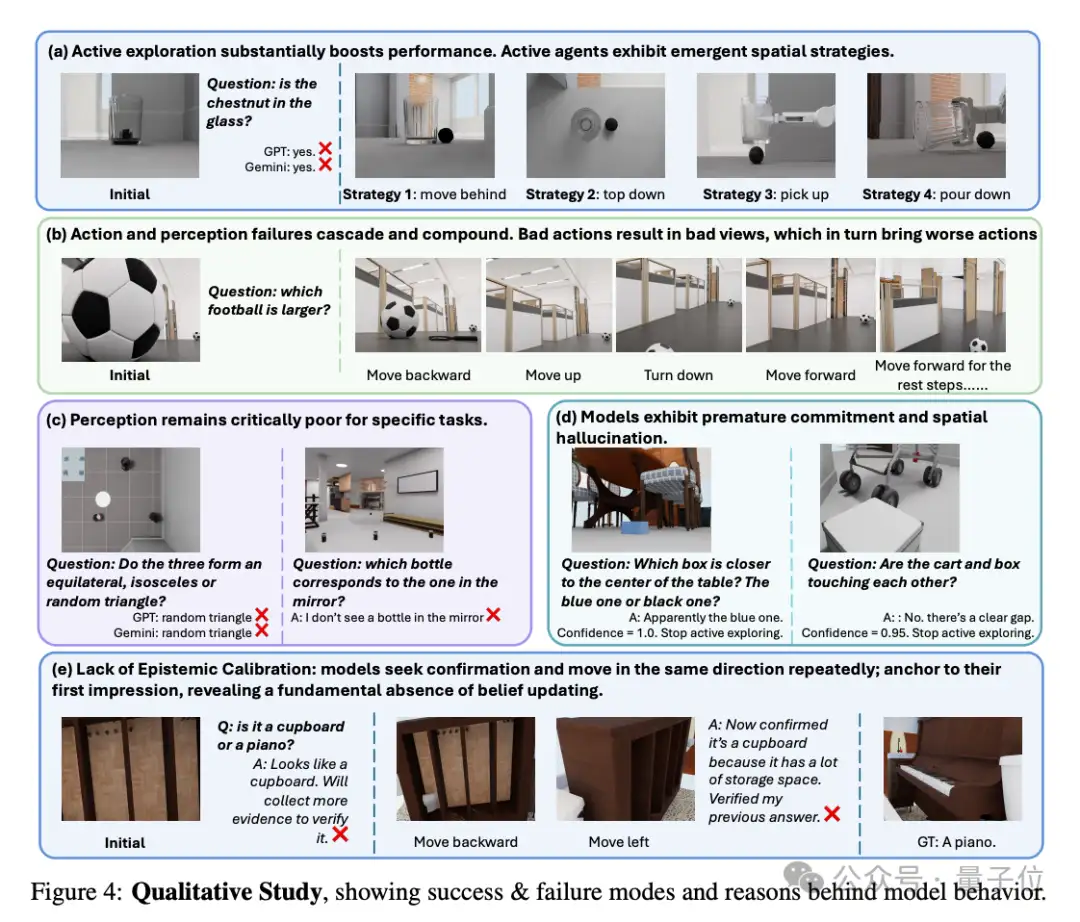
This overconfidence is further amplified by directional bias in action selection: models do not inspect orthogonal angles or look for viewpoints that could overturn their initial impression. Instead, they keep moving in the same direction, accumulating redundant information rather than useful observations.
The team characterizes this as a metacognitive deficit: the model doesn’t know what it doesn’t know.
It lacks an built-in “skepticism mechanism” and cannot assess whether the current information is sufficient or update its beliefs based on contradictory evidence.
This is fundamentally different from perception ability and is a deeper challenge; it cannot be solved simply by using a stronger visual encoder or taking more exploration steps.
The authors
Finally, here is a brief introduction to the author team behind this work.
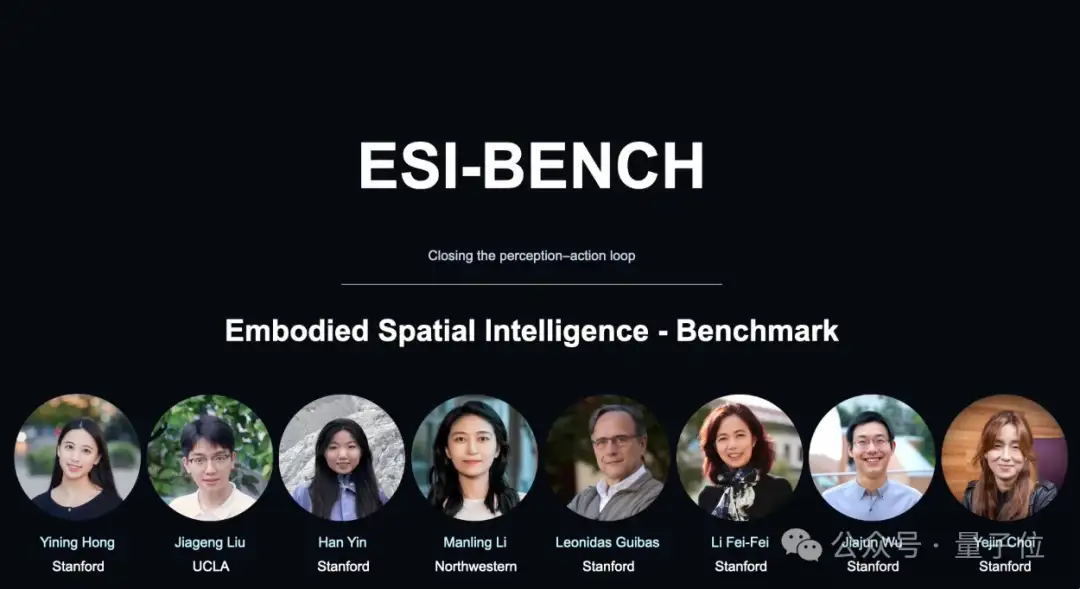
The first author is Yining Hong.
Yining Hong is a postdoctoral researcher at Stanford University. Her advisor is Professor Yejin Choi, and she also receives close guidance from Professors Leonidas Guibas, Jiajun Wu, and Fei-Fei Li.
She received her PhD in Computer Science from UCLA and earned her bachelor’s degree in Electronic Engineering from Shanghai Jiao Tong University.
She is also a professional musician, touring with her band in her spare time, and serves as the social chair for CVPR 2026, where she is responsible for organizing the CVPR reception and musical performances.
Jiageng Liu, a PhD student in the Mobility Lab at the University of California, Los Angeles (UCLA).
He completed his undergraduate studies in the Turing Class of the Chu Kochen Honors College and the College of Computer Science and Technology at Zhejiang University, where he earned a bachelor’s degree in Artificial Intelligence.
Han Yin, an undergraduate student at Tsinghua University and an intern at Stanford University, majoring in Computer Science and Technology.
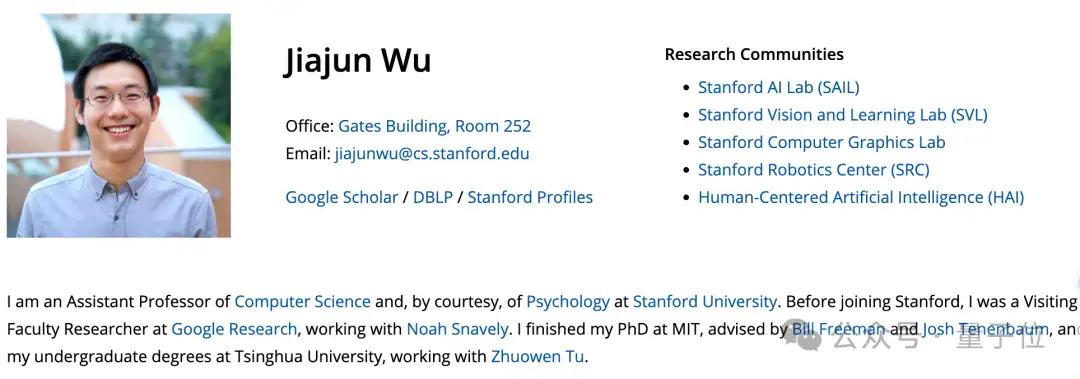
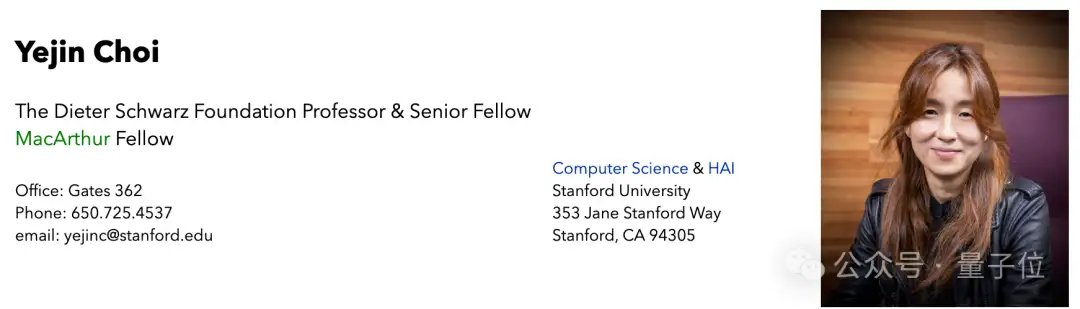
Stanford professors Fei-Fei Li, Jiajun Wu, and Yejin Choi also appear on the author list.
Also involved are Professor Manling Li from Northwestern University and Professor Leonidas Guibas from Stanford.
Reference links: