
Introduction to the Ettin Reranker Series
Published on May 19, 2026
TL;DR
Today I released 6 new Sentence Transformers CrossEncoder rerankers that reach state-of-the-art performance at their respective scales. These models are built on the Ettin ModernBERT encoder, and I also released the data and full training recipe used to create them:
cross-encoder/ettin-reranker-17m-v1cross-encoder/ettin-reranker-32m-v1cross-encoder/ettin-reranker-68m-v1cross-encoder/ettin-reranker-150m-v1cross-encoder/ettin-reranker-400m-v1cross-encoder/ettin-reranker-1b-v1
These models were trained with a distillation recipe: pointwise MSE (mean squared error) training on the scores from mixedbread-ai/mxbai-rerank-large-v2 over cross-encoder/ettin-reranker-v1-data, a subset of lightonai/embeddings-pre-training mixed with a reranking subset of lightonai/embeddings-fine-tuning.
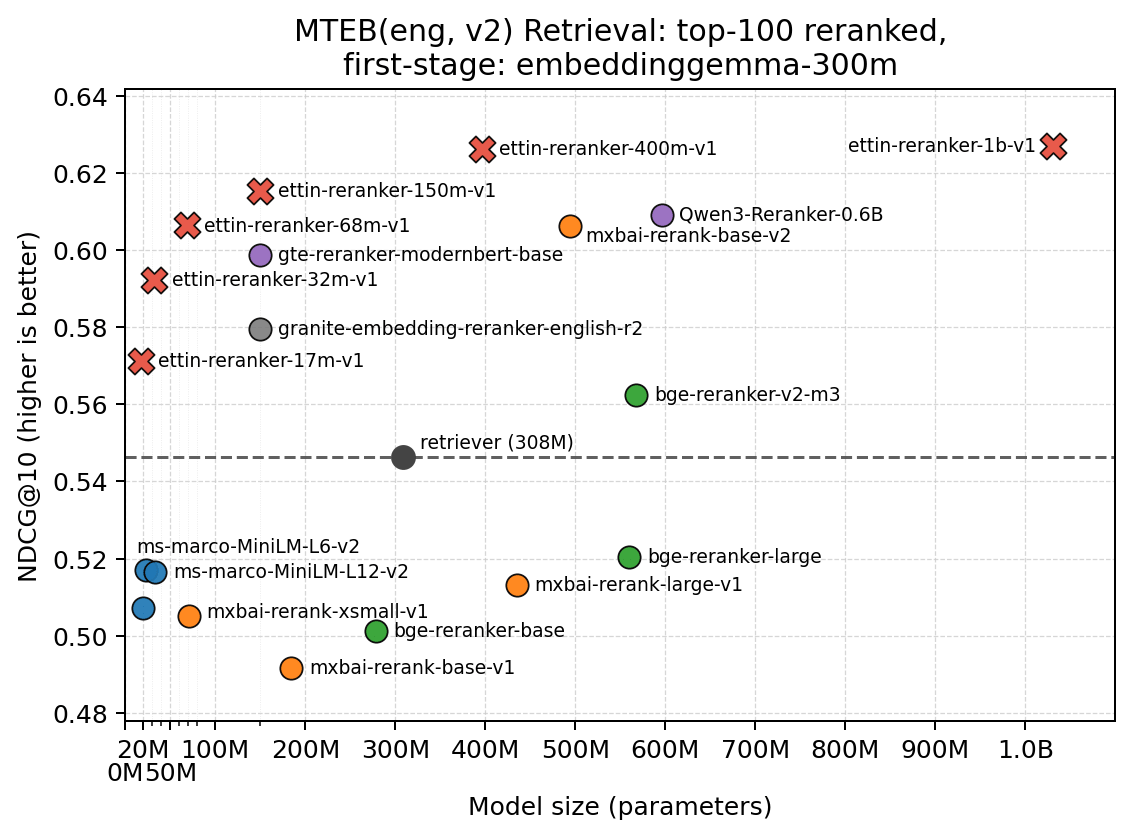
Our 6 rerankers paired with google/embeddinggemma-300m on MTEB(eng, v2) Retrieval. See Results for more embedding-model combinations.
If you’re new to rerankers and want to understand why you’d use one, jump to What is a reranker, and why pair one with an embedder?. If you just want to use the models, jump to Usage. If you want to train your own, jump to Training.
I kicked off the training recipe below using the new
train-sentence-transformersAgent Skill in Sentence Transformers v5.5.0. You can install it withhf skills add train-sentence-transformers [--global] [--claude]and let your AI coding agent (Claude Code, Codex, Cursor, Gemini CLI, etc.) fine-tuneSentenceTransformer,CrossEncoder, orSparseEncodermodels on your data.