
Simon Willison’s Blog
Gemini 3.5 Flash: More Expensive, but Google Plans to Use It Everywhere
May 19, 2026
Today at Google I/O, Google announced Gemini 3.5 Flash. This time, it skipped the -preview suffix and went straight to general availability, and Google appears to be rolling it out across many key products:
3.5 Flash is available today to billions of people around the world:
- All users can use it through the Gemini app and AI Mode in Google Search
- Developers can use it in our agent-first development platform Google Antigravity, as well as in Gemini API in Google AI Studio and Android Studio
- Enterprise users can use it in Gemini Enterprise Agent Platform and Gemini Enterprise
As is often the case with Gemini, the most interesting details are tucked away in the developer docs What’s new in Gemini 3.5 Flash. It broadly has the same set of platform capabilities as the earlier Gemini 3.x models, except for computer use. The model ID is gemini-3.5-flash. The knowledge cutoff is January 2025, and it supports 1,048,576 input tokens and up to 65,536 output tokens.
Google is also pushing a new Interactions API, currently in beta. It looks to me a lot like the pattern introduced by OpenAI Responses, especially the server-side history management.
The price has gone up
Gemini 3.5 Flash comes with a noticeable price increase. Previously, the “Flash” family consisted of Gemini 3 Flash Preview and Gemini 3.1 Flash-Lite. The new 3.5 Flash costs 3 times as much as 3 Flash Preview, and 6 times as much as 3.1 Flash-Lite (see the price comparison here).
At $1.50 per million input tokens and $9 per million output tokens, it is already close to Google’s Gemini 3.1 Pro, which is priced at $2 and $12 respectively.
The Gemini team has promised that 3.5 Pro will arrive “next month” — presumably at an even higher price.
This fits a broader trend: OpenAI’s GPT-5.5 is priced at 2x GPT-5.4, and Claude Opus 4.7, after accounting for the new tokenizer, is priced at about 1.46x 4.6.
Given the price increase, it’s notable that Google is still deploying this across so many consumer-facing free products. It feels like all three major AI labs are starting to test how much API customers are willing to pay.
Artificial Analysis publishes the cost of running their proprietary benchmark across models, which is a useful way to factor in things like tokenization and increases in reasoning tokens. Here are some numbers worth comparing:
- Gemini 3.5 Flash (high):$1,551.60
- Gemini 3.1 Pro Preview:$892.28
- Gemini 3 Flash Preview (Reasoning):$278.26
- Gemini 3.1 Flash-Lite Preview:$93.60
Running the 3.5 Flash (high) benchmark is significantly more expensive than 3.1 Pro Preview!
Here are some numbers from other vendors:
- Claude Opus 4.7 (Adaptive Reasoning, Max Effort):$5,117.14
- Claude Opus 4.7 (Non-reasoning, High Effort):$1,217.23
- GPT-5.5 (xhigh):$3,357.00
- GPT-5.5 (medium):$1,199.14
A pelican riding a bicycle
I ran a test of a Gemini API request for “generate a pelican riding a bicycle”, and it returned this very information-dense pelican:
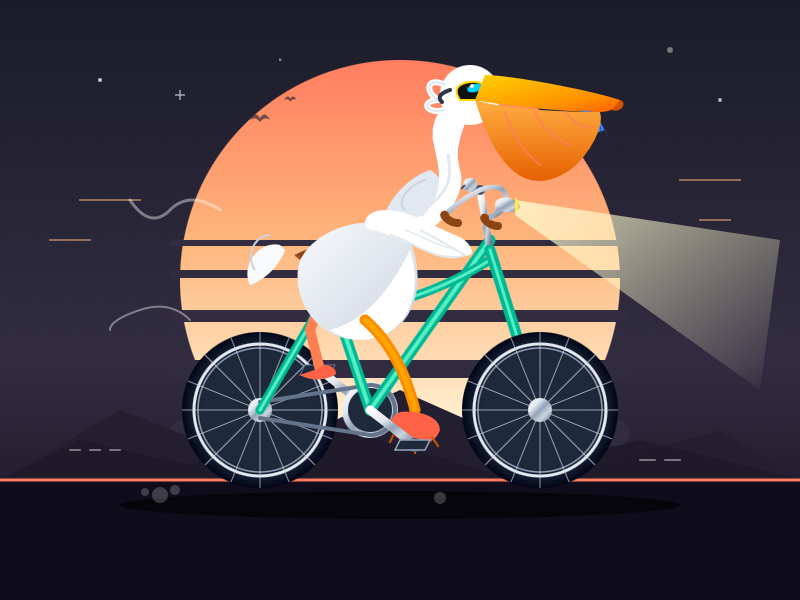
As the code comment notes: <!-- Pelican Eye / Sunglasses (Cool Retro Aviators) -->
Hacker News user hedgehog said:
This pelican looks like it’s at a crypto conference in Miami.
This request used 11 input tokens and 14,403 output tokens, for a total cost of less than 13 cents.
Published May 19, 2026 at 10:40 PM · Follow me on Mastodon, Bluesky, Twitter, or subscribe to my newsletter
More recent articles
- The LLM Six-Month Review: A Five-Minute Tour - May 19, 2026
- Notes on the xAI/Anthropic data center deal - May 7, 2026
This article is Simon Willison’s Gemini 3.5 Flash: More Expensive, but Google Plans to Use It Everywhere, published on May 19, 2026.
Previous: The LLM Six-Month Review: A Five-Minute Tour
Monthly Briefing
Sponsor me for $10/month and get a curated email digest covering the month’s most important LLM developments.
Pay me to send you fewer emails!