
By Stephan Rabanser, Sayash Kapoor, and Arvind Narayanan
Suppose you hear about a new AI agent that promises to boost productivity by shopping for you, writing code, sending emails, or handling customer inquiries. Should you trust it? Can this agent really do the job reliably? After all, failures by agents are easy to find..
Surprisingly, despite the well-known unreliability of AI agents, the AI industry currently has neither good tools for measuring reliability nor even a good definition of “reliability.”
Arvind and Sayash have been thinking about this problem for a long time. Last fall, Princeton postdoc Stephan Rabanser joined us; his doctoral research focused on reliability in simpler, more traditional AI systems. We recruited several other independent researchers and published what we hope is a comprehensive study of reliability measurement. Our draft paper is called Towards a Science of AI Agent Reliability.
We drew on lessons from fields such as nuclear safety and aviation safety. We broke reliability down into 12 distinct dimensions. After evaluating 14 models on two complementary benchmarks, we found that the rapid capability gains of the past two years have translated into only modest improvements in reliability. An interactive dashboard is available here.
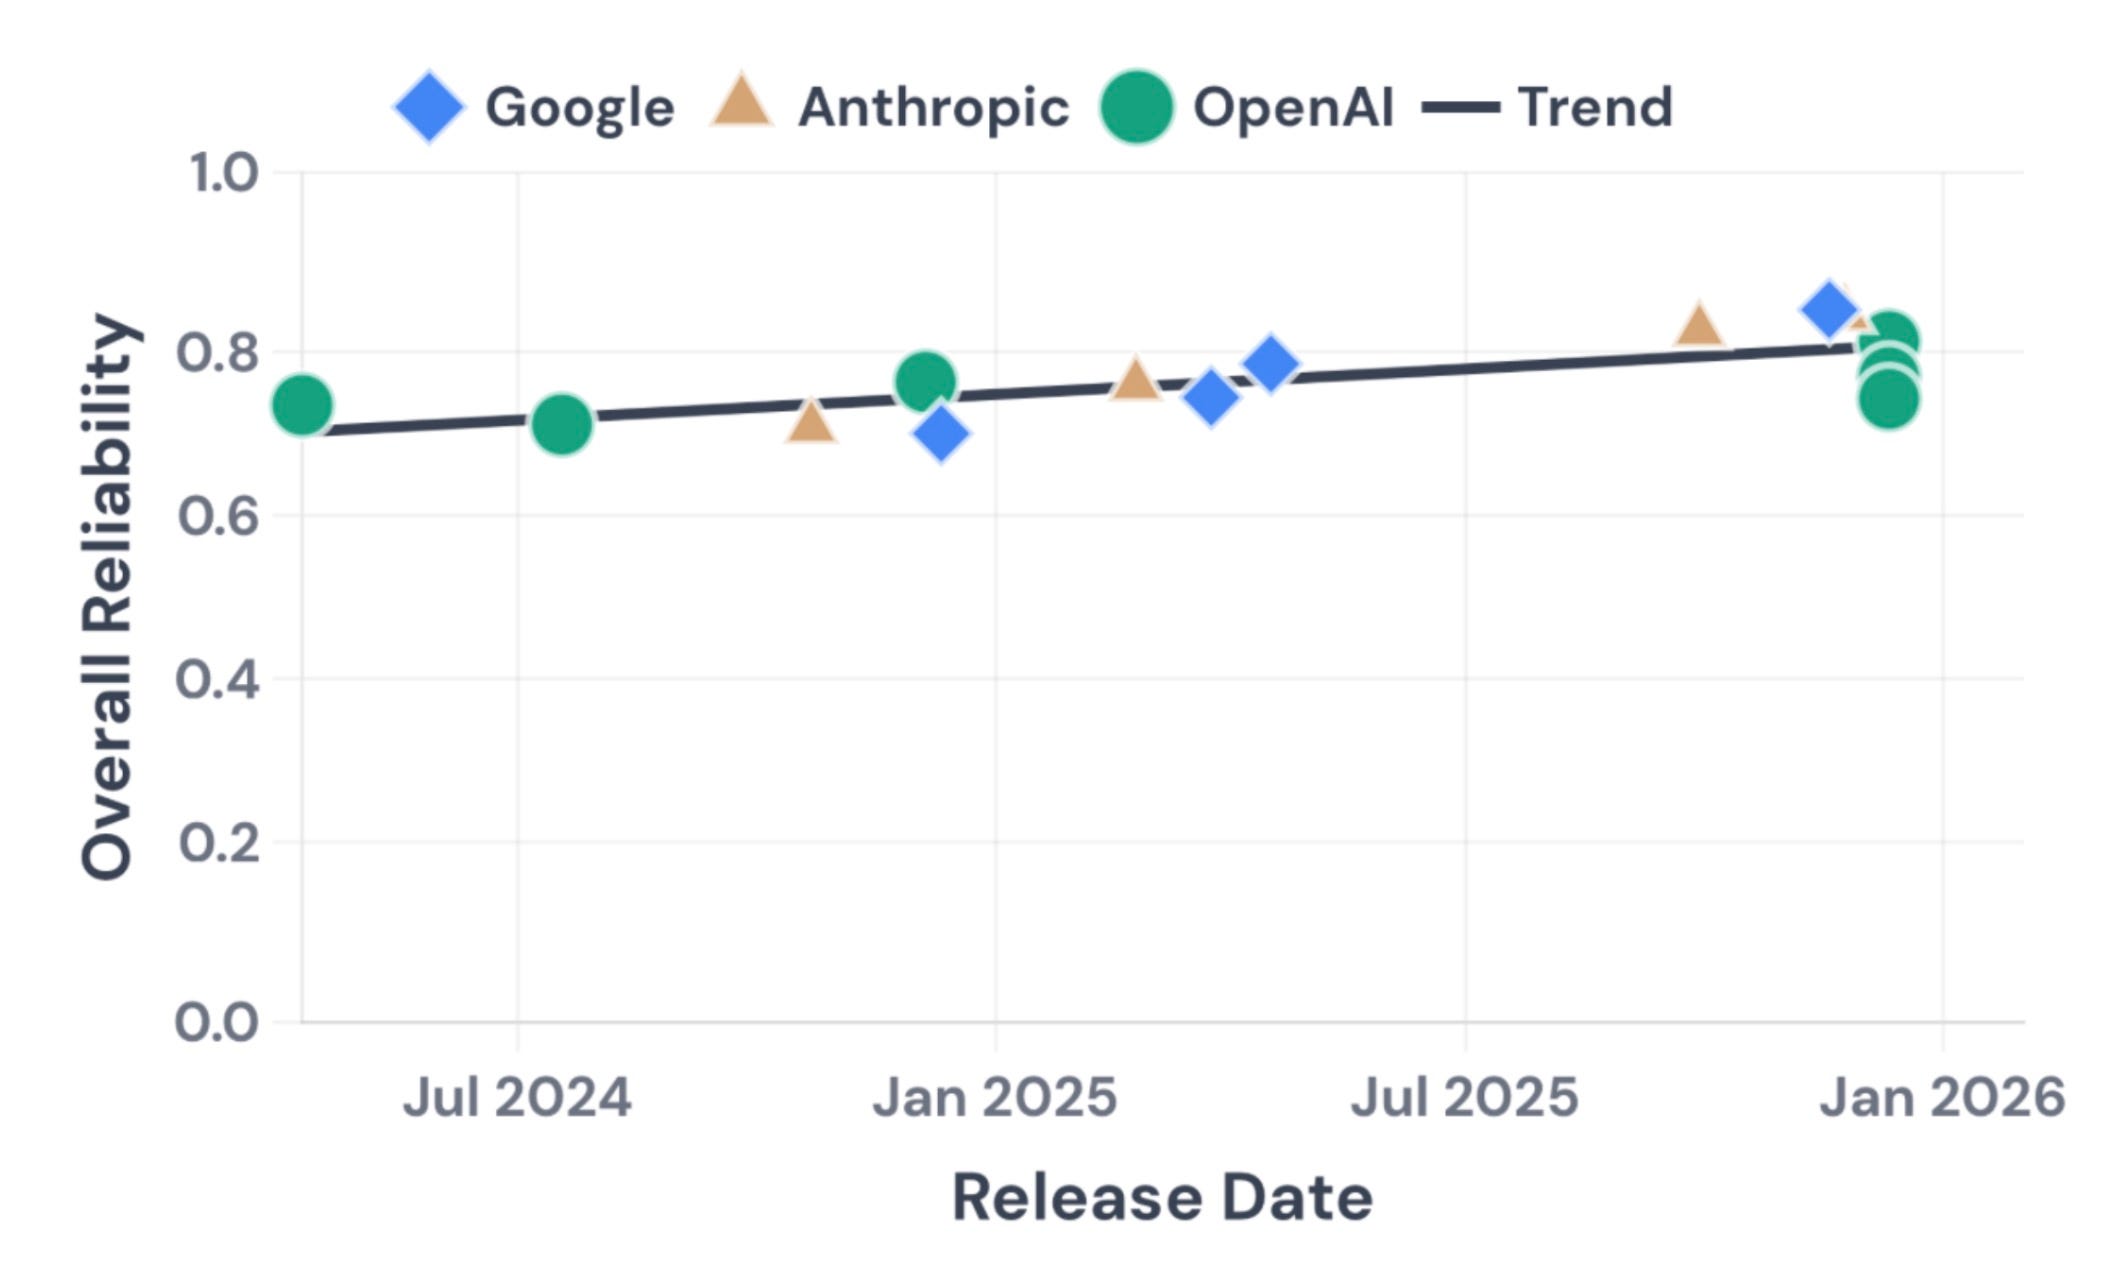
Although our current findings are still preliminary, we hope they help explain the confusion many in the industry feel: why the economic impact of AI agents is progressing so slowly despite their exceptional performance on capability benchmarks.1 To help the community track reliability systematically, we plan to launch an AI agent “reliability index.” We hope this will encourage researchers and industry to invest more effort in improving reliability.